tools
vLLM Review 2026 — The Best Open-Source LLM Serving Engine
vLLM is the production standard for serving open-source LLMs. PagedAttention delivers 10-24x throughput vs naive inference. OpenAI-compatible API, 50+ models, free Apache 2.0.
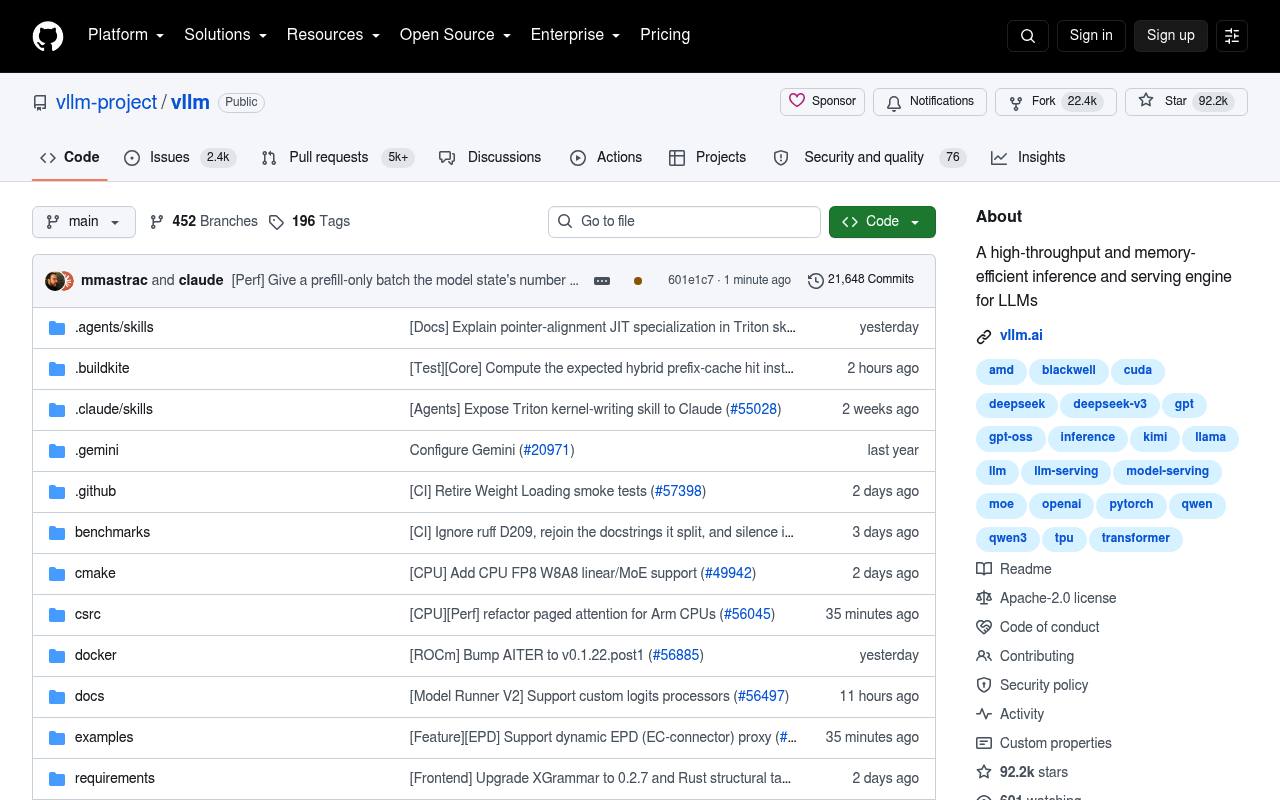
vLLM runs open-source language, multimodal, embedding, retrieval, reward, and classification models for inference and production serving. It provides an OpenAI-compatible API, plus Anthropic Messages API and gRPC support.
It is used by developers, research teams, and infrastructure operators deploying models on GPUs, CPUs, and other accelerators. vLLM is software rather than a hosted model service; operators provide the hardware and pay any related infrastructure costs.
Features
- Continuous batching, chunked prefill, and prefix caching
- PagedAttention for key-value memory management
- OpenAI-compatible API server, plus Anthropic Messages API and gRPC support
- Tensor, pipeline, data, expert, and context parallelism
- Quantization with FP8, INT8, INT4, GPTQ/AWQ, GGUF, and related formats
- Speculative decoding with n-gram, suffix, EAGLE, and DFlash
- Support for NVIDIA, AMD, Intel GPUs and x86, ARM, and PowerPC CPUs
- Apache-2.0 license
Use cases
- Serve open-source language models behind an application API
- Run high-throughput batch inference for production workloads
- Deploy multimodal, embedding, retrieval, reward, or classification models
- Reduce GPU memory use with quantization and prefix caching
- Distribute inference across multiple accelerators
- Integrate model serving with OpenAI-compatible clients
Pros
Cons
Latest updates
- v0.33.0 (v0.33.0)
Added support for listed models, upgraded to PyTorch 2.14.0, and dropped CUDA 12.9.
- v0.33.0rc2: [ROCm][Bugfix] Skip AITER tuned GEMM when M*N >= 2^31 on gfx950 (#64567) (v0.33.0rc2)
Skip AITER tuned GEMM when M*N >= 2^31 on gfx950.
- v0.33.0rc0 (v0.33.0rc0)
Skip adaptive verification cost profiling in CUDA.
- v0.32.0 (v0.32.0)
Added POST /v1/systemone for choice, noul, and score questions over structured state; it is served by default.
- v0.32.0rc3: [Bugfix] Fix NaN output of the Mamba2 chunk scan kernel on sm90 (#61718) (v0.32.0rc3)
Fixed NaN output from the Mamba2 chunk scan kernel on sm90.
Capabilities
- Runs commands — “vllm download-kernels # precompiled kernels for faster startup” source
- Command line — “vllm download-kernels # precompiled kernels for faster startup” source
- Choice of models — “vLLM seamlessly supports 200+ model architectures on Hugging Face, including:” source
- Self-hosted — “Install vLLM with uv (recommended) or pip :” source
- API — “OpenAI-compatible API server, plus Anthropic Messages API and gRPC support” source
- Runs models for you — “A high-throughput and memory-efficient inference and serving engine for LLMs” source
Get it
Pricing
- Starting price
- $4/user/mo
- Prices checked
- 2026-11-06
Free
Free
- Unlimited public/private repositories
- Dependabot security and version updates
- 2,000 CI/CD minutes/month
- 500MB of Packages storage
- Issues & Projects
- Community support
Team
- $ 4 USD per user / month
- Access to GitHub Codespaces
- Repository rules
- Multiple reviewers in pull requests
- Draft pull requests
- Code owners
- Required reviewers
Enterprise
- $ 21 USD per user / month
- GitHub Copilot access
- Agent governance
- Data residency
- Enterprise Managed Users
- User provisioning through SCIM
- Enterprise Account to centrally manage multiple organizations