tools
Ursa
Ursa is Speechmatics’ speech-to-text model family for transcribing live and recorded audio across languages, accents, and speakers.
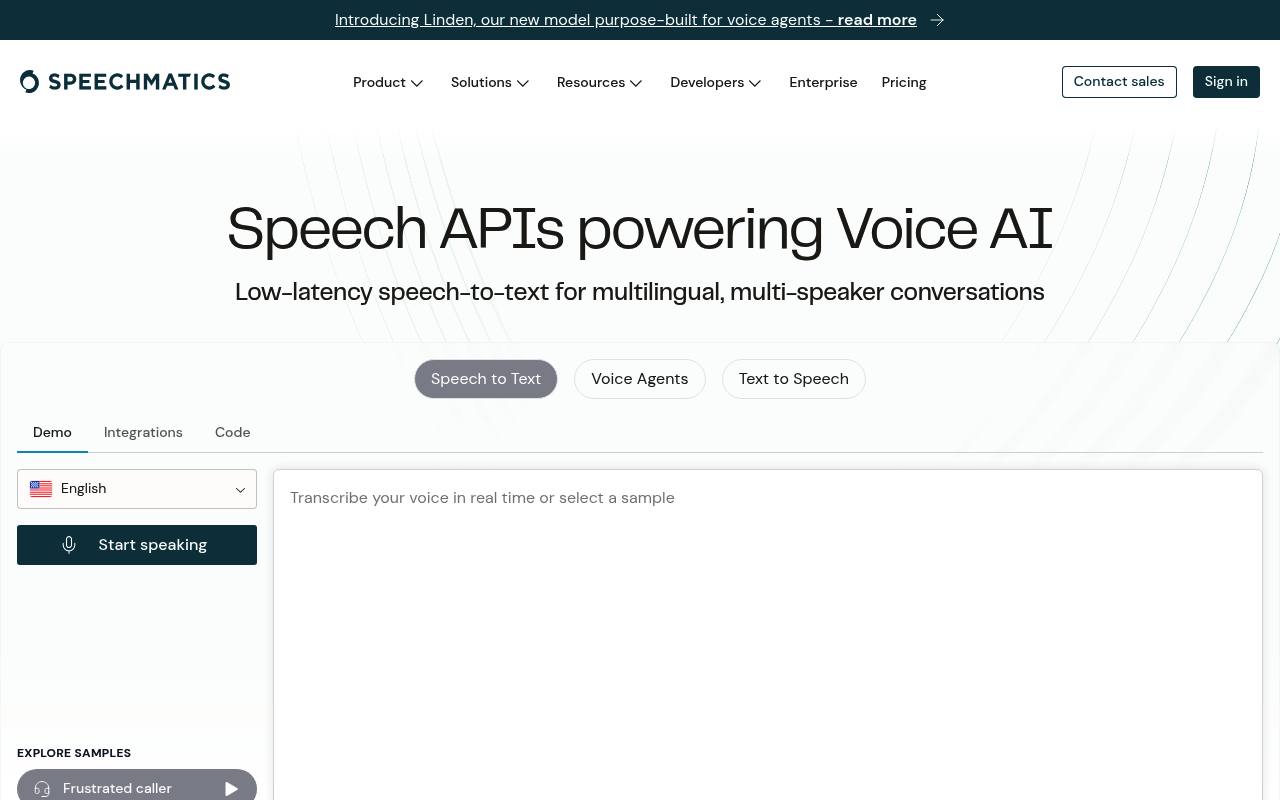
Ursa converts speech into text for applications such as captions, search, analytics, voice agents, legal transcription, and healthcare documentation. It supports batch and real-time transcription, speaker information, timestamps, formatting, and translation workflows.
Speechmatics released Ursa 2 as its next-generation model in October 2024. Current Speechmatics pricing is usage-based and is listed by API model and processing mode rather than by the Ursa name; translation, summaries, chapters, sentiment, and topics cost extra.
Features
- Batch transcription for recorded audio and video
- Real-time transcription with latency under one second
- Speech recognition across 55+ languages
- Speaker diarization for multi-speaker conversations
- Custom dictionaries and vocabulary support
- Word-level timestamps and subtitle formatting
- Cloud, on-premises, container, and on-device deployment
- Translation, summaries, sentiment, topics, and audio events
Use cases
- Generate live captions for broadcasts, meetings, and events
- Transcribe calls for contact-center analytics
- Build multilingual voice agents with speech-to-text APIs
- Create clinical, legal, or financial transcripts
- Search and index large audio and video archives
- Produce translated subtitles and accessible media
Pros
Cons
Latest updates
- 2026.11.03 Realtime SaaS (2026.11.03)
Realtime sessions are now less likely to become unresponsive when transcription falls behind the audio being sent.
- 2026.10.30 Batch SaaS (2026.10.30)
Fixed a case where a valid WAV file could be misidentified as another format during audio preprocessing.
- 2026.10.29 Agent STT SaaS (2026.10.29)
Fixed an issue in vad turn detection mode where short words could occasionally be missing from the transcript.
- 2026.10.29 Batch SaaS (2026.10.29)
Fixed a case where a valid WAV file could be misidentified as another format during audio preprocessing.
- 2026.10.27 Realtime SaaS (2026.10.27)
Oak 1, a medical model, is now available for real-time transcription.
Capabilities
- Text to speech — “Natural, low-latency speech synthesis for Voice AI use cases.” source
- Speech to text — “Real-time speech-to-text in 350ms” source
- Dubbing — “Real-time translation of live events or media.” source
- Many languages — “55+ languages, one model” source
- API — “Speech-to-text API built for every language and accent” source
Get it
Pricing
- Starting price
- Free
- Prices checked
- 2026-11-06
Free
Free
- $100 in credits
- No card required
Pro
- Pre-recorded, Melia 1: $0.12 / hr
- Pre-recorded, Enhanced: $0.38 / hr
- Pre-recorded, Oak 1: $0.15 / hr
- Pre-recorded, Standard: $0.23 / hr
- Real-time, Melia 1: $0.20 / hr
- Real-time, Enhanced: $0.40 / hr
- Real-time, Oak 1: $0.23 / hr
- Real-time, Linden 1: $0.15 / hr
- Real-time, Standard: $0.23 / hr
- $0.011 per 1,000 characters
- Pay as you go, credit packs, or subscription
- Speech to Text usage-based pricing
- Text to Speech usage-based pricing
Enterprise
Price on request
- Dedicated CSM + Solutions Engineer
- Unlimited files per second
- Multi-region cloud deployment
- Contact sales