tools
llama.cpp
Open-source C/C++ software for running large language and vision-language models locally or in the cloud.
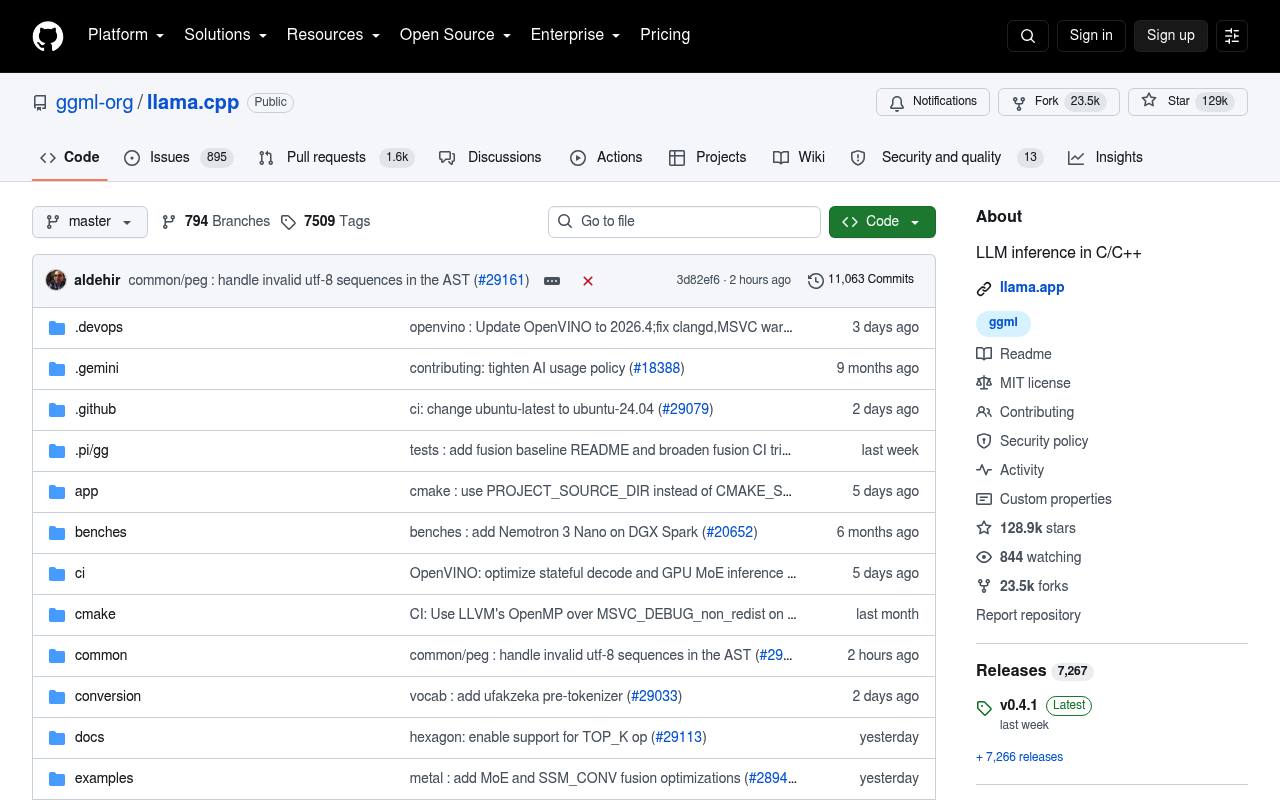
llama.cpp runs large language and vision-language models using C/C++ on CPUs, GPUs, mobile devices, and other hardware. It supports command-line tools, quantization, hybrid CPU/GPU inference, and multiple hardware backends.
Developers use it to run models locally, build applications, or launch an OpenAI-compatible API server. The project is software rather than a hosted model service; users provide models and computing hardware separately.
Features
- Runs LLM and VLM inference in C/C++
- Provides 1.5-bit through 8-bit integer quantization
- Supports CPU+GPU hybrid inference
- Includes command-line tools and a server
- Offers an OpenAI-compatible API server
- Supports CUDA, HIP, Metal, Vulkan, SYCL, OpenCL, and WebGPU
- Provides pre-built binaries and Docker installation
- MIT License
Use cases
- Run language models locally on a laptop or workstation
- Serve models through an OpenAI-compatible API
- Deploy inference across CPU, GPU, mobile, and embedded hardware
- Reduce model memory use with quantization
- Build C/C++ applications with the llama library
- Test models without sending prompts to a hosted service
Pros
Cons
Latest updates
- b12129
Re-enabled the large coopmat matmul configuration on AMD.
- b12127: metal: keep fusable node groups inside one command buffer (#31688)
Metal keeps fusable node groups within a single command buffer.
- b12126: qwen2 : add nvfp4 scales to build_ffn (#31657)
Added NVFP4 scales to Qwen2's build_ffn call.
- b12125
Enabled f32 and q5_k multi-column GEMV by default for Adreno X2.
- b12124
Added OpenCL support for non-contiguous sigmoid.
Capabilities
- Command line — “llama cli -hf ggml-org/Qwen3.5-0.8B-GGUF” source
- Choice of models — “Download and run a model directly from Hugging Face” source
- Self-hosted — “The main goal of llama.cpp is to enable LLM (and VLM) inference with minimal setup and state-of-the-art performance on a wide range of hardware - locally and in the cloud.” source
- API — “Launch OpenAI-compatible API server” source
Get it
Pricing
- Starting price
- $4/user/mo
- Prices checked
- 2026-11-05
Free
Free
- Unlimited public/private repositories
- Dependabot security and version updates
- 2,000 CI/CD minutes/month
- 500MB of Packages storage
- Issues & Projects
- Community support
Team
- $ 4 USD per user / month
- Access to GitHub Codespaces
- Repository rules
- Multiple reviewers in pull requests
- Draft pull requests
- Code owners
- Required reviewers
Enterprise
- $ 21 USD per user / month
- GitHub Copilot access
- Agent governance
- Data residency
- Enterprise Managed Users
- User provisioning through SCIM
- Enterprise Account to centrally manage multiple organizations