tools
DeepEval
Open-source framework for testing and evaluating LLM apps, agents, RAG pipelines, chatbots, and multimodal systems.
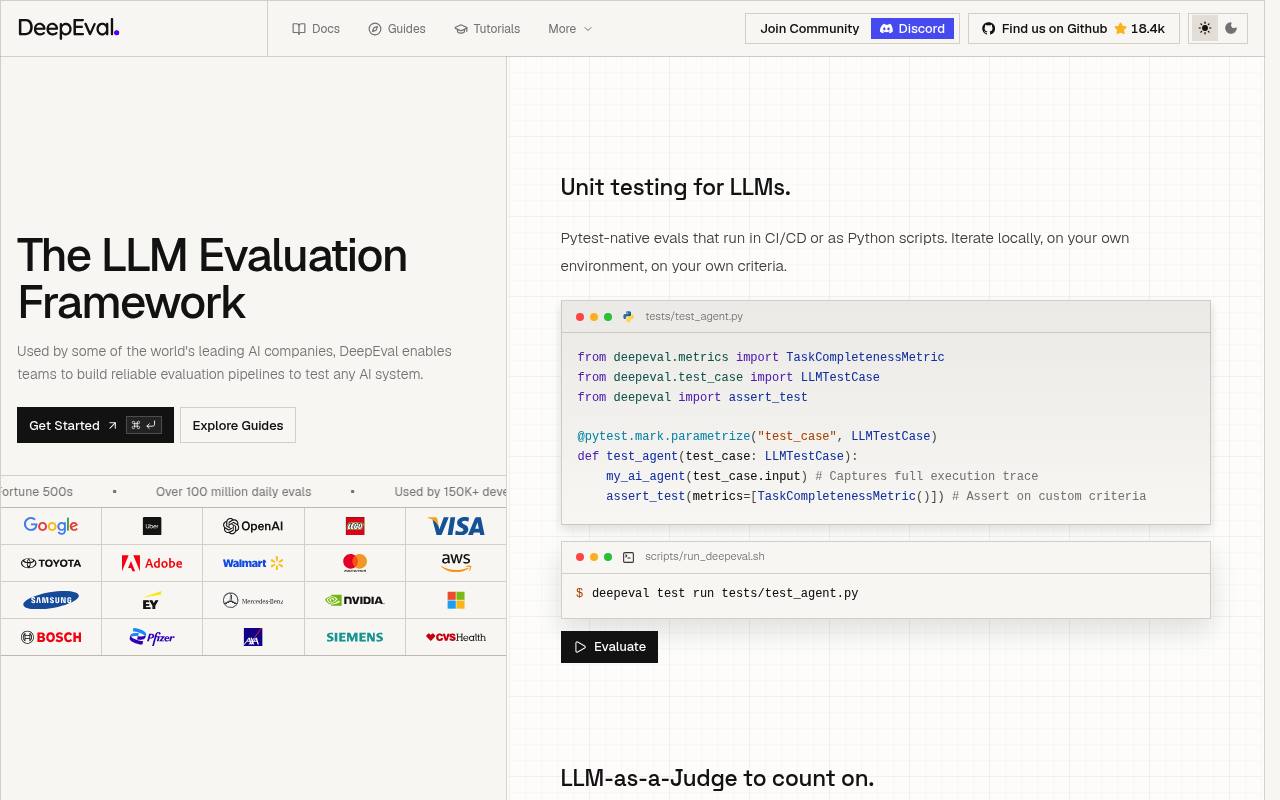
DeepEval runs LLM evaluations locally through Python or TypeScript, with Pytest-style assertions, 50+ metrics, tracing, synthetic dataset generation, conversation simulation, and component-level testing. It supports agents, RAG pipelines, chatbots, MCP systems, and custom workflows.
Developers use the CLI in local development and CI/CD, including with coding agents such as Cursor, Claude Code, and Codex. Shared dashboards, regression tracking, observability, production monitoring, and other hosted features are provided through the separate Confident AI platform and may cost extra.
Features
- Run LLM evaluations locally with Pytest-style assertions
- Use 50+ metrics for agents, RAG, safety, conversations, and multimodal apps
- Trace agent runs and evaluate complete trajectories or individual components
- Generate synthetic datasets and edge-case goldens
- Run evaluation suites from a CLI in local development or CI/CD
- Support Python and TypeScript SDKs
- Integrate with LangChain, LangGraph, OpenAI Agents, and OpenTelemetry
- Apache 2.0 licensed open-source framework
Use cases
- Test chatbot answers for relevance, correctness, safety, and faithfulness
- Evaluate RAG retrieval and generated responses against reference data
- Grade agent trajectories, tool calls, and component-level behavior
- Run regression tests on every pull request in CI/CD
- Generate synthetic test datasets from documents or application code
- Inspect local traces while iterating with a coding agent
Pros
Cons
Latest updates
- Setup wizard 0.1.0 (0.1.0)
Added transcription accuracy, voice transcript support, Claude Opus 5.5 registry entry, persona metadata/noise URL, and expectation verdicts.
- python-v4.3.0: new release (python-v4.3.0)
Released python-v4.3.0.
- python-v4.2.9: new release (python-v4.2.9)
Released python-v4.2.9.
- python-v4.2.8 (python-v4.2.8)
- typescript-v0.9.21 (typescript-v0.9.21)
Capabilities
- Runs commands — “Pytest-native evals that run in CI/CD or as Python scripts.” source
- Command line — “50+ metrics, one CLI” source
- Official SDKs — “Pytest-native evals that run in CI/CD or as Python scripts.” source
- Traces and evaluates — “DeepEval traces every step of your agent into something you can grade, and improve — visible in your terminal, testable in your runner, shippable in your next commit.” source
Get it
Pricing
- Starting price
- $200/mo
- Prices checked
- 2026-10-27
- Read
- by web search
DeepEval
Free
- Open-source LLM evaluation framework
- Apache 2.0 licensed
- Local and CI/CD test runner
Free
Free
- Full LLM unit and regression testing suite
- Evals in development and CI/CD
- LLM tracing
- Prompt versioning
- Datasets on the cloud
- Limited to 2 user seats, 1 project, 5 test runs per week, 1 GB-month of trace spans
Starter
- $200 / month
- Everything in Free, plus no-code AI evaluation workflows
- Custom evaluation metrics
- Online evals and classifications on live traffic
- Annotation queues & workflows
- Real-time alerting
- Unlimited user seats, 5 projects, 5 GB-months of trace spans then $1 per GB-month
Team
- $2,000 / month
- Everything in Starter, plus metric & dataset versioning
- Git-based prompt workflows
- Custom RBAC, SOC2, SSO
- Dedicated support channel
- Unlimited user seats and projects, 75 GB-months of trace spans then $1 per GB-month
Enterprise
Price on request
- Everything in Team, plus advanced AI authentication options
- Dedicated On-Prem Deployment, HIPAA
- Custom data residency
- Dedicated 24x7 technical support
- Unlimited user seats, projects, GB-months, online eval metric runs/month