tools
Cerebras Inference
Cerebras Inference provides API access to fast cloud inference for language and multimodal models.
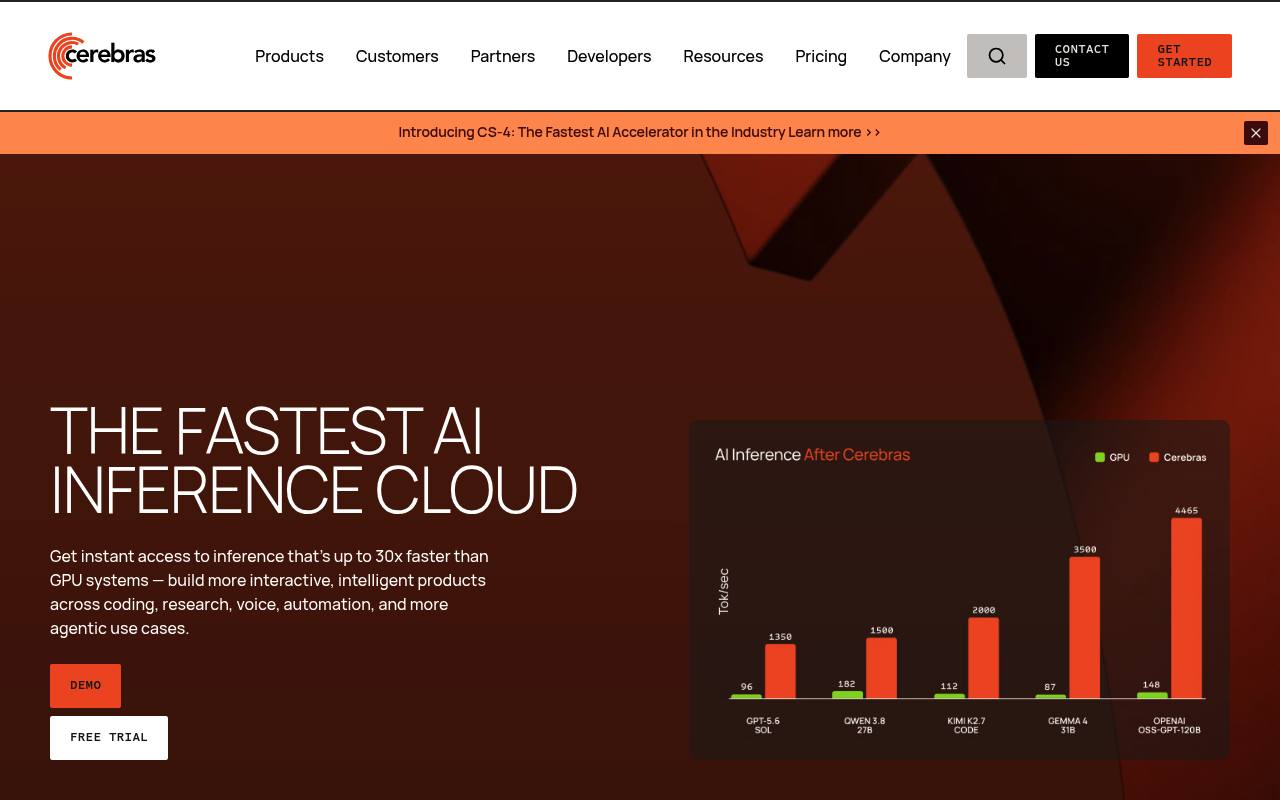
Cerebras Inference lets developers run supported AI models through an OpenAI-compatible API. It is intended for coding, research, voice, automation, agentic workflows, and other applications where response speed matters.
The service offers public endpoints, partner integrations, and dedicated enterprise endpoints. The product page advertises a free trial with $5 in credit; developer usage is pay per token, while enterprise access requires contacting Cerebras. Current pricing tier amounts were not rendered on the pricing page.
Features
- OpenAI API compatibility with two code changes
- Run supported language and multimodal models through cloud endpoints
- Public endpoints for models including GPT OSS 120B and Gemma 4 31B
- Dedicated enterprise endpoints for larger model families
- Multi-LoRA support for switching adapters per request
- Partner access through AWS, OpenRouter, Hugging Face, and Vercel
- Free trial with $5 in credit
Use cases
- Build responsive coding assistants and coding agents
- Run research and knowledge-work agents with lower response latency
- Create voice and real-time interactive applications
- Automate browser and computer-use workflows
- Serve specialized model behavior with multiple LoRA adapters
Pros
Cons
Latest updates
- Dedicated models and API guidance
Added Kimi K3, GLM 5.3 Flash, Inkling, Reflection AI Beam, and MiMo V2.6 Pro to the Dedicated model catalog.
- Clarified service-tier fallback and response behavior
Responses report the effective tier in service_tier; auto can fall back to flex and priority can retry at the request’s standard priority.
- Temporary increase to Qwen 3.8 27B total token rate limit
The Developer tier total token rate limit for qwen-3.8-27b is temporarily increased from 450K to 750K tokens per minute.
- Gemma 4 31B availability changes on public endpoints
gemma-4-31b is no longer available on Cerebras public endpoints. Gemma 4 31B remains available on Dedicated Endpoints.
- Qwen 3.8 27B available on public endpoints
qwen-3.8-27b is now available on Cerebras public endpoints.
Capabilities
Security
Pricing
- Prices checked
- 2026-10-24
Developer Tier
- $0.35/M tokens
- $0.75/M tokens
- $0.99/M tokens
- $1.49/M tokens
- Self-serve pay-as-you-go
- OPENAI GPT OSS 120B
- QWEN Qwen 3.8 27B