Research
WorldSR: Harnessing World Knowledge Search for Grounded Image Super-Resolution
WorldSR: Harnessing World Knowledge Search for Grounded Image Super-Resolution Overview Research area: Computer Vision — real-world image super-resolution (SR), retrieval-augmented generation, and MLL
- arXiv
- 2610.28423
- Published
- 2026-10-20
- Authors
- Junyuan Deng, Xinyi Wu, Zhenyao Wu, Song Wang, Yu Wang, Congchao Zhu
AI summary
WorldSR: Harnessing World Knowledge Search for Grounded Image Super-ResolutionOverview
- Research area: Computer Vision — real-world image super-resolution (SR), retrieval-augmented generation, and MLLM-driven agentic pipelines for low-level vision.
- Technical level: Advanced. The paper assumes familiarity with diffusion/DiT backbones, LoRA adaptation, reference-based super-resolution, image quality assessment metrics, and multimodal LLM tooling.
- Scope: A single paper introducing an agent-style super-resolution framework (WorldSR) that retrieves entity-aligned reference images from the web and a local knowledge base to constrain a multi-reference SR model, evaluated on five benchmarks against roughly a dozen baselines.
What This Paper Is About
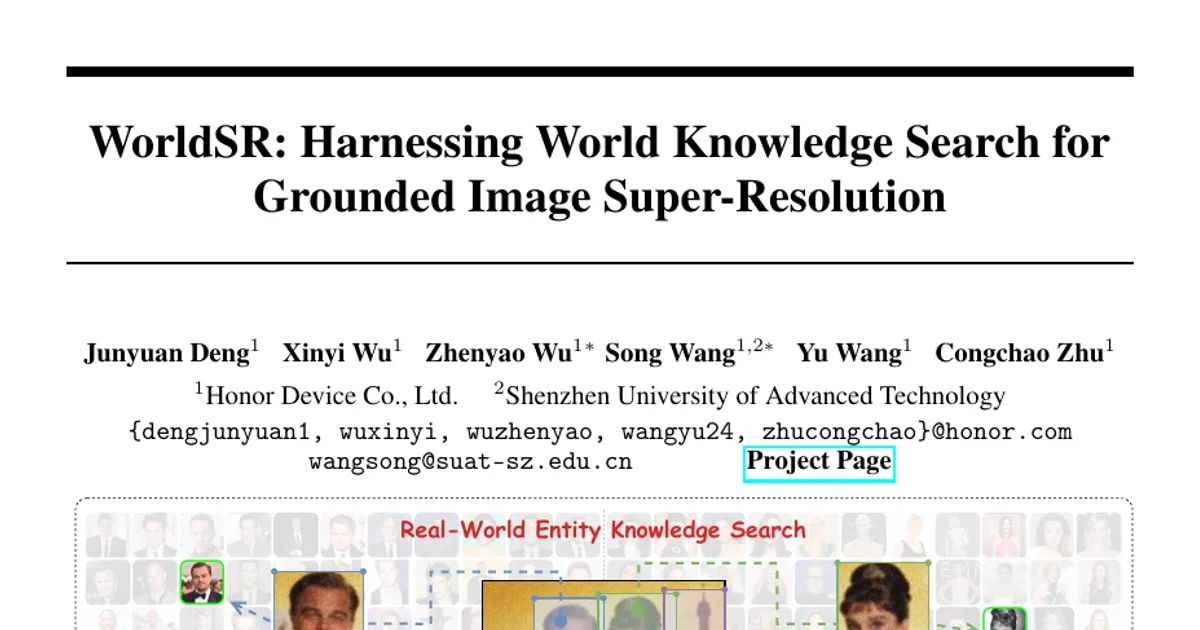
Generative super-resolution models reconstruct plausible detail from priors baked into large pretrained models, but those priors are stochastic and not grounded in the actual subject being upscaled, so they often invent details that look realistic but are wrong. WorldSR's goal is to supply explicit external evidence instead: an MLLM breaks the low-resolution input into real-world entities, images of those same entities are searched for on the web and in a local database, filtered for quality and relevance, and then injected as references during reconstruction. The authors describe this as reframing SR as an "entity-level grounding problem" rather than a purely model-bound generation problem.
Key Contributions
- An agent-style grounded SR framework. WorldSR decomposes super-resolution into five cooperating stages — planning, verification, searching, filtering, and super-resolution — where an MLLM plans which image regions correspond to real-world knowledge entities, and external retrieval supplies the corresponding visual evidence.
- Entity-level world knowledge acquisition with caching and filtering. An Agentic ROI Planner produces entity bounding boxes and crops; a Memory Verifier with a Memory Bank avoids redundant re-retrieval across iterative refinement rounds (using an IoU threshold
s_IoU); a dual-engine searcher combines web reverse image search (Google Lens) with a local knowledge base indexed by SigLIP-2 embeddings and cosine similarity; and a three-stage filter applies quality assessment (RALI and Q-Insight, with thresholds_filter = 3.8), MLLM-based irrelevant-region pruning, and semantic ranking (Qwen3-VL-Reranker) to pick a top-1 reference per entity. - A multi-reference world-grounded SR model. A one-step model built on the Flux.2-dev DiT backbone with three LoRA adapters: a Reference Quality Refinement LoRA (
θ_RQR) that cleans up retrieved references, plus a dual-LoRA design (θ_LRfor degraded low-resolution tokens,θ_Reffor reference tokens) that decouples the two data distributions before unified sequence-level interaction. Training randomly samples the number of references from 0 toN_max, so the model also works with zero references. - Iterative refinement with convergence detection. Intermediate SR outputs are fed back as input for another planning/retrieval round; when all newly proposed ROIs hit the Memory Bank, the loop terminates and returns the previous round's result.
Main Findings
- Best no-reference scores across the board. The paper claims a new state of the art on all no-reference metrics on all five benchmarks. On RealLQ250, WorldSR reports MUSIQ 73.32, CLIPIQA 0.7649, MANIQA 0.5954, RALI 3.9940, Q-Insight 4.0270, versus the strongest prior numbers shown (HYPIR: MUSIQ 69.75, CLIPIQA 0.6978, MANIQA 0.4561, RALI 3.9048, Q-Insight 3.9783; OMGSR reaches RALI 3.9236).
- Deliberate PSNR/SSIM trade-off. WorldSR does not win the reference-based metrics on Bird and Face, which the authors frame as a design choice favoring semantic consistency over pixel-wise fidelity. On Bird it reports PSNR 21.75 / SSIM 0.6709 / LPIPS 0.3836, behind Ada-RefSR (23.36 / 0.6942 / 0.3677). On Face it reports PSNR 22.97 / SSIM 0.6879 / LPIPS 0.3408, behind Ada-RefSR (24.43 / 0.6998 / 0.3191) and OMGSR (24.47 / 0.6977 / 0.3548).
- Identity preservation gain. On Face, WorldSR's IDS of 0.8199 is reported as 6.4% above the second-best face-specific reference-based approach (InstantRestore at 0.7705).
- Near-miss on one Bird metric. On Bird, WorldSR (CLIPIQA 0.8822) is reported as trailing the top approach by a marginal 0.32%; SeeSR+ReFIR scores 0.8850 there.
- Clean sweep on CUFED5. On CUFED5, WorldSR is reported to surpass all competitors on every evaluated metric: PSNR 19.04, SSIM 0.5731, LPIPS 0.2941, MUSIQ 72.52, CLIPIQA 0.6846, MANIQA 0.6198, RALI 3.8854, Q-Insight 3.8196.
- WRSR results. PSNR 19.71, SSIM 0.5540, LPIPS 0.3878, MUSIQ 74.57, CLIPIQA 0.7761, MANIQA 0.6244, RALI 4.1676, Q-Insight 4.1302 — again best on the no-reference metrics shown (e.g., HYPIR MANIQA 0.5050, RALI 3.9533).
- The SR network itself matters, not just the references. Given the same retrieved world knowledge, swapping in SeeSR+ReFIR yields MUSIQ 69.72 / CLIPIQA 0.6792 / MANIQA 0.4756 / RALI 3.8620 / Q-Insight 3.9227, and Ada-RefSR yields 67.35 / 0.6351 / 0.3852 / 3.8221 / 3.9168, both below WorldSR's 73.32 / 0.7649 / 0.5954 / 3.9940 / 4.0270.
- Ablations isolate the retrieval pipeline's value. Removing the World Knowledge Searcher drops RealLQ250 MUSIQ from 73.32 to 72.14, CLIPIQA from 0.7649 to 0.7527, MANIQA from 0.5954 to 0.5910, RALI from 3.9940 to 3.8777, and Q-Insight from 4.0270 to 3.9824, with the authors noting severe visual hallucinations. Removing the World Knowledge Filter gives 72.49 / 0.7628 / 0.5842 / 3.9385 / 3.9964 — no obvious visual hallucination but a clear quantitative drop. Removing the Iterative Refinement Loop (73.23 / 0.7621 / 0.5928 / 3.9862 / 4.0257) or the Agentic ROI Planner (73.13 / 0.7654 / 0.5968 / 3.9688 / 4.0176) produces smaller declines attributed to entity misalignment.
- Web search adds value over a local base alone. On Face, baseline (no external knowledge) gives MUSIQ 77.03 / CLIPIQA 0.7296 / MANIQA 0.6979 / RALI 4.1397 / Q-Insight 4.0704 / IDS 0.6894; local knowledge base only gives 77.41 / 0.7910 / 0.7321 / 4.2226 / 4.1893 / 0.8096; web + local gives 77.57 / 0.8089 / 0.7517 / 4.2522 / 4.1917 / 0.8199. On Bird the same progression runs 76.33 → 76.23 → 77.12 on MUSIQ, 0.8532 → 0.8718 → 0.8822 on CLIPIQA, and 4.0749 → 4.1059 → 4.2081 on RALI.
Methodology in Plain English
Take a blurry, low-resolution photo. First, a multimodal LLM looks at it and, using a carefully constrained prompt, lists only the "entities" it is confident about — people, animals, landmarks, vehicles — and draws a tight box around each one, returning the answer as structured JSON. Crops of those boxes become search queries.
Before searching, a cache check runs: if a similar box was already retrieved in an earlier round (measured by overlap with stored boxes, against a threshold), the previously found reference image is reused and no new search happens. Otherwise two searches run in parallel — a reverse image search on the public web (Google Lens, then scraping the source URLs for full-resolution versions) and a similarity lookup against a pre-registered local image database, using SigLIP-2 embeddings and cosine similarity.
The raw candidates are messy, so three filters are applied in order. Images scoring below a threshold on either of two image-quality models are discarded. An LLM then locates the region in each surviving candidate that actually matches the query and crops to it. Finally, a multimodal ranking model scores the cropped candidates against the query and the single best one becomes the reference for that entity.
The super-resolution model is built on a pretrained text-to-image transformer. A first LoRA adapter improves the retrieved references, since even filtered web images carry real-world degradations. Then the low-resolution image and all refined references are converted into token sequences, concatenated, and processed together, with separate LoRA adapters for the degraded-image tokens and the reference tokens so the model can tell the two distributions apart before letting them interact globally. Training is one-step, updates only LoRA parameters, and randomly varies the reference count from zero to N_max so the model degrades gracefully when nothing is retrieved. Supervision combines an MSE loss, an OC-EA-DISTS perceptual loss, and a DINOv3-based adversarial loss.
If anything had to be searched for, the resulting SR image is fed back in as the new input and the loop repeats; the loop stops when every ROI is a memory hit, meaning refinement has converged.
Why This Matters
- Impact on research. The paper argues against treating a generative prior as the sole source of detail and instead treats external, explicitly retrieved visual evidence as a complement. It also shows that image-level retrieval — the natural extension of retrieval-augmented generation to SR — is too coarse for multi-entity scenes, and that entity-level correspondence is the useful granularity.
- Real-world applications:
- Consumer photo restoration / enhancement on phones and cameras, where subjects are often known objects, faces, or places.
- Landmark and e-commerce catalog imagery, where the identity of the depicted object must be preserved exactly rather than plausibly invented (the paper specifically highlights landmarks and well-defined objects).
- Surveillance or archival footage enhancement, where inventing a detail that was never there is worse than leaving it soft.
- Cultural heritage and document/artifact digitization, where fidelity to the actual object is the point.
- Industry relevance. All authors are affiliated with Honor Device Co., Ltd. and Shenzhen University of Advanced Technology, and the pipeline is built entirely from off-the-shelf components (Qwen3.5-35B-A3B, Flux.2-dev, Google Lens, SigLIP-2, Qwen3-VL-Reranker, RALI, Q-Insight), which speaks to near-term productization. The stated costs are explicit: retrieval and refinement add non-negligible computation, and the pipeline depends on external services.
Future Directions
- Robustness to bad entity decomposition. The authors list this as their first limitation: errors in fine-grained entity parsing propagate through retrieval and into reconstruction. Making planning self-correcting or uncertainty-aware is the obvious next step.
- Coverage for rare and long-tail entities. Performance is bounded by the external visual corpus, so handling unseen objects, niche categories, or private scenes — possibly by falling back gracefully or synthesizing references — remains open.
- Disambiguating multiple references. The paper notes that integrating multiple references introduces ambiguity; the trade-off between reference count and fidelity was not reported and is a natural target for a dedicated study.
- Cost reduction. Retrieval, filtering, and multi-round refinement all cost compute, and the paper does not report latency or per-image cost figures. Caching (already partly addressed by the Memory Bank) and cheaper filtering or one-round variants are clear directions.
Target Audience
Researchers and engineers working on generative or reference-based image restoration who want an alternative to purely prior-driven detail synthesis; practitioners building production SR systems who need fidelity guarantees and are willing to accept retrieval infrastructure; and readers interested in agentic pipelines that orchestrate MLLMs and external tools for low-level vision rather than for generation or editing. Readers without a background in diffusion transformers, LoRA, and perceptual/IQA metrics will find the implementation sections dense.
Authors’ abstract
Generative-prior-based super-resolution (SR) methods leverage implicit knowledge learned from large-scale models to enhance low-resolution inputs. However, such priors are inherently stochastic and optimized for diverse generation, conflicting with the deterministic, high-fidelity reconstruction required for SR. It is also tied to the base model, costly to update, and prone to hallucinations as real-world data evolves. To address these limitations, we introduce WorldSR, a novel framework that augments SR with explicit, entity-aligned visual world knowledge. WorldSR automatically decomposes the input into semantic entities and performs entity-wise retrieval of structurally and semantically aligned images from a large-scale external corpus. For efficiency and reliability, we incorporate a memory mechanism to reuse previously retrieved results and a multi-step filtering process to refine candidate references. The selected references as world knowledge are then integrated through a novel multi-reference super-resolution model, which provides fine-grained constraints for detail synthesis and structural recovery. Experiments on real-world SR benchmarks show that WorldSR consistently improves structural fidelity and visual quality, outperforming existing generative super-resolution methods. Our results suggest that entity-level grounding in external visual world knowledge provides a simple and effective complement to model-bound generative priors.