Research
WorldRecon: Generative Multi-View Mesh Reconstruction for Large-Scale 3D World
Overview Research area: Computer vision — 3D scene reconstruction and generative 3D modeling, specifically multi-view mesh reconstruction of large indoor environments from unposed (uncalibrated) RGB i
- arXiv
- 2610.18846
- Published
- 2026-10-13
- Authors
- Mengchen Zhang, Yang Li, Chunshi Wang, Tong Wu, Chunchao Guo
AI summary
Overview
Research area: Computer vision — 3D scene reconstruction and generative 3D modeling, specifically multi-view mesh reconstruction of large indoor environments from unposed (uncalibrated) RGB images.
Technical level: Advanced. The paper assumes familiarity with diffusion/flow-matching generative models, sparse voxel representations, multi-view geometry, pointmap regression, and mesh-based evaluation metrics such as Chamfer distance and F-score.
Scope: The paper presents WorldRecon, a block-wise generative framework that combines a reconstruction prior (VGGT-Ω) with a native 3D generative prior (TRELLIS.2) to produce complete, PBR-textured scene meshes from unposed multi-view RGB images, and evaluates it on 3D-FRONT (synthetic) and ScanNet++ (real-world).
What This Paper Is About
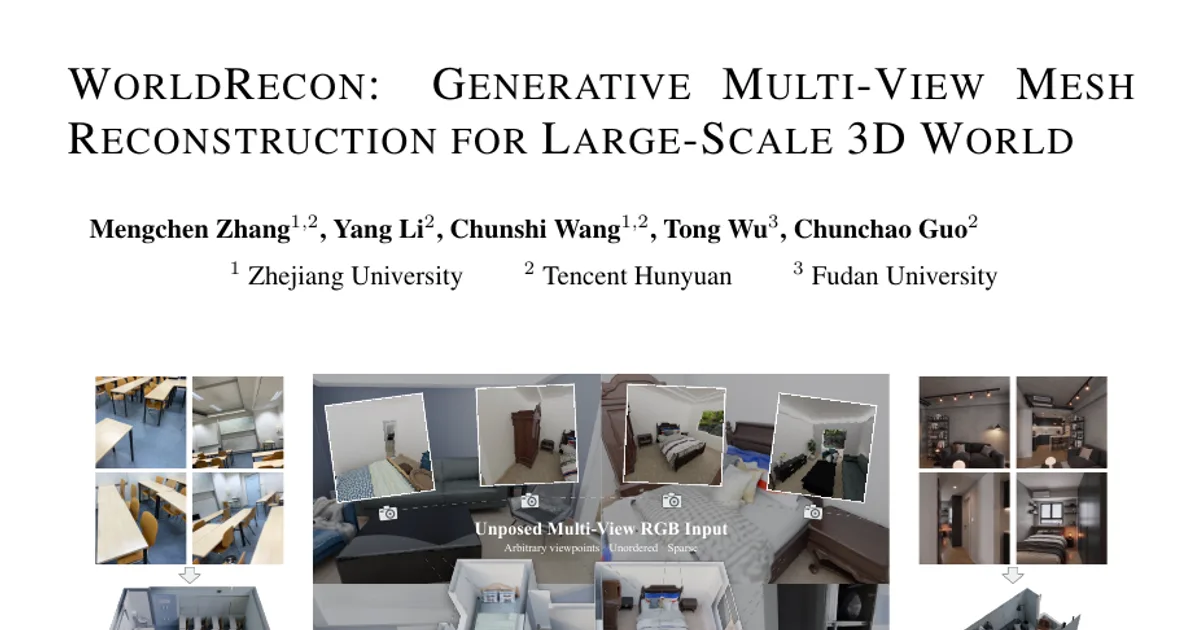
Reconstruction methods can recover the surfaces a camera actually sees, but they leave occluded or sparsely captured regions incomplete and produce noisy geometry that is hard to turn into clean, textured meshes. Purely generative models can invent plausible geometry, but existing scene-level generative reconstruction approaches depend on accurate camera poses to project image features into a 3D volume, so they degrade when poses are imperfect. WorldRecon's goal is to reconstruct complete, high-fidelity, scene-scale meshes with PBR materials from unposed RGB images by grounding generation in a coarse, noisy point cloud and camera estimates rather than requiring clean geometry or calibrated cameras.
Key Contributions
- WorldRecon framework: An integration of 3D reconstruction and 3D generation that recovers large-scale, high-fidelity scene meshes with PBR materials from unposed multi-view RGB images.
- Reconstruction-based block generation with neighbour-aware inpainting: Block-level mesh generation conditioned on a local point-cloud crop and block-relevant multi-view images, plus dedicated inpainting variants of all three denoisers that condition each new block on overlap latents from already-generated neighbours.
- Causal world-generation pipeline: A voxel-priority block ordering that propagates sparse structure, geometry, and material context across overlapping blocks, using trajectory clamping and distance-weighted blending for seamless scene assembly.
- State-of-the-art results and sim-to-real transfer: Experiments on synthetic (3D-FRONT) and real-world (ScanNet++) indoor scenes showing reductions in Chamfer distance of 14.9% and 43.1% and F-score improvements of 17.3% and 12.0% over the strongest baselines, despite training only on synthetic data.
Main Findings
- Synthetic scenes (3D-FRONT, 30 held-out scenes): WorldRecon achieves CD 0.1583, F-score 0.7271, NC 0.6839, and Completeness 0.9589, compared with the strongest baseline GenRecon at CD 0.1861, F-score 0.6196, NC 0.6128, and Completeness 0.9587. It also reports the best values on all evaluated 2D depth and normal metrics, including depth RMSE 0.3910 versus GenRecon's 0.5348, and angular normal error 16.4044 versus FineRecon's 17.6099.
- Real-world scenes (ScanNet++, 30 scenes): WorldRecon reaches CD 0.0638, F-score 0.8363, NC 0.7840, and Completeness 0.9918, with depth RMSE 0.3331 and angular normal error 20.0429. The paper states this corresponds to a 43.1% reduction in CD and a 12.0% improvement in F-score over the strongest baselines.
- Synthetic headline numbers: The abstract reports a 14.9% Chamfer distance reduction and a 17.3% F-score improvement on synthetic scenes.
- Cross-domain generalization: The model is trained solely on synthetic data yet improves real-world reconstruction, which the authors describe as strong sim-to-real generalization. Qualitative results are also shown on frames from generated videos (Seedance et al., 2026).
- Ablation results (30 scenes: 15 from 3D-FRONT, 15 from ScanNet++): Starting from vanilla pretrained TRELLIS.2, results are CD 0.4003, F-score 0.2013, NC 0.1682, Completeness 0.7377, MAE 1.1847, AbsRel 0.6160, angular 48.6471, RGB CLIP 0.7255. Adding reconstruction-based sparse structure gives CD 0.0996 and F-score 0.7438; adding reconstruction-based geometry and material gives CD 0.0954 and F-score 0.7624; adding neighbour-aware inpainting gives CD 0.1023 and F-score 0.7482 (a slight 3D degradation, attributed to residual boundary seams) while improving MAE to 0.1439 and AbsRel to 0.0830; the full pipeline gives CD 0.0830, F-score 0.8226, NC 0.7640, Completeness 0.9894, MAE 0.1394, AbsRel 0.0815, angular 16.5789, and RGB CLIP 0.8671.
- Qualitative failure modes of baselines: VGGT-Ω + TSDF recovers visible surfaces but leaves unobserved regions incomplete and propagates pose/depth errors into noisy artifacts and distorted walls; Murre and FineRecon show artifacts and broken surfaces; GenRecon injects distorted point clouds and inaccurate poses into its generative model, producing fragmented artifacts and global layout distortion; MonoSDF completes regions but over-smooths surfaces and loses fine detail.
- Data scale: Training blocks number roughly 56k from 6k 3D-FRONT scenes and 61k from 10k SAGE-10k scenes, totalling around 117k training blocks.
- Not reported in the provided content: wall-clock inference time, memory footprint, parameter counts, and the exact training hyperparameters (these are referred to the Appendix, which is not included in the supplied text).
Methodology in Plain English
The pipeline has three conceptual parts.
Getting a rough scaffold. The system takes an arbitrary number of uncalibrated RGB images and runs VGGT-Ω to predict coarse camera poses and a global point cloud. After confidence filtering and outlier removal, the point cloud is aligned into canonical scene coordinates. This point cloud is deliberately treated as imperfect — it is a scaffold, not ground truth. The scene's XY bounding box is partitioned into overlapping cubic blocks of side length ℓ, with adjacent blocks overlapping by ℓ/4. For each block, only the parts of the input images that fall inside the block are kept; images with at least 15% in-block pixel coverage become candidate views, and up to V views are chosen to maximise the block's voxel coverage. Blocks are then generated in a voxel-priority order that starts from the highest-occupancy block and greedily expands a connected frontier, ensuring each block has at most two previously generated four-connected neighbours.
Teaching the generator to reconstruct blocks. The authors start from TRELLIS.2, an image-to-3D generative model that represents assets as sparse voxels called O-Voxel, and whose generation cascades three flow-matching DiT stages: Sparse Structure (which voxels are active), Geometry (geometry latents inside active voxels), and Material (material latents aligned to the geometry). All three stages are finetuned for block-level scene generation. The original single-image conditioning is replaced with reconstruction-based conditioning: multi-view images encoded by a frozen DINOv3 patch encoder and camera poses encoded as five Plücker rays, fused via cross-attention into fixed-length tokens; the Sparse Structure stage additionally receives point-cloud tokens from a Fourier positional embedder plus linear projection (following the Hunyuan3D-Omni design), with point-cloud tokens randomly dropped during training to enable classifier-free guidance. Training data is built by slicing 3D-FRONT and SAGE-10k scenes into cubic blocks, with each block yielding a mesh, a point cloud, up to 16 RGBA renders and their block-local camera poses; point clouds are sampled either from noise-augmented unprojected ground-truth depth or from a VGGT-Ω reconstruction, so the model sees both controlled perturbations and the inference-time distribution.
Stitching blocks into a world. Because each new block sees only partial context from its neighbours, the authors train inpainting variants of all three denoisers. Each denoiser receives C+1 extra input channels: a binary inpainting mask and a C-channel masked known latent. Inpaint variants are initialised from the corresponding generation models, with the original input projection inherited and the new channel weights zero-initialised, so finetuning starts from a functionally equivalent generator. Training masks emulate inference overlaps: masking is restricted to the XY plane (all scenes fit in one block vertically), and one or two neighbour-supplied edges are sampled, with an L-shape constraint when there are two. At inference, the raw overlap of width ℓ/4 is shrunk by one quarter, leaving a known margin of 3ℓ/16 and an editable transition band of ℓ/16. During denoising, a trajectory-clamping mechanism restores the known overlap to its forward-flow trajectory at every step, so generated context is preserved while unknown regions evolve. After the world Sparse Structure latent is complete, Geometry and Material latents are generated in the same causal order and blended into shared world latents using a linear feather weight based on distance to block boundaries (producing bilinear blending at corners) via an online weighted average. Finally, aligned block latents are decoded into block-local PBR meshes, transformed into the shared world frame, and merged. At inference the system uses a 12-step Heun sampler with guidance scales 7.5, 7.5, and 3.0 and time-rescaling factors 5.0, 3.0, and 3.0; blocks are 4 m, conditioned on up to 4 local views and an 8192-point cloud crop, and the model starts from the 512-resolution TRELLIS.2 pretrain, with full finetuning of Sparse Structure and Geometry and LoRA on Material, trained on 32 NVIDIA GPUs.
Why This Matters
Impact on research. The paper argues that generative reconstruction at scene scale does not require clean camera poses or accurate geometry, only a coarse scaffold used as a conditioning signal. If that holds, it relaxes a key constraint of prior scene-level generative reconstruction methods such as SCube and GenRecon, which rely on accurate poses to project features into 3D volumes. The block-wise causal generation scheme also offers a template for scaling any native 3D generative prior beyond the object level.
Real-world applications:
- Virtual and augmented reality content pipelines that need complete, textured environments rather than partial scans.
- Embodied AI and simulation, where agents need navigable scene geometry and materials for training.
- Digital content production and 3D asset creation from casually captured phone video or generated video frames.
- Scene editing and asset reuse, since the output is a mesh with PBR materials rather than unstructured primitives.
Industry relevance. The work comes from Zhejiang University, Tencent Hunyuan, and Fudan University, and is built on public or company models (TRELLIS.2, VGGT-Ω, DINOv3, Hunyuan3D-Omni-style point conditioning). The pipeline consumes uncalibrated images, which lowers capture requirements for scalable content creation, and its output format (editable PBR meshes) is directly usable in game engines, simulation, and design tools.
Future Directions
- Outdoor generalization. Training data comprise only indoor scenes, so applicability is currently limited to indoor environments; generalization to outdoor scenes remains to be established.
- Multi-story buildings. The scene representation uses a single layer of 4 m-high blocks, restricting reconstruction to single-story environments. Supporting block generation along the vertical dimension is called out as an important direction.
- Boundary consistency. The ablation shows that neighbour-aware inpainting alone slightly degrades 3D metrics (CD 0.1023 versus 0.0954 without it), which the authors attribute to residual seams; the stitching mechanism resolves this, but further improving seam handling is an open question.
- Dependence on the reconstructed scaffold. Since the point cloud and poses come from VGGT-Ω, the sensitivity of the final mesh to scaffold failure modes is not quantified in the provided content.
Target Audience
Researchers and practitioners working on 3D reconstruction, generative 3D modeling, and scene-level mesh generation; engineers building AR/VR, simulation, or embodied-AI content pipelines that need complete textured scenes from casually captured images; and readers already familiar with flow-matching DiT generative models, sparse voxel representations, and multi-view geometry, since the paper assumes that background.
Authors’ abstract
Reconstructing complete, high-quality meshes of large-scale scenes from unposed multi-view images requires faithful geometric grounding while plausibly completing surfaces that are unobserved or only sparsely captured. We present WorldRecon, a generative multi-view reconstruction framework for recovering complete, large-scale 3D scene meshes from unposed RGB images. WorldRecon uses a coarse, noisy global point cloud and camera poses estimated from the input images by a reconstruction model as a global scaffold for whole-scene generation and partitions it into overlapping spatial blocks. To robustly leverage these imperfect geometric priors, we equip the native 3D generative model TRELLIS.2 with a dedicated reconstruction-based conditioning architecture that generates each block from its local point-cloud crop and block-relevant image observations, producing sparse structure, detailed geometry, and PBR materials. To maintain scene-level coherence, we introduce neighbour-aware latent inpainting and a causal world-generation procedure that propagates structural, geometric, and material context across overlapping blocks. Together, these designs scale multi-view generative reconstruction to large-scale scenes, yielding coherent, unified meshes. Extensive experiments demonstrate that WorldRecon achieves state-of-the-art reconstruction performance, reducing Chamfer distance by 14.9% and 43.1% while improving F-score by 17.3% and 12.0% over the strongest baselines on synthetic and real-world indoor scenes, respectively, thereby demonstrating faithful and complete generative reconstruction as well as strong sim-to-real generalization. Project page: https://kszpxxzmc.github.io/WorldRecon-website/.