Research
VIS-Ground: Video Interactive Storytelling with Contextual Grounding
Overview Research area: Computer vision and video generation — specifically interactive video storytelling, where a viewer can redirect an in-progress video, combined with "contextual grounding" to an
- arXiv
- 2610.09326
- Published
- 2026-10-07
- Authors
- Bingxuan Li, Yiwen Song, Xueqing Wu, Yanzhou Pan, Yang Li, Kuang Su, Jingyun Liu, Sebastian Ko, Huan Zhang, Tong Zhang, Nanyun Peng, Tomas Pfister, Yale Song
AI summary
Overview
Research area: Computer vision and video generation — specifically interactive video storytelling, where a viewer can redirect an in-progress video, combined with "contextual grounding" to an external narrative or knowledge source.
Technical level: Intermediate. The paper is readable without deep mathematics, but it assumes familiarity with video diffusion/generation backbones, LLM-based planning agents, and LLM-as-judge evaluation.
Scope: The paper defines the task of video interactive storytelling with contextual grounding, proposes a three-stage framework (VIS-Ground) that compiles heterogeneous context into explicit generation constraints, and introduces a paired benchmark (VIS-Bench) evaluated across three video backbones.
What This Paper Is About
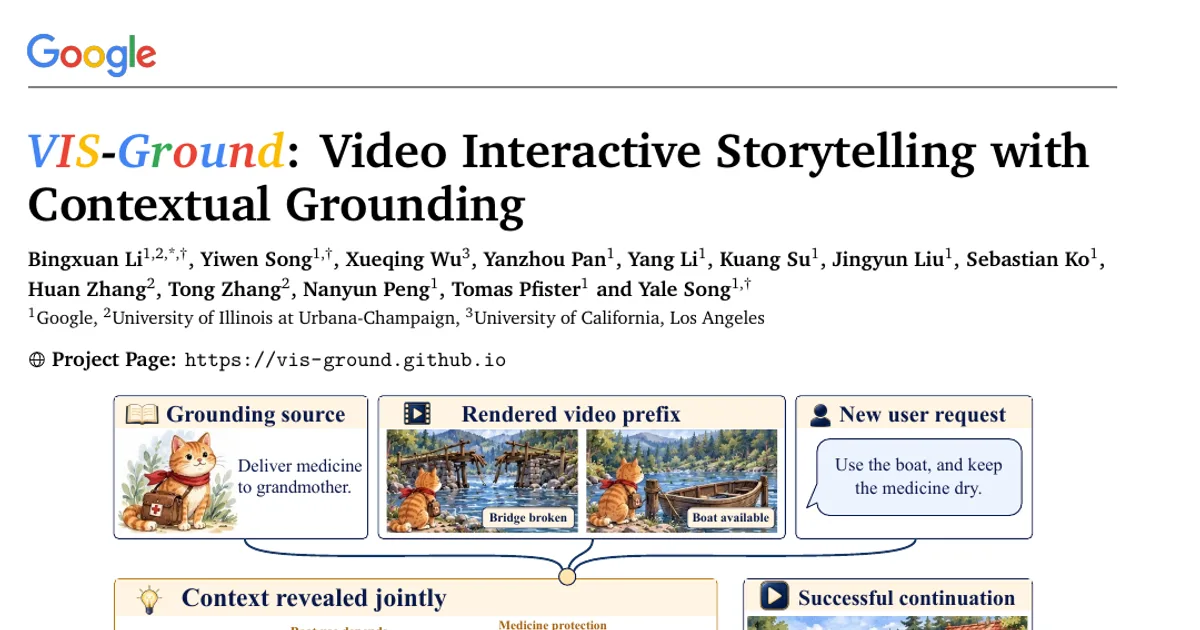
When a viewer interrupts a partially generated video to ask for something new, the request cannot be interpreted in isolation: it depends on what the source material supports and on what the already-rendered video has established. Existing interactive video systems mainly follow the latest instruction, while source-grounded systems mainly align output to an external narrative — neither handles the joint case. The paper's goal is to make those hidden dependencies explicit and enforceable, so a continuation responds to the viewer without contradicting the source or the visible history.
Key Contributions
-
Task formulation. Defines "Video Interactive Storytelling with Contextual Grounding": given a grounding source G, a rendered video prefix v_prefix, and a new viewer request u, generate a continuation v_cont that satisfies all three. The formulation treats v_prefix as a sufficient record of earlier instructions rather than conditioning on their full history.
-
The VIS-Ground framework. Casts contextual grounding as context compilation — transforming heterogeneous inputs into a grounded dependency model M = (V, H, S, A) of video state, story state, source state, and cross-context alignments, then deriving a dependency set R = Derive(M).
-
Candidate-conditioned constraints and repair. Dependencies become constraints c_j = (s_j, a_j, b_j, e_j) only when a proposed script activates them, evaluated as pass / fail / unknown. Failures drive targeted script revision and, after rendering, output-level repair — the same dependency model is reused for both reasoning and generation.
-
VIS-Bench. A benchmark built from 250 CoQA source passages (132 narrative-grounded, 118 knowledge-grounded), with 1,004 interaction instructions yielding 2,008 planned instruction–style instances across two visual styles (cinematic realism and cutout animation), plus six evaluation metrics (Source Faithfulness, Story Continuity, Interaction Fulfillment, Joint Constraint Satisfaction, Visual Consistency, Video Quality).
Main Findings
-
Best composite on every backbone. VIS-Ground scores 84.2 on Omni-1.1-Flash, 84.6 on Veo 3.1, and 78.8 on MiniMax-H3, versus the strongest baseline per backbone of 71.9, 69.3, and 75.4 respectively — gains of 12.3, 15.3, and 3.4 points, an average absolute improvement of 10.3 points.
-
Gains concentrate where joint reasoning is required. Across the grounding-related dimensions (Source Faithfulness, Story Continuity, Interaction Fulfillment, Joint Constraint Satisfaction), the paper reports an improvement of roughly 10% on average over the strongest competing result across backbones and settings.
-
It works for both narrative and knowledge grounding. Improvements hold in both settings despite their different emphases (character/event progression versus factual accuracy). For example, on Omni-1.1-Flash under knowledge grounding, JCS is 80.2 versus 66.3 for the strongest baseline.
-
Stability across generators. Direct Generation's composite spans more than 30 points across the three backbones (70.2, 69.3, 38.1), while VIS-Ground's range is below 6 points — described as an approximately 82% reduction in cross-backbone performance variation.
-
Both structural components matter. In the narrative-grounded setting, replacing the structured representation with a free-form summary ("Unstructured State") reduces the mean of SF, SC, and IF by 7.60 percentage points; removing instance-specific constraint induction ("One-Pass Planning") reduces it by 4.36 points.
-
It is not best on every metric. VIS-Ground loses some Interaction Fulfillment, Visual Consistency, and Video Quality comparisons. The authors attribute IF losses to deliberately favoring compatibility with prior evidence over literal instruction-following in ambiguous or conflicting requests, and VQ losses to the fact that the method does not modify the synthesis model itself.
-
Residual failures are about detail, not gross context. In a 72-output failure-analysis sample (an analysis subset, not the full evaluation set), 67 outputs scored at least 75 on Source Faithfulness, and 64 reached that threshold on each of Story Continuity and Interaction Fulfillment; perfect scores were rarer (8 for Story Continuity, 11 for Interaction Fulfillment).
-
Motivating evidence for interaction. The introduction reports formative-study pre-to-post gains of 47.9 percentage points with interaction versus 32.1 without; the study enrolled nine volunteers, with learning gains analyzed for the seven who passed an attention test. Prior log analyses cited in the paper find viewers revise or reformulate intent in 18–30% of sessions.
Methodology in Plain English
The system separates "what the context establishes" from "what that implies for what comes next," in three stages.
First, it reads the source document, the video so far, and the viewer's request, and converts each into structured facts — entities, attributes, events, state changes — using vision-language models. These become three aligned states: what the video has visibly shown, what the story has established, and what the source actually supports. Aligning them produces cross-context dependencies: temporal ordering rules, causal prerequisites, things that must persist, things that would conflict.
Second, when the planner drafts a candidate script, the system checks which dependencies that particular draft makes relevant. A rule about who owns an object only matters if the draft has someone use that object. Each activated constraint is checked and returns pass, fail, or unknown, with links back to the evidence that justified it — so a failure points to a specific violated dependency rather than a vague quality complaint.
Third, the draft is revised using that targeted feedback, and activation is recomputed after each revision because new events can trigger new obligations. Only then is the video rendered. Because a valid script does not guarantee a faithful render, the system re-extracts what the video actually shows and projects the same dependencies onto the output, sending any unrealized dependency back as feedback for another repair-and-render round. The loop stops when the applicable dependencies are satisfied or the budget runs out.
Evaluation uses two independent LLM judges (Gemini 3.8 Flash and Claude Opus 5) scoring metric-specific checklists on a five-level scale, with scores normalized to 0–100 and averaged across judges; human validation of the rubric is performed blinded. On a fixed 16-instance subset per backbone (8 narrative, 8 knowledge), five methods are run across three backbones, giving 240 evaluated continuations of 48 seconds each (two 24-second scenes of three eight-second shots). No training split exists.
Why This Matters
The paper reframes interactivity as a constraint-satisfaction problem rather than a prompt-following problem. That matters because responsiveness without grounding is easy to achieve and often wrong: a system can satisfy a request while contradicting the source or the already-rendered history. Making dependencies explicit and traceable also makes failures diagnosable, which is a precondition for deploying these systems where factual or narrative accuracy is non-negotiable.
Real-world applications:
- Educational and explanatory video that lets a learner pause and ask "why?" or "show me an example" while staying faithful to a paper, textbook, or wiki page.
- Interactive documentaries and journalism, where a viewer's question about a claim must be answered without misrepresenting the underlying reporting.
- Training and simulation content, where a procedure or sequence must not be reordered or skipped when a trainee redirects the scenario.
- Brand and marketing storytelling, where an interactive narrative must remain consistent with approved characters, products, and established scenes.
Industry relevance: The method is backbone-agnostic — it is layered on top of Omni-1.1-Flash, Veo 3.1, and MiniMax-H3 without altering the generator, and it substantially reduces performance variance across them. That makes it attractive to teams that treat video generators as interchangeable commodity components and want a reliability layer above them. The benchmark and its source-faithfulness/continuity/interaction split also give product teams a way to report quality that separates reasoning failures from rendering failures.
Future Directions
-
Better dependency extraction. The authors explicitly flag dependency extraction as a remaining challenge, and their ablation shows the structured representation is the single largest contributor among the tested components — so improving what gets extracted and aligned is the highest-leverage target.
-
Faithful realization during rendering. Since visual quality and some consistency scores are bounded by the generator and the method does not modify it, closing the gap between a verified script and the rendered video is left open — including tighter coupling to the synthesis model.
-
Resolving the instruction-following trade-off. When a viewer request is ambiguous or partially conflicts with established context, the system currently favors compatibility over literal compliance, costing Interaction Fulfillment. Deciding when to push back on or clarify a request, rather than silently prioritizing context, is unresolved.
-
Scaling evaluation. The reported results come from a fixed 16-instance subset per backbone out of 2,008 planned instances; the authors note their ablation comparisons do not independently isolate representation, repair, and reasoning-budget effects, leaving room for fuller and more controlled studies.
Target Audience
Researchers and practitioners working on controllable or interactive video generation, long-form video storytelling systems, and agentic generation pipelines. It is also useful for teams building evaluation harnesses for grounded generation, since the metric decomposition (source faithfulness, story continuity, interaction fulfillment, plus perceptual quality) offers a template for separating reasoning errors from rendering errors. Readers mainly interested in raw video synthesis quality will find less here, as the method deliberately leaves the generator untouched.
Authors’ abstract
Video interactive storytelling enables viewers to actively steer how a video unfolds. However, once we allow viewers to intervene during generation, a new challenge arises: The viewer's request can have latent dependencies on both the grounding source and the current rendered video state. These dependencies may not be explicitly stated in any individual input, but emerge only when the source, rendered history, and new viewer intent are considered jointly. Existing interactive video generation systems primarily emphasize following viewer instructions, while source-grounded video generation methods focus on aligning generated content with an external narrative or knowledge source. This leaves a fundamental question underexplored: What context should a generation model ground on during interactive continuation, and how can heterogeneous, unstructured inputs be transformed into such grounding context? In this work, we formulate contextual grounding as the process of transforming heterogeneous input context into an executable constraint model for video generation. To address this challenge, we introduce VIS-Ground, which performs Structured Context Abstraction to recover grounded states and cross-context dependencies, Generation Constraints Induction to project relevant dependencies into candidate-specific constraints, and Constrained Video Generation to enforce these constraints through planning, verification, revision, and rendering. Across three video generation backbones, VIS-Ground consistently achieves the highest overall composite score, reaching an average absolute improvement of 10.3 points over the strongest per-backbone baselines. Detailed analysis further shows gains across both narrative and knowledge grounding, and reveals remaining challenges in dependency extraction, and faithful realization during video rendering.