Research
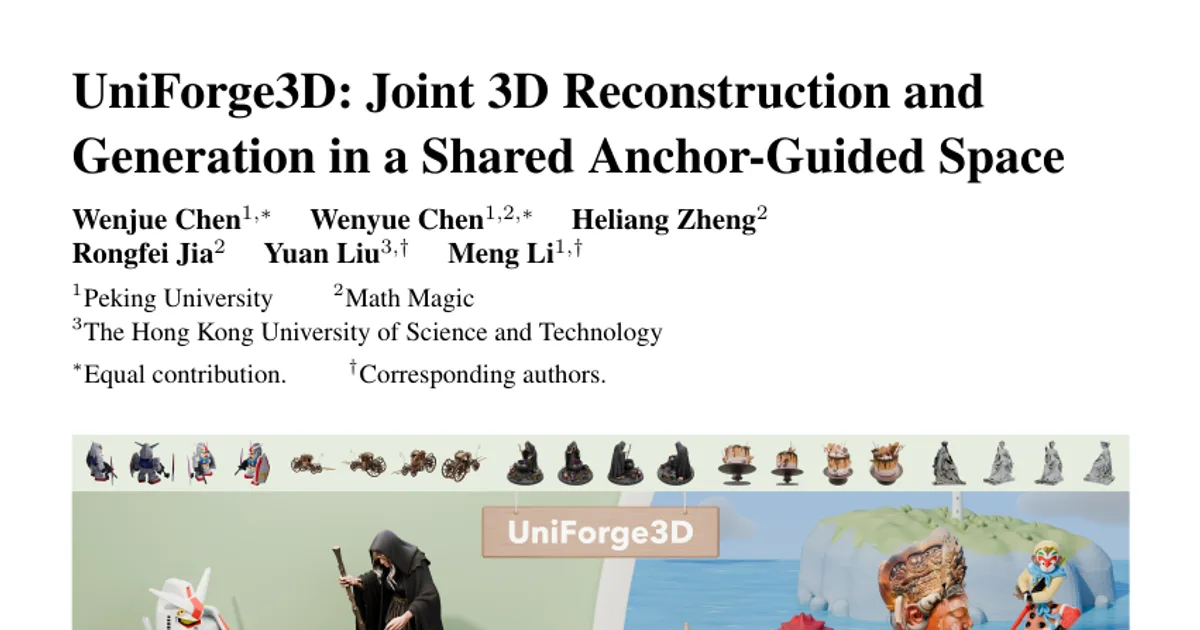
UniForge3D: Joint 3D Reconstruction and Generation in a Shared Anchor-Guided Space
Overview Research area: Computer vision — 3D object reconstruction and generative 3D modeling from multi-view images. Technical level: Advanced. The paper assumes familiarity with feed-forward multi-v
- arXiv
- 2610.15357
- Published
- 2026-10-11
- Authors
- Wenjue Chen, Wenyue Chen, Heliang Zheng, Rongfei Jia, Yuan Liu, Meng Li
AI summary
Overview
Research area: Computer vision — 3D object reconstruction and generative 3D modeling from multi-view images.
Technical level: Advanced. The paper assumes familiarity with feed-forward multi-view reconstruction (point maps, VGGT), Diffusion Transformers, sparse-voxel 3D latent representations, LoRA fine-tuning, and flow-matching objectives.
Scope: UniForge3D is a single framework that couples a multi-view reconstruction branch and a sparse-voxel 3D generation branch inside one shared, anchor-aligned coordinate space, and uses the generated structure to route per-voxel image evidence into detailed shape synthesis.
What This Paper Is About
Given only a few images of an object taken from unknown camera poses, the goal is to produce a complete 3D asset that keeps the geometry and appearance actually seen in those images while plausibly filling in the parts nobody photographed. Pure image-conditioned 3D generators tend to drift toward shapes their priors find plausible rather than matching what was observed, while pure reconstruction leaves unseen regions empty. The paper's core claim is that reconstruction and generation should be trained together, but only after removing the coordinate-system mismatch between them and after deciding, for each 3D location, which input view actually contains useful evidence.
Key Contributions
-
A shared anchor-guided object space. The authors define a coordinate frame whose horizontal orientation follows the azimuth of a designated anchor view (the first input image) while the vertical axis stays canonical and upright. Both the reconstruction branch (originally camera-relative) and the generation branch (originally canonical-space) are trained and supervised in this single frame, so reconstructed points and generated voxels can be associated directly without learning a similarity transform.
-
Bidirectional joint reconstruction and generation. Reconstruction tokens and generation tokens exchange information through cross-attention in both directions: reconstruction features are added as residuals to frozen DINOv3 patch features to condition sparse-structure generation, and generation tokens are injected back into reconstruction with noise-level gating. The two branches are optimized with a combined flow-matching and point-map loss.
-
Structure-guided reconstruction and voxel-wise view selection. The generated sparse voxel structure is fed back as an explicit condition to the reconstruction network, which then predicts point maps expressed in the same space as the voxels. Quantizing those points onto the voxel grid yields pixel-to-voxel correspondences; each voxel is assigned the view with the strongest support, and that view's features condition the shape denoiser through selected-view attention alternated with global multi-view attention.
-
State-of-the-art results on two benchmarks plus real-world images. The method reports the best scores across all evaluated appearance and geometry metrics on Toys4K and GSO compared with Hunyuan3D-2MV, Mix3R, MV-SAM3D, ReconViaGen (v0.2 and v0.5), and Stream3D + TRELLIS.2.
Main Findings
-
Best overall quantitative results. On Toys4K the method reaches PSNR 27.428, SSIM 0.9616, LPIPS 0.0401, Chamfer Distance 1.4196 (×10⁻²) and F-score 0.8899; on GSO it reaches PSNR 24.826, SSIM 0.9363, LPIPS 0.0591, CD 1.4047 (×10⁻²) and F-score 0.8897. Every one of these is the best value in Table 1 for its column.
-
Clear margin over the strongest baselines. The closest PSNR competitor is ReconViaGen v0.5 at 25.020 on Toys4K and 22.774 on GSO. The closest geometry competitor in F-score is Mix3R at 0.7343 (Toys4K) and 0.7174 (GSO), versus 0.8899 and 0.8897 for UniForge3D.
-
The shared space matters more than the conditioning scheme alone. In the sparse-structure ablation on GSO (64³ occupancy grids), DINO-only conditioning scores IoU 0.4261 / CD 2.0019; adding frozen VGGT features in the anchor-guided space raises this to IoU 0.5533 / CD 1.1710; full anchor-guided joint training reaches IoU 0.5827 / CD 1.0563.
-
Canonical or cross-space joint training is worse than anchor-guided joint training. Canonical-space joint training scores IoU 0.4601 / CD 1.5825 and cross-space joint training (reconstruction in VGGT's first-camera space, generation in canonical space) scores IoU 0.4563 / CD 1.6291 — both below the anchor-guided variant's 0.5827 / 1.0563, supporting the claim that tying the frame's orientation to the input view helps.
-
Reconstruction improves from interacting with generation. Point-map accuracy on GSO (×10⁻³) goes from 5.025 accuracy / 4.667 completeness / 4.846 overall for image-only VGGT, to 4.053 / 4.250 / 4.152 when trained jointly, to 3.539 / 3.086 / 3.313 when the generated sparse structure is used as an explicit condition.
-
Per-voxel view selection beats conditioning on all views. With the same predicted 64³ sparse structure, full multi-view conditioning yields PSNR 26.892, SSIM 0.9649, LPIPS 0.0401, CD 1.4739 and F-score 0.8758 on rendered normal maps, while the proposed alternating scheme yields 27.207, 0.9657, 0.0388, 1.4047 and 0.8897.
-
Qualitative behavior. Comparisons on synthetic benchmarks (Fig. 4) and real-world unposed images (Fig. 5), as well as the supplementary video, are reported to show that competing methods omit parts or distort local structures while UniForge3D preserves the observed geometry and appearance.
-
Stated limitation. Training uses synthetic renderings, and severe occlusion, strong reflections, and extreme lighting remain challenging; no failure-rate or robustness numbers on such conditions are reported.
Methodology in Plain English
The system takes four unposed RGB images and treats the first as the anchor. It builds one common 3D frame by rotating the canonical object space so that the anchor's viewing azimuth becomes the "front," while keeping the object upright. Both target types are generated from this same transformed geometry: visible surface points become the point-map targets for reconstruction, and the full geometry is voxelized into the sparse-structure target for generation.
Two pretrained networks are then coupled. A VGGT reconstruction branch predicts per-view point maps and confidence maps; a TRELLIS.2 Diffusion Transformer branch generates a coarse sparse voxel structure. At selected layers they talk to each other: the reconstruction features are adapted and added to frozen DINOv3 image features, which the generator attends to across all views; in the reverse direction, generation features are injected into the reconstruction tokens with gating that depends on the current noise level. In this stage the branches are fine-tuned with LoRA (rank 64 for generation, rank 32 for reconstruction) while new interaction modules are trained fully.
In a second stage the generated voxels are encoded as tokens and fed into the reconstruction network as an extra condition, so point prediction uses both the images and the current coarse shape. Because those points live in the same frame as the voxels, each predicted pixel can be dropped into a voxel cell. After keeping the highest-confidence 95% of valid foreground predictions, the authors count how many pixels from each view land in each voxel, using the largest connected component on the image as the support score, and pick the argmax view. Unsupported voxels inherit a view from a directly supported voxel in their 26-neighborhood, falling back to the anchor view. Ties favor the anchor view, then higher mean confidence.
Detailed shape generation is a coarse-to-fine (512 and 1024) TRELLIS.2 denoiser with rank-128 LoRA, whose cross-attention alternates between global multi-view attention for completion context and selected-view attention that lets each voxel read only its assigned view's full feature sequence. Texture is produced by a separate generator conditioned on the fixed shape latent and decodes base color, metallic, roughness and opacity into UV textures.
Training used 32 NVIDIA A800 GPUs. The joint stage ran 60K iterations at global batch size 128 and learning rate 5×10⁻⁵, the structure-guided reconstruction was fully fine-tuned for 40K iterations and then frozen, and each shape generator used 60K iterations at batch size 64 and 5×10⁻⁵. Data came from a 210K-object subset of TRELLIS-500K, with two sampled azimuthal orientations and six candidate anchor views per orientation plus 48 extra rendered views; evaluation used 500 objects from Toys4K and 500 from GSO, all held out, rendered from four random viewpoints.
Why This Matters
The paper argues that image conditioning alone does not force a generator to match observed surfaces, and that bolting a reconstruction front-end onto a generator propagates that front-end's errors. Its answer — put both tasks in one frame and let the generated structure decide which pixels matter for which voxel — is a concrete recipe for observation-faithful 3D generation rather than plausibility-driven generation. If the reported gains hold, it reframes "reconstruct vs. generate" as a single coupled problem with a shared geometric reference.
Real-world applications:
- Gaming and digital content creation: turning a handful of casual product or prop photos into complete, textured 3D assets without a scanning rig or known camera poses.
- Augmented and virtual reality: populating scenes from sparse capture, where unseen backs and undersides must still be filled in consistently.
- E-commerce and digital twins: building viewable 3D product models from unposed user or catalogue imagery while keeping visible surface detail faithful.
- Embodied intelligence and robotics: object-level 3D assets for simulation and manipulation, where unseen regions must be completed but observed geometry must not be hallucinated away.
Industry relevance: the method reuses pretrained TRELLIS.2 and VGGT backbones with LoRA rather than training from scratch, which is attractive for teams that already hold such checkpoints; the training cost reported (32 A800 GPUs across multiple stages) is substantial but typical for this class of 3D foundation model.
Future Directions
- Robustness to hard capture conditions. The stated limitation is that training uses synthetic renderings, with severe occlusion, strong reflections, and extreme lighting still challenging; the authors propose training with simulations of these conditions.
- Whether the shared frame generalizes beyond the anchor choice. The anchor view fixes the front direction and is also the fallback for unsupported voxels; how sensitive results are to which input image is chosen as anchor is not reported and is a natural next question.
- Scaling the joint stage. The joint model is trained on a 210K-object subset of TRELLIS-500K, leaving open how the coupled branches behave with much larger or more varied 3D corpora.
- Efficiency and inference cost. Training and hardware are described in detail, but inference latency, memory, and per-asset runtime are not reported, which matters for interactive or production pipelines.
Target Audience
Researchers and engineers working on 3D generative models, multi-view reconstruction, and feed-forward geometry estimation — particularly those building native sparse-voxel or VecSet generators who want observed geometry to be respected rather than approximated. It is also relevant to practitioners in graphics, AR/VR, and robotics who need complete assets from sparse, unposed captures, and to readers interested in how two pretrained 3D models can be coupled through a shared coordinate frame with LoRA fine-tuning. Readers without background in diffusion transformers, point maps, or sparse voxel latents will find the method section dense.
Authors’ abstract
Generating complete 3D assets from sparse, unposed images requires preserving observed geometry while completing unseen regions. Joint reconstruction and generation offers a way to address both goals: reconstruction recovers the geometry observed in the input images, while generation contributes learned shape priors. However, combining camera-relative reconstruction with canonical-space generation introduces a coordinate mismatch that makes direct geometric interaction more difficult. Moreover, conditioning each 3D location on all views without accounting for their relevance may mix useful geometric evidence with unrelated image content, hindering local detail recovery. We present UniForge3D, which jointly models reconstruction and generation in a shared anchor-guided space, resolving their coordinate mismatch. This space follows the anchor view's azimuth while keeping the object upright. The two branches exchange features bidirectionally to predict per-view point maps and a complete sparse voxel structure. We further condition point-map prediction on the generated structure to establish pixel-to-voxel correspondences and select the most informative input view for each voxel. Features from the selected views then guide detailed shape generation, helping preserve observed geometric details. Our method achieves state-of-the-art appearance and geometry results on Toys4K and GSO, generating complete 3D assets with improved fidelity. Project webpage: https://xishuxishu.github.io/uniforge3d-project/