Research
UltraTex: Unleashing 2K Multi-View Diffusion for 3D Texturing
Overview Research area: Generative computer vision and graphics, specifically 3D texture generation using multi-view diffusion models. Technical level: Advanced. The paper assumes familiarity with Dif
- arXiv
- 2609.23169
- Published
- 2026-09-19
- Authors
- Yibo Zhang, Ze Yuan, Nan Cao, Li Zhang, Yan-Pei Cao, Yuan-Chen Guo, Rui Ma
AI summary
Overview
Research area: Generative computer vision and graphics, specifically 3D texture generation using multi-view diffusion models.
Technical level: Advanced. The paper assumes familiarity with Diffusion Transformers (DiTs), Flow Matching, VAE latent spaces, Rotary Position Embeddings (RoPE), and block-sparse attention kernels.
Scope: The paper introduces UltraTex, an end-to-end framework that scales multi-view diffusion for 3D texturing to 2048 × 2048 resolution by exploiting foreground sparsity, alongside a new large-scale rendering dataset.
What This Paper Is About
Existing multi-view diffusion methods for 3D texturing operate at low resolutions such as 512 or 768, so they cannot preserve high-frequency detail from high-resolution reference images. Scaling these methods to 2048 resolution is computationally prohibitive: a six-view setup produces a unified sequence of 212,992 tokens, causing excessive memory use and latency. UltraTex addresses this by removing the redundant background regions of object-centric multi-view renderings and by sparsifying the attention computed over the remaining foreground tokens, while adding a decoding strategy and a training dataset to support 2K generation.
Key Contributions
-
UltraTex framework: An efficient end-to-end multi-view diffusion framework that scales generation to 2048-resolution texture output, producing high-fidelity multi-view texture images for 3D texturing.
-
Foreground-aware computational design at three levels: Background Token Dropping to compress sequence length before the DiT backbone, Block-Sparse Attention with Top-K block selection to reduce attention cost over the retained foreground tokens, and Foreground-Aware VAE Decoding to keep inference fast without reconstruction artifacts.
-
G-buffer TexVerse dataset: A large-scale, ultra-high-resolution multi-view rendering dataset built on TexVerse, covering over 268,000 filtered 3D assets with multi-view G-buffer attribute maps, reference images, and shaded image sets rendered under diverse lighting at resolutions up to 4096 × 4096.
-
Demonstrated efficiency gains: 20.6× to 91.1× training speedup and 22.3× to 74.6× end-to-end inference speedup over the baseline on common samples in the dataset, alongside state-of-the-art visual results.
Main Findings
-
Sequence length is the bottleneck: At 2048 × 2048, each image becomes 16,384 tokens after 8× VAE downsampling and 2×2 DiT patchification. A standard six-view generation setup yields 6 × 16,384 (noisy latents) + 6 × 16,384 (conditions) + 16,384 (reference) = 212,992 tokens, which the paper describes as computationally intractable with dense attention.
-
Backgrounds dominate object-centric renderings: Two example views contain only 24.9% and 7.9% foreground pixels. More than 85% of dataset assets fall within the 5%–30% foreground-ratio range, confirming substantial background redundancy.
-
DiT spatial understanding relies on position, not sequence contiguity: In a preliminary experiment with pretrained FLUX, removing background tokens while preserving original RoPE indices still allowed the model to denoise the discontinuous partial sequence and produce spatially plausible foreground results.
-
Attention over retained foreground tokens is sparse: Attention maps from a lower-resolution full-attention model trained with Background Token Dropping show sparse patterns in both Double-Stream and Single-Stream DiT blocks, motivating Block-Sparse Attention.
-
Foreground-only denoising degrades VAE reconstruction without correction: In Table 2, FLUX VAE reconstruction of full images achieves PSNR 47.65, SSIM 0.9937, LPIPS 0.0023; decoding a denoised foreground against a noisy background drops to PSNR 29.66, SSIM 0.9555, LPIPS 0.0263. The canonical-background replacement alone ("Ours w/o finetune") reaches PSNR 37.81, SSIM 0.9818, LPIPS 0.0084, and adding foreground-restricted decoder fine-tuning ("Ours w/ finetune") reaches PSNR 50.26, SSIM 0.9956, LPIPS 0.0038.
-
Retention ratio trades quality for speed: Smaller ρ gives greater acceleration but degrades quality; ρ = 5% leads to noticeable texture degradation. The final model uses ρ = 20%.
-
Best results on most texture metrics: On a held-out TexVerse test set of 100 unseen objects compared over 32 viewpoints, UltraTex achieves the best scores on most metrics across the Unshaded, Shaded, and Relighting tracks. Unshaded: FID 125.13, CLIP-FID 15.180, CMMD 0.810, CLIP-I 0.929, LPIPS 0.082. Shaded: FID 97.6, CLIP-FID 12.239, CMMD 0.368, CLIP-I 0.941, LPIPS 0.064. Relighting: FID 96.4, CLIP-FID 11.583, CMMD 0.333, CLIP-I 0.944, LPIPS 0.062. Note that in the Shaded and Relighting tracks, LumiTex reports lower CMMD (0.351 and 0.316) than UltraTex.
-
Foreground-only denoising enables test-time scaling: Because only foreground positions are updated, increasing the number of retained foreground tokens increases the valid foreground area in generated views, providing more texture evidence for subsequent 3D texturing.
-
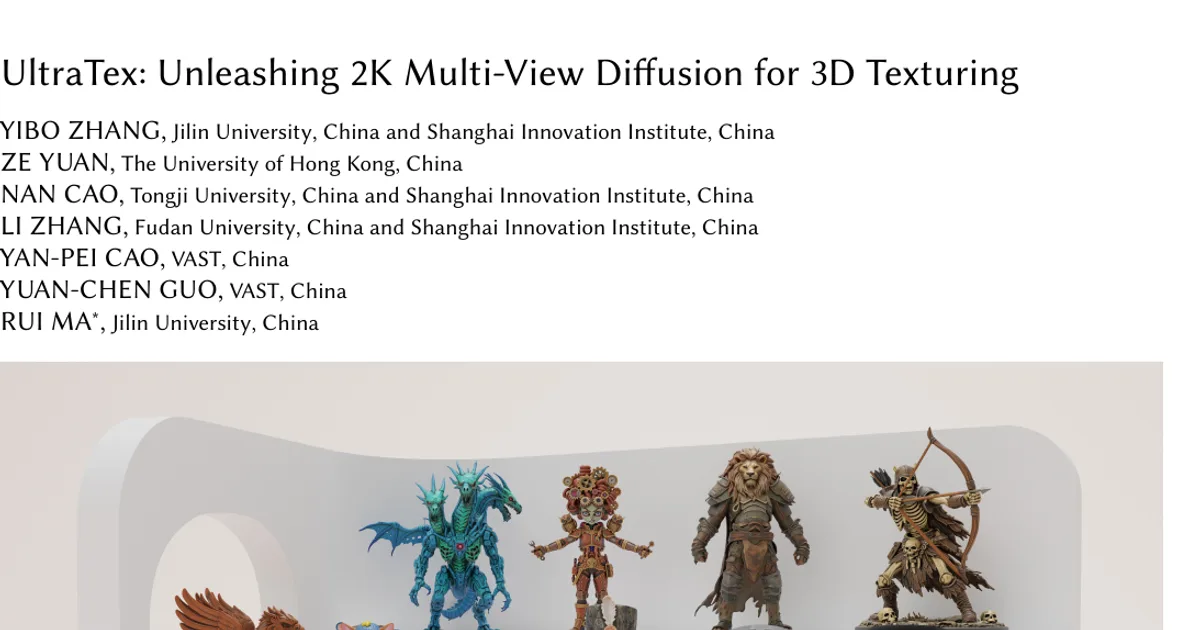
Qualitative advantage over PBR-based baselines: Existing methods often produce over-smoothed albedo textures and miss fine local details, while UltraTex maintains richer high-frequency detail from high-resolution geometric conditions.
Methodology in Plain English
The generator is built on the pretrained FLUX model, which uses a Multi-Modal Diffusion Transformer architecture and Flow Matching. Texturing is framed as in-context conditioning: the reference image, six per-view normal maps used as geometric guidance, and the ground-truth target views are each encoded into latent tokens and concatenated into one sequence. Only the target tokens are supervised to predict the velocity along the noise-to-data path.
The core idea is that object-centric multi-view renderings waste computation on empty space. The authors use binary foreground masks taken from the alpha channels of rendered views, downsample them to 1/16 resolution to match the latent token grid, and slightly dilate them to protect object boundaries. All background tokens are removed before the transformer backbone, so every subsequent layer operates only on foreground tokens. Each surviving token keeps its original RoPE index, preserving absolute pixel coordinates and hence the geometric and epipolar consistency needed across views. Training and inference both operate only on this compressed sequence, with background positions left in their initial Gaussian noise state during sampling.
On top of the compressed sequence, Block-Sparse Attention partitions queries, keys, and values into blocks and cheaply scores block relevance using mean-pooled queries and keys. For each query block, only the top-K key blocks by that score are used, where K is set by the retention ratio ρ. The actual attention values are then computed with the original, unpooled tensors inside the selected blocks, so full token-level attention is preserved where it matters.
Because foreground-only denoising leaves the background as pure noise, the composite latent would confuse a standard VAE decoder. The authors replace the noisy background with a canonical background latent obtained by encoding a solid-color black RGB image with the frozen VAE encoder, tile-repeating it across the 2 × 3 grid. They then lightly fine-tune only the VAE decoder, freezing the encoder, with a reconstruction loss computed only on foreground pixels.
Training uses LoRA with rank 64 on the MM-DiT backbone across 64 H200 GPUs with a per-GPU batch size of 1, in three progressive stages: 512 × 512 with full attention at learning rate 1 × 10⁻⁴ for 22K steps (1 day); 1024 × 1024 with full attention at learning rate 1 × 10⁻⁵ from step 22K to 70K (8 days); and 2048 × 2048 switching to Block-Sparse Attention with ρ = 0.2 at learning rate 2 × 10⁻⁵ from step 70K to 97K (9 days). Training samples are bucketed by effective foreground token count to balance GPU workloads, and DeepSpeed ZeRO-2 with gradient checkpointing reduces memory overhead. The decoder is fine-tuned separately for 3,000 steps at batch size 64 with learning rate 1 × 10⁻⁵.
Why This Matters
Impact on research: The paper reframes high-resolution multi-view diffusion efficiency as a data-structure problem rather than only an attention-kernel problem. Instead of optimizing attention within an unchanged full token sequence, it removes the tokens that should never have been computed in the first place, then combines this with sparse attention over the shortened sequence. It also releases a dataset at a scale and resolution the field lacked, lowering the barrier for future work on 2K and higher texturing.
Real-world applications:
- Game development pipelines needing production-ready textured assets at high detail.
- Film and visual effects production, where texture fidelity and rendering under novel lighting conditions matter.
- Spatial computing and AR/VR, where assets must hold up under varied viewing angles and illumination.
- E-commerce and product visualization, where a single reference photo could drive a fully textured 3D object.
Industry relevance: The reported 20.6×–91.1× training and 22.3×–74.6× inference speedups directly affect cost of ownership for anyone training or serving high-resolution texturing models. The relighting track is especially relevant for industries that need assets whose albedo holds up under new lighting rather than baked-in lighting from the input image.
Future Directions
- Handle repetitive texture patterns: The authors report failure cases on objects with highly repetitive patterns; a remedy is not described in the provided content.
- Reduce dependence on the pretrained FLUX backbone: The limitations section states the framework is inherently constrained by the capability of the pretrained FLUX model, but the paper content truncates mid-sentence before these aspects are enumerated.
- Explore more aggressive sparsity settings: The retention ratio analysis shows a clear quality–efficiency trade-off, with ρ = 5% causing noticeable degradation; adaptive or content-dependent retention policies are a natural extension.
- Expand the dataset further: G-buffer TexVerse already covers over 268,000 assets at up to 4096 × 4096, but training currently uses only normal maps as geometry conditions and resizes views to 2048 × 2048, leaving the other G-buffer attributes unused.
Target Audience
Researchers and engineers working on 3D asset generation, diffusion models, and efficient transformer inference. It is most useful to readers already comfortable with diffusion transformers and Flow Matching who want to understand how to make very long multi-view sequences tractable, and to practitioners who need high-resolution textured assets and are weighing the cost of training or deploying such a system. Readers interested in dataset construction for 3D generation will also find the G-buffer TexVerse description valuable, though the paper notes that detailed curation, rendering protocol, organization, and statistics are provided in the supplementary material rather than the main text.
Authors’ abstract
High-quality texture generation is essential for creating realistic and production-ready 3D assets. Recent multi-view diffusion methods have shown promising results for image-guided 3D texturing, but they are typically constrained to low operating resolutions such as 512 or 768, making it difficult to preserve high-frequency details from high-resolution reference images. Scaling this paradigm to 2048 resolution is computationally prohibitive, as the unified multi-view sequence exceeds 212K tokens and incurs excessive memory and latency. In this paper, we present UltraTex, an efficient end-to-end framework for high-resolution multi-view diffusion-based 3D texturing. Our key observation is that object-centric multi-view renderings contain two major sources of redundancy: background-induced sequence redundancy and sparse token interactions within the foreground. To address them, we introduce Background Token Dropping, which removes background tokens before the DiT backbone, and Block-Sparse Attention, which reduces attention computation over the retained foreground sequence. To enable efficient foreground-only inference while avoiding reconstruction artifacts, we further design Foreground-Aware VAE Decoding to ensure the quality of the final high-resolution views. To satisfy the demanding data requirements of 2K-resolution multi-view diffusion training, we construct G-buffer TexVerse, a large-scale, ultra-high-resolution multi-view rendering dataset covering over 268,000 3D assets. Extensive experiments show that UltraTex generates visually faithful textures with rich fine-grained details, while substantially improving efficiency, achieving $20.6\times$--$91.1\times$ training speedup and $22.3\times$--$74.6\times$ end-to-end inference speedup over the baseline on common samples in our dataset. Code and data is at https://yiboz2001.github.io/UltraTex.