Research
Scaffolding Foundation Models into Physical-World Agents Pushes the Frontier of Long-Horizon Navigation
Overview Research area: Embodied AI — specifically long-horizon navigation agents built by combining vision-language models (VLMs) with navigation foundation models (NFMs), evaluated on Embodied Quest
- arXiv
- 2608.30396
- Published
- 2026-08-31
- Authors
- Zixing Lei, Gengze Zhou, Xiong-Hui Chen, Jiazhao Zhang, Yiyang Huang, Hang Yin, Haoqi Yuan, Qi Wu, Weixin Li, Siheng Chen
AI summary
Overview
Research area: Embodied AI — specifically long-horizon navigation agents built by combining vision-language models (VLMs) with navigation foundation models (NFMs), evaluated on Embodied Question Answering (EQA).
Technical level: Advanced. The paper assumes familiarity with VLM agent scaffolds, tool-calling interfaces, navigation foundation models, and EQA benchmarks.
Scope: The paper introduces NavMCP, an agentic scaffolding framework that couples a VLM reasoning agent with an NFM executor through three communication channels, and evaluates it on three simulated EQA benchmarks plus a Unitree Go2 robot.
What This Paper Is About
Today's foundation models split the capabilities needed for long-horizon physical tasks: VLMs can reason about what information is missing and revise high-level plans, but repeatedly turning those plans into navigation actions is brittle and inefficient, while navigation foundation models execute semantic goals robustly but run as one-off bounded episodes with no persistent task-level reasoning. The paper argues these limitations are complementary and builds NavMCP, a scaffold in which the VLM decides what evidence to seek, where to search, and when to stop, while the NFM grounds each semantic sub-goal into closed-loop navigation. The goal is persistent physical-world agency without retraining either foundation model.
Key Contributions
-
NavMCP framework: An agentic scaffolding framework that organizes the complementary capabilities of a VLM reasoning agent and an NFM executor into a single long-horizon physical-world agent. The NFM extends the VLM's action horizon; the VLM extends the NFM's reasoning horizon.
-
Evidence-centric three-channel design: An intent channel (evidence need to semantic navigation call), an observation channel (complete rollout to source-grounded journey evidence), and a memory channel (accumulated findings, negative evidence, and unresolved goals across calls). Together these close the "episodic interface gap" — the mismatch between route instructions and evidence-seeking intent, intermediate observation loss, and the lack of cross-call accumulation.
-
State-of-the-art simulated results: Evaluation on HM-EQA, MT-HM3D, and EXPRESS-Bench, with controlled ablations isolating the value of the protocol itself, including a matched comparison against an episodic interface under identical agent and executor backbones.
-
Real-robot validation: Deployment on a Unitree Go2 reaching 78.3% overall success in multi-room search, with the margin over the strongest baseline growing from 10 to 45 points as the task horizon increases.
Main Findings
-
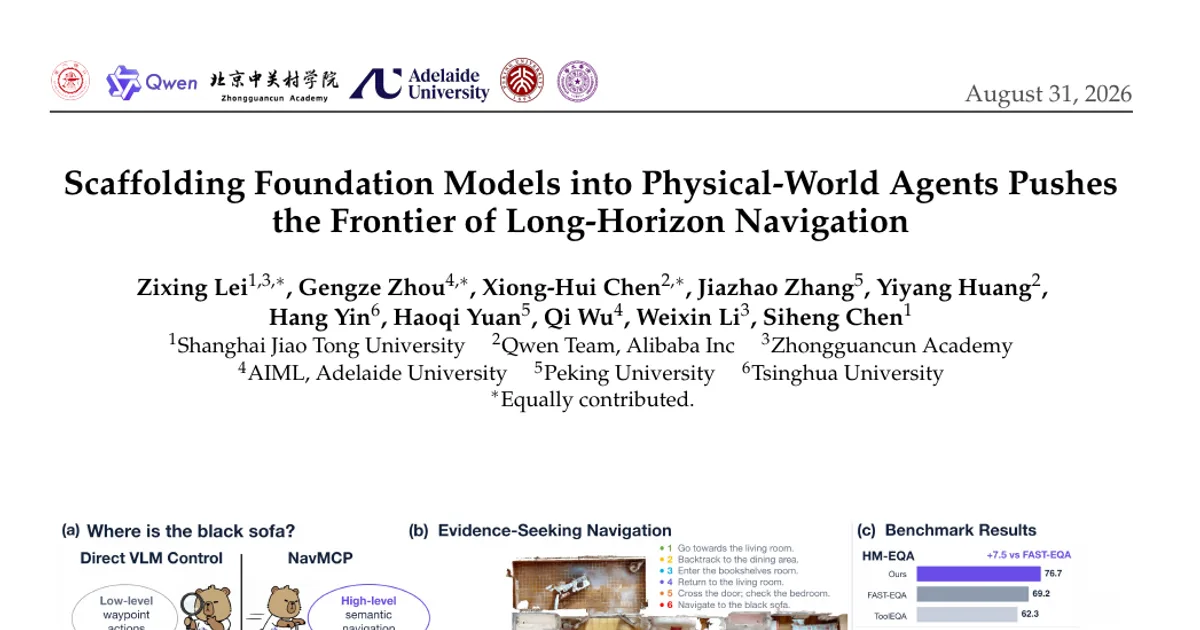
Cross-benchmark accuracy: NavMCP reaches 76.7% (± 0.1) on HM-EQA, 54.4% (± 1.5) on MT-HM3D, and an LLM Score of 79.27 (± 0.44) with an E_path of 33.96 (± 0.75) on EXPRESS-Bench. Reported comparison figures are FAST-EQA at 69.2%, 50.5%, and 68.7 / 29.25 respectively.
-
Gains over FAST-EQA: 7.5 percentage points on HM-EQA, 3.9 points on MT-HM3D, and 10.57 LLM Score plus 4.71 E_path points on EXPRESS-Bench.
-
Efficiency improves alongside accuracy: Using the paper's normalized equivalent agent-step metric (outer VLM invocations plus an extra charge per additional 3 m segment of NFM rollout), NavMCP reports the lowest normalized step fractions among reporting methods on HM-EQA and MT-HM3D at 0.15 (± 0.01) and 0.19 (± 0.01), versus 0.65 and 0.52 for FAST-EQA.
-
Matched-backbone comparison: With the same Qwen3.5-397B-A17B agent, episodes, initial states, and budget, NavMCP with Qwen-RobotNav-8B reaches 74.0% (± 0.3), versus 57.6% (± 0.7) for re-evaluated Explore-EQA, 60.8% (± 0.9) for a reproduced ToolEQA, and 63.5% (± 1.4) for a reproduced FAST-EQA — leads of 16.4, 13.2, and 10.5 points.
-
The episodic interface gap is costly: Replacing the full three-channel protocol with a plain episodic tool interface drops accuracy from 74.0% to 59.1%, a loss of 14.9 points with agent and executor backbones held fixed.
-
Channel-level effects: Terminal-only observation return costs 5.9 points; removing the EQA context state costs 4.6 points; removing journey analysis costs 4.4 points; sparser keyframes cost 2.8 points; restricting to a single navigation mode costs 2.0 points; removing context compaction costs 0.9 points; removing the zoom_in_object verification tool costs 0.6 points.
-
Agent and executor are complementary, not substitutable: With Qwen-RobotNav-8B fixed, accuracy rises from 38.2% (no agent) to 58.4% (single-round agent) to 62.0% (reactive agent) to 74.0% (full Qwen3.5-397B-A17B) to 76.7% (Qwen3.6-Plus). With the full Qwen3.5 agent fixed, it rises from 60.9% (Random Walk) to 65.3% (Frontier Exploration) to 69.3% (StreamVLN) to 73.3% (Qwen-RobotNav-4B) to 74.0% (Qwen-RobotNav-8B). The 4B-to-8B difference of 0.7 points is reported only as a scaling trend because of stochastic hosted-LLM runs.
-
Category-level profile on HM-EQA: Existence 80.6%, Identification 80.2%, Location 78.5%, State 77.2%, Count 65.0%. On MT-HM3D, relationship questions reach 63.9% and comparison questions 59.6%.
-
Real-robot success scales with horizon: On a Unitree Go2 across three tiers of 20 episodes each (single-room, cross-room, over 20 m), NavMCP with Qwen-RobotNav scores 90 / 85 / 60 and 78.3% overall, versus 70 / 60 / 15 and 48.3% for NavMCP with frontier exploration, and 80 / 35 / 0 and 38.3% for the reactive baseline. Margins over the strongest baseline grow from 10 to 25 to 45 points.
-
Evidence-driven search is deliberately non-monotonic: In the reported Explore-EQA example (finding a small black sofa), the agent records negative evidence in five rooms, moves away from the goal to rule out plausible regions, then issues an object-targeted final call, over a 25-turn tool-call timeline.
Methodology in Plain English
The system splits an embodied task into two layers. The upper layer is a VLM agent that reads the question and the current state and either commits to an answer or emits an "evidence need." The lower layer is a navigation foundation model, here Qwen-RobotNav, which takes a natural-language sub-goal plus the current egocentric observation and state and outputs a short-horizon waypoint trajectory.
Three channels connect them. The intent channel converts an evidence need into a structured call with a mode (navigate_to_object for object navigation, navigate_by_instruction for vision-and-language navigation), a sub-goal, a step budget, and optional constraints — so the agent specifies what to seek without micromanaging control. The observation channel samples keyframes along the whole trajectory, not just the final pose, and a VLM summarizer turns them into a journey artifact covering sub-goal status, route context, observed objects, planning cues, and uncertainty, with each object or room mention tied to a source keyframe and a confidence label. The memory channel maintains an EQA context state of (interaction history, evidence ledger, unresolved goals), updated before any raw tool output is compressed, so long contexts shrink around persistent source-grounded evidence rather than raw traces.
Evaluation uses three benchmarks stressing different evidence-gathering demands: HM-EQA (500 multiple-choice questions across 267 HM3D scenes), MT-HM3D (multi-target questions requiring cross-room comparison), and EXPRESS-Bench (2,044 free-form questions scored by LLM Score and E_path). Controlled ablations fix the agent, executor, perception tools, episodes, initial states, and budgets while changing one factor at a time. The real-robot study holds the Qwen3.6-Plus agent fixed and varies orchestration and executor, with each tier containing 20 episodes.
Why This Matters
Impact on research: The paper reframes the problem from "build a better reasoner or navigator" to "organize complementary foundation models into persistent agency." Its episodic interface gap analysis — intent mismatch, observation loss, no cross-call accumulation — gives a concrete diagnostic for why tool-style wrappers of navigation models underperform, and its 14.9-point matched ablation quantifies that diagnosis. The three-channel protocol is presented as executor-agnostic: any navigation model supporting the same intent modes and return format can be swapped in, which the paper demonstrates across Random Walk, Frontier Exploration, StreamVLN, and two Qwen-RobotNav scales.
Real-world applications:
- Home and assistive robots that must search multiple rooms for an object before answering a question about it.
- Service robots in retail, hospitality, or hospitals that need to locate evidence ("is the coffee maker on the counter?") rather than follow one fixed route.
- Industrial or warehouse inspection, where an agent must cover regions, record what it saw and did not see, and decide when coverage is sufficient.
- Search-and-rescue style multi-room coverage, where negative evidence and unresolved goals must persist across repeated search passes.
Note that the paper's only reported physical deployment is a Unitree Go2 in multi-room search; other applications are implications of the framework, not experiments run here.
Industry relevance: The approach requires no retraining of either foundation model, which lowers the barrier to combining an existing VLM API with a pretrained navigation policy. The paper's step-accounting metric — outer VLM invocations as the dominant wall-clock cost, with 3 m as the direct-control conversion unit — is directly relevant to teams reasoning about inference cost versus coverage in deployed agents. The paper explicitly notes that relying on a large VLM slows inference, and that smaller agents or distillation may reduce that cost.
Future Directions
-
Cost reduction: The paper states NavMCP relies on a large VLM, slowing inference, and suggests smaller agents or distillation as a remedy. No latency or compute measurements are reported in the provided content.
-
Better counting and cross-view reasoning: Counting is the weakest HM-EQA category at 65.0%, attributed partly to multiple keyframes containing overlapping views of the same object. The paper calls for stronger cross-view object association and uncertainty tracking.
-
Agent-directed data collection: The authors propose that agents could use navigation foundation models to explore environments and efficiently collect embodied data for training spatial intelligence, coupling high-level reasoning with grounded observations and trajectories.
-
Broader protocol generalization: The protocol is specified to require only source-grounded evidence updates, but it is instantiated and evaluated on EQA alone. Extending it to other embodied tasks, and hardening the semantic interface so more executors can plug in unchanged, remains open. Cross-paper comparisons in the main table are described as contextual only, since full alignment across implementations was not possible.
Target Audience
Researchers and engineers working on embodied AI, vision-language navigation, and agentic tool use, particularly those building long-horizon robotic agents that combine a reasoning model with a learned navigation policy. The paper is most useful to readers already comfortable with EQA benchmarks and navigation foundation models; its protocol ablations and step-accounting metric will matter most to teams making architectural tradeoffs between reasoning cost and navigation coverage. Readers looking for beginner-level background on VLMs, NFMs, or EQA terminology will need supplementary reading.
Authors’ abstract
Long-horizon physical-world agents must reason over distant goals while grounding decisions in reliable closed-loop behavior. Today's foundation models split these capabilities: vision-language models (VLMs) infer missing information and adapt high-level plans but remain brittle and inefficient at repeated navigation grounding, while navigation foundation models (NFMs) robustly execute semantic goals but operate as bounded episodes without persistent task-level reasoning. We introduce NavMCP, an agentic scaffolding framework that couples a VLM reasoning agent with an NFM executor for long-horizon exploration. The VLM decides what evidence to seek, where to search, and when to stop, while the NFM grounds each semantic sub-goal into closed-loop navigation. Three channels structure their collaboration: intent translates evidence needs into navigation calls, observation converts rollouts into source-grounded trajectory evidence, and memory accumulates findings, negative evidence, and unresolved goals across calls. This design turns isolated navigation rollouts into persistent embodied interaction without retraining either model. On Embodied Question Answering, NavMCP achieves state-of-the-art results on HM-EQA, MT-HM3D, and EXPRESS-Bench. Under matched agent and executor backbones, it outperforms an episodic interface by 14.9 percentage points on HM-EQA. On a Unitree Go2, NavMCP reaches 78.3% success, with its margin over the strongest baseline growing from 10 to 45 points as the task horizon increases. These results demonstrate the potential of scaffolding complementary foundation models into long-horizon physical-world agents.