Research
RuleTrek: Benchmarking Agentic Rule Reasoning in Complex Scenarios
Overview Research area: AI agent evaluation — specifically rule-based reasoning in LLM agents operating over documents and files. Technical level: Intermediate. The paper is a benchmark and evaluation
- arXiv
- 2610.19698
- Published
- 2026-10-14
- Authors
- Chenhao Yuan, Bohan Yu, Yinhao Xu, Chao Yin, Chenxi Zhou, Zhaoxuan Wang, Shuwen Xu, Shaoping Huang, Haolin Ren, Jiaxiang Liu, Yao Xu, Jun Zhao, Kang Liu
AI summary
Overview
Research area: AI agent evaluation — specifically rule-based reasoning in LLM agents operating over documents and files.
Technical level: Intermediate. The paper is a benchmark and evaluation study; readers need familiarity with LLM agents, tool use, and benchmark design conventions, but no deep mathematical background.
One-sentence scope: RuleTrek is a 240-instance, six-domain benchmark that tests whether LLM agents can find the right domain-specific rules inside heterogeneous rule repositories and correctly apply them to solve problems whose evidence is spread across many files.
What This Paper Is About
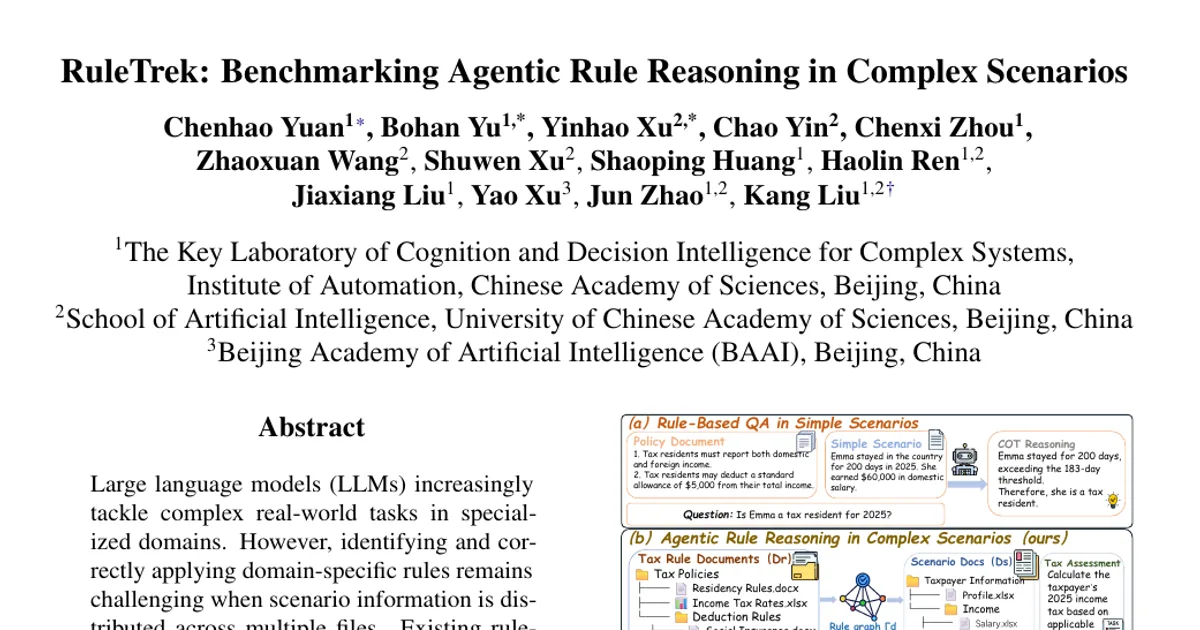
Existing rule-reasoning benchmarks usually describe a scenario with only a few factual statements, which makes it easy for a model to spot which rule applies. Real work is harder: tax assessment, for instance, requires pulling a taxpayer's profile, salary records, and royalty income out of separate files before the correct residency, rate, and deduction rules can even be identified. RuleTrek was built to close that gap by creating complex, multi-file scenarios grounded in real rule repositories, and by measuring agents on rule identification, rule deduction, and the two combined.
Key Contributions
- A multi-domain benchmark for agentic rule reasoning. RuleTrek provides 240 instances across six domains — taxation, PostgreSQL, cybersecurity, software policy, procurement, and game rules — where agents work in interactive workspaces with file and shell access and must retrieve distributed information, identify applicable rules, and apply them.
- A rule-grounded scenario construction pipeline. The pipeline (1) extracts structured rule graphs from real-world rule repositories, (2) generates a sub-scenario for each individual rule that requires that rule to be applied, and (3) incrementally composes sub-scenarios along rule dependencies while checking consistency and solvability at every step, with human verification throughout.
- Three separate evaluation settings. Rule Identification (RI), Rule Deduction (RD), and End-to-End Rule Reasoning (E2E) isolate different failure sources by varying whether the verified rule graph is supplied and whether a final answer is required.
- An empirical study of 11 frontier LLMs plus reliability checks. The paper reports per-domain scores, analyzes how rule-graph complexity degrades performance, classifies failure modes, and validates the automatic judge against human annotators and two additional judge models.
Main Findings
- Rule identification is far from solved: The highest average RI score is 62.47% (GPT-6.1-Sol), followed by Grok-4.7 at 61.86% and GPT-5.5 at 60.20%. The lowest is Gemini-2.5-Flash at 33.35%.
- Applying provided rules is also hard: Even with the verified rule graph handed to the agent, the best average RD score is only 60.43% (GPT-6.1-Sol), with DeepSeek-V4.1-Flash at 56.39% and Grok-4.7 at 56.12%.
- End-to-end scores are the weakest: E2E scores range from 26.97% (Gemini-2.5-Flash) to 55.29% (GPT-6.1-Sol). GPT-6.1-Sol also leads Grok-4.7 (51.34%), DeepSeek-V4.1-Flash (50.06%), DeepSeek-V4-Pro (49.07%), GLM-5.3-Flash (47.16%), Gemini-3.7-Flash (46.26%), GPT-5.5 (45.47%), Qwen3.8-Flash (44.59%), HY3 (39.47%), and GPT-6-Luna (34.36%).
- Domain difficulty varies sharply: For example, GPT-6.1-Sol reaches 85.89% E2E on Tax and 71.99% on Game, but only 26.92% on Procurement and 25.49% on PostgreSQL. Gemini-2.5-Flash falls to 9.21% RI and 11.55% RD on PostgreSQL.
- Performance falls as rule graphs grow: Mean E2E across 11 models drops from 76.5 to 23.6 when rule-node count rises from at most 3 to at least 14, and from 62.3 to 26.4 when rule-graph depth rises from at most 1 to at least 5.
- Identification adds measurable difficulty on top of deduction: RD outperforms E2E by 3.79–8.15 points across seven models, yet RD itself stays limited even though the correct rules are provided.
- Rule selection is the dominant error: Classifying GPT-6.1-Sol's failed trajectories by earliest decisive error yields four categories — retrieval misses, rule-selection errors, reasoning errors, and final-synthesis errors — with rule-selection errors accounting for 54.9% of failures.
- More interaction is not better: GPT-6.1-Sol reaches the top E2E score of 55.29% with relatively few steps, while Gemini-3.7-Flash and Qwen3.8-Flash use considerably more steps for 46.26% and 44.59%; GLM-5.3-Flash uses fewer steps than most models but scores only 47.16%.
- Output length does not predict success: Appendix B.1 reports no consistent correlation between average output tokens per task and E2E performance.
- State tracking matters: In one game scenario, GPT-6.1-Sol correctly treats a protective ward as consumed on first trigger and finishes in 34 steps, while Qwen3.8-Flash retrieves the same protection rule but keeps the ward active, producing a wrong answer after 57 steps.
- Scoring is reasonably reliable: Human–judge Spearman correlations range from 0.822 to 0.857, versus 0.933–0.951 for human–human agreement. Rescoring with GLM-5 and Gemini-2.5-Pro gives submission-level Spearman correlations of 0.903–0.934 and model-ranking correlations of 0.955–0.991.
- Benchmark quality was human-verified: Five criteria (answerability, answer uniqueness, rule alignment, scenario consistency, difficulty validity) show Cohen's kappa of 0.85–0.93 (average 0.89) and initial pass rates of 79.6%–91.7% (average 86.1%). After the multi-round quality control, pass rates went from 184/240 (76.7%) at initial review to 228/240 (95.0%) after revision to 240/240 (100%) at final validation.
Methodology in Plain English
The team started from real rule repositories — sources such as NIST materials, PostgreSQL documentation and tooling, Open Contracting Partnership standards, Kyverno and Open Policy Agent policies, GitHub policy, and IRS tax computation systems — spanning the six target domains. All LLM-based construction steps used GPT-6-Astra.
For each domain, an LLM extracted a structured rule graph whose nodes are individual rules and whose edges encode relationships like applicability dependencies, eligibility conditions, aggregation, exceptions, overrides, precedence, and temporal constraints. Human experts then checked the extracted rules, source references, and dependencies against the originals.
Rather than generating one big scenario and hoping it exercises the right rules, the pipeline builds a separate sub-scenario for each rule, expressed through files typical of that domain — spreadsheets, configuration files, logs, forms, messages, tables, or source code. These sub-scenarios are then composed incrementally along the rule dependencies: adding a new sub-scenario often forces edits to existing files so that entities, timestamps, states, versions, units, and cross-file references stay aligned. After every composition step, human experts verify consistency and solvability, and the process only proceeds once both pass. The final scenario yields a question and answer that experts solve using the original rules to confirm answerability, answer uniqueness, and rule compliance.
Evaluation runs in isolated workspaces through the pi CLI, with file and shell access but no external network, a 30-minute limit, and a maximum of 200 agent steps. Each model runs three times at temperature 1 and scores are averaged. The judge is gpt-5.6-luna at temperature 0: for RI it scores the correctness of the identified rule set and the logical validity of the stated relationships; for RD and E2E it scores answer correctness and a reasoning score across fact grounding, rule application, computation, and evidential support, with the final score being the product of binary answer correctness and the reasoning score. Scores are on a 0–100 scale, averaged over 240 instances, with failed or missing submissions assigned zero.
The dataset statistics: 240 instances total, 30–48 per domain (Cybersecurity 38, Game 45, PostgreSQL 30, Procurement 42, Software 37, Tax 48). Operative rule graphs average 9.05 nodes and 8.69 edges with a mean depth of 2.69 edges; PostgreSQL has the largest average graphs at 13.90 nodes, 13.07 edges, and 4.10 depth, while Cybersecurity is the smallest at 7.05 nodes, 6.18 edges, and 1.55 depth.
Why This Matters
RuleTrek changes the difficulty profile of rule-reasoning evaluation: prior benchmarks hand models a handful of factual statements, whereas RuleTrek forces them to locate the evidence across heterogeneous files and to recover rule dependencies rather than matching rules by semantic similarity. The result is a diagnostic picture of where agents fail — most often in choosing the right rule set, not in retrieving evidence.
Real-world applications:
- Tax assessment: integrating taxpayer profiles, salary records, and royalty income to identify residency, rate, and deduction rules — the paper's own motivating example.
- Regulatory and security compliance: mapping network flows, remote-access records, and exception documents to specific control enhancements, as in the cybersecurity instances.
- Database operations: reasoning about configuration settings, synchronization state, and failover conditions in PostgreSQL replication and recovery tasks.
- Procurement and software policy enforcement: resolving hierarchical rule scopes and parameterized policy conditions tied to API versions, resource types, and configurable thresholds.
Industry relevance: any organization deploying LLM agents to answer questions governed by written rules — tax, audit, compliance, platform policy, IT operations — gets a benchmark that more closely matches production conditions, plus evidence that supplying the correct rules (the RD setting) is necessary but not sufficient for success.
Future Directions
- Extending beyond English: the paper notes RuleTrek is limited to English-language rule repositories and scenarios, and suggests multilingual settings as an extension.
- Moving to dynamic environments: the authors propose environments where rules and scenario information evolve over time, rather than the fixed, reproducible repositories currently used.
- Reducing rule-selection errors: since rule-selection mistakes are the single largest failure category at 54.9% of GPT-6.1-Sol's failed E2E trajectories, targeted methods for distinguishing rules with similar descriptions but different applicability conditions are an obvious target.
- Improving state tracking after rule application: the paired trajectory examples show that agents can retrieve the correct rule yet fail to maintain consistent evolving states, which current benchmarks now make measurable.
Target Audience
Researchers building and evaluating LLM agents, benchmark designers working on reasoning or tool-use evaluation, and practitioners in compliance-heavy domains (tax, audit, cybersecurity, procurement, platform policy) who need to know how far current agents can be trusted with rule-governed decisions.
Authors’ abstract
Large language models (LLMs) increasingly tackle complex real-world tasks in specialized domains. However, identifying and correctly applying domain-specific rules remains challenging when scenario information is distributed across multiple files. Existing rule-reasoning benchmarks typically represent scenarios using only a few factual statements, simplifying the identification and application of relevant rules. To address this gap, this paper introduces \textbf{RuleTrek}, a multi-domain benchmark for agentic rule reasoning in complex scenarios. Its rule-grounded construction pipeline extracts structured rule graphs, generates and incrementally composes rule-specific sub-scenarios while ensuring consistency and solvability. To systematically evaluate agentic rule reasoning in complex scenarios, RuleTrek assesses three capabilities in interactive workspaces: Rule Identification (RI), Rule Deduction (RD), and End-to-End Rule Reasoning (E2E). Experiments on 11 frontier LLMs show that the highest RI and RD scores are only 62.47\% and 60.43\%, respectively, while E2E scores range from 26.97\% to 55.29\%. These results demonstrate that current LLM agents face substantial challenges in rule reasoning over complex scenarios. We make our code and dataset publicly available at \href{https://github.com/yuan247/RuleTrek}{RuleTrek}.