Research
Right Looks, Wrong Reasons: Compositional Fidelity in Text-to-Image Generation
Overview Research area: Computer vision / text-to-image (T2I) generation, specifically compositional reasoning and constraint satisfaction. Technical level: Intermediate (a survey with some formal not
- arXiv
- 2511.10136
- Published
- 2025-11-13
- Authors
- Mayank Vatsa, Aparna Bharati, Richa Singh
AI summary
Overview
- Research area: Computer vision / text-to-image (T2I) generation, specifically compositional reasoning and constraint satisfaction.
- Technical level: Intermediate (a survey with some formal notation, but the argument is accessible).
- Scope: This survey examines why state-of-the-art text-to-image models fail at logical composition across three primitives — negation, counting, and spatial relations — and why their failures compound when the primitives are combined.
What This Paper Is About
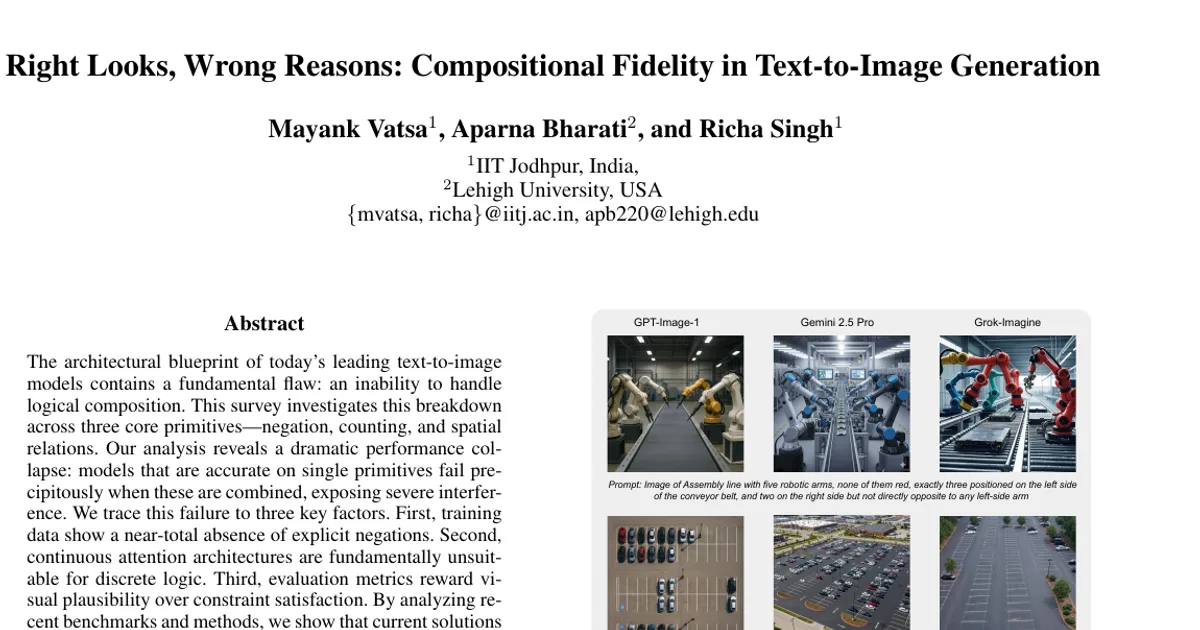
Text-to-image systems like DALL·E 3, Stable Diffusion, Imagen, and Parti produce photorealistic images but systematically fail to satisfy combinations of constraints such as counting, attribute binding, spatial relations, and negation. A prompt like "exactly three red apples to the left of a vase with no flowers" is trivial for a human but challenging for these models, and performance drops sharply once individually solvable constraints are combined. The paper's goal is to diagnose the causes of this breakdown, survey the benchmarks and methods proposed to address it, and argue that current solutions and simple scaling cannot close the gap.
Key Contributions
- A formal account of the intersectional failure, explaining why progress on isolated primitives does not extend to joint prompts, connected to constrained optimization and combinatorial hardness.
- A synthesis of methods organized by primitive: data augmentation and contrastive training for negation; architectural strategies and mixture-of-experts for counting; layout and structural control for spatial relations; and hybrid neural-symbolic pipelines for joint composition.
- A review of 15 benchmarks, charting the shift from human studies to automated and adversarial evaluations, with discussion of their strengths, biases, and gaps.
- A proposed research direction spanning theory, architecture, training, and evaluation to bridge visual plausibility and logical faithfulness.
Main Findings
- Performance collapse under combination: Models that are accurate on single primitives fail precipitously when primitives are combined, exposing severe interference. Joint failure rates are consistently higher than single-primitive failure rates.
- Quantified interference: Defining compositional faithfulness as the probability that all constraints in a prompt are satisfied, the paper measures interference as the ratio of actual joint performance to the product of individual rates (independence). Ratios below 1 indicate intersectional failure, with the paper treating interference as pronounced at or below a threshold such as 0.75.
- Illustrative compounding example: If each of three primitives succeeds at 70%, independence predicts 0.7³ = 34.3% joint faithfulness; with observed interference of approximately 0.58, actual performance falls to approximately 20%.
- Super-linear counting errors: Accuracy degrades as the target number increases, and the degradation is not gradual — error growth fits a power law with exponent β in [1.2, 1.5] across multiple benchmarks.
- Negation is rare in training data: Explicit negation appears in roughly 0.4% of MS COCO captions, 1.63% of CC3M, approximately 2.5% of CC12M, and approximately 0.6% of LAION-400M; LAION-2B and DataComp-1B show similar sub-percent to low single-digit rates depending on cues such as "no/not/without."
- Other primitives are also sparse: High-count scenes (n > 5) appear in under 2% of samples, and complex spatial arrangements with multiple relations constitute less than 5%, making joint cases vanishingly rare.
- Three root causes: (1) training data show a near-total absence of explicit negations; (2) continuous attention architectures are fundamentally unsuitable for discrete logic; (3) evaluation metrics reward visual plausibility over constraint satisfaction.
- Combinatorial hardness: Satisfying combined constraints is NP-hard in the general case. With n objects, m spatial relations, and k negation constraints, the search space grows as O(n! · 2^m · C(n,k)). Current models use greedy local search, producing characteristic failures: objects meet local constraints but break global consistency, counts hold until layout is enforced, and negation applies to the wrong scope when combined with relations.
- Regularization dominates: In the composite scoring view, the visual realism/regularization term dominates when compositional requirements conflict with learned priors, explaining why models generate plausible yet unfaithful images.
- Existing methods have limits: Structural approaches for negation generally outperform data-driven contrastive methods, which struggle with complex negation and are prone to bias or overfitting from synthetic augmentations. Counting improvements from architectural changes are often limited to a small number of objects. Layout-based spatial methods require additional structural inputs that may not scale to complex scenes.
- Scaling is not sufficient: Larger models show marginal gains on isolated primitives but suffer the same performance collapse on joint tasks, pointing to a deeper architectural limitation.
- Benchmark landscape: Fifteen major benchmarks spanning 2022–2025 shift from human evaluation (DrawBench, PartiPrompts) to automated evaluation at scale (T2I-CompBench, CREPE with 370K+ variations) and adversarial/VQA-based probing. Critical gaps remain, including temporal reasoning and complex multi-object interactions.
Methodology in Plain English
This is a survey rather than an empirical study, so the researchers worked by analysis and synthesis rather than by running new experiments. They structured the problem around compositional primitives — the semantic mechanisms that combine to specify a scene — and selected three to examine in depth: negation, counting, and spatial relations. For each primitive, they described how it appears linguistically in prompts, gave a formal statement of what satisfying it requires, catalogued the recurring failure patterns reported in prior work, and reviewed the methods proposed to fix it. They then formalized joint compositionality by comparing observed joint success against the product of individual success rates, quantifying interference and connecting the combined constraint problem to constrained optimization and known combinatorial hardness results. Finally, they assembled and compared fifteen benchmarks, noting what each measures and where the coverage is thin, before summarizing open challenges in theory, evaluation, architecture, and training.
Why This Matters
- Impact on research: The paper reframes compositional failure as a structural mismatch between continuous architectures and discrete logic rather than a data or scale problem, arguing that closing the submultiplicative gap requires fundamental advances in representation and reasoning rather than incremental adjustments.
- Educational platforms cannot reliably render illustrations with specific counts.
- Technical documentation tools misplace components in assembly diagrams.
- Scientific and medical illustration can show anatomically or physically impossible results under too many constraints; a prompt like "no fracture" failing yields misleading imagery, as does a mis-grounded relation such as "lesion left of the hippocampus."
- Industry relevance: Compositional fidelity is presented as a prerequisite for reliable and trustworthy deployment. Iterating extensively to reach a desired composition undermines direct language control and hinders adoption in high-stakes domains.
Future Directions
- Theoretical foundations: Establish computational lower bounds for faithful composition and formally characterize which compositional patterns are learnable from data; explore connections to classical constraint satisfaction such as SAT solving and neuro-symbolic methods.
- Evaluation methodology: Address the weak correlation between existing metrics and human compositional assessment on complex multi-constraint prompts, resolve natural-language ambiguity in ground truth, and handle occlusion and viewpoint variation; characterize the poorly understood trade-off between aesthetic quality and compositional fidelity.
- Architectural innovations: Develop modular architectures that decouple reasoning from generation, memory-augmented networks for explicit state, and hierarchical models separating "what," "where," and "how many"; learn structured representations from text alone rather than relying on costly layout and scene-graph annotations.
- Training paradigms: Align objectives that currently optimize average-case performance with compositional requirements demanding worst-case guarantee on logical constraints, without the catastrophic forgetting and distribution shift that affect primitive-targeted augmentation; also, better benchmarks that measure compositional generalization rather than memorization.
- Extension beyond the three primitives: Techniques developed for negation, counting, and spatial relations are expected to extend to temporal reasoning, causal relations, and abstract concepts — including the temporal reasoning and complex multi-object interactions the paper identifies as missing from current benchmarks.
Target Audience
Researchers and practitioners working on text-to-image generation, vision-language models, and multimodal evaluation; engineers deploying generative models in domains where constraint satisfaction matters (education, technical documentation, scientific and medical imaging); and students or newcomers seeking a structured, primitive-based entry point into compositional reasoning, since the survey connects formal definitions, failure taxonomies, method families, and benchmarks in one place.
Authors’ abstract
The architectural blueprint of today's leading text-to-image models contains a fundamental flaw: an inability to handle logical composition. This survey investigates this breakdown across three core primitives-negation, counting, and spatial relations. Our analysis reveals a dramatic performance collapse: models that are accurate on single primitives fail precipitously when these are combined, exposing severe interference. We trace this failure to three key factors. First, training data show a near-total absence of explicit negations. Second, continuous attention architectures are fundamentally unsuitable for discrete logic. Third, evaluation metrics reward visual plausibility over constraint satisfaction. By analyzing recent benchmarks and methods, we show that current solutions and simple scaling cannot bridge this gap. Achieving genuine compositionality, we conclude, will require fundamental advances in representation and reasoning rather than incremental adjustments to existing architectures.