Research
Once a Tree, Always a Tree? Cross-lingual Transfer of Hierarchical Generalization in Language Models
Overview Research area: Natural Language Processing — cross-lingual transfer, inductive bias, and the linguistic competence of language models (syntax acquisition, subject–verb agreement, the poverty-
- arXiv
- 2610.30960
- Published
- 2026-10-22
- Authors
- Shin Yamaguchi, Masaya Taniguchi, Tatsuki Kuribayashi, Taro Watanabe, Yoshinobu Kano
AI summary
Overview
Research area: Natural Language Processing — cross-lingual transfer, inductive bias, and the linguistic competence of language models (syntax acquisition, subject–verb agreement, the poverty-of-stimulus paradigm).
Technical level: Intermediate. The paper is readable with basic familiarity with language-model pretraining and minimal-pair evaluation, but the experimental design (counterfactual L1/L2 corpora, Bayesian mixed-effects analysis) rewards a reader who knows the hierarchical-vs-linear agreement literature.
Scope: The paper asks whether a hierarchical syntactic rule learned from one language (L1) can transfer to a second language (L2) when the L2 data alone are ambiguous, and whether any such transfer depends on shared vocabulary between the two languages.
What This Paper Is About
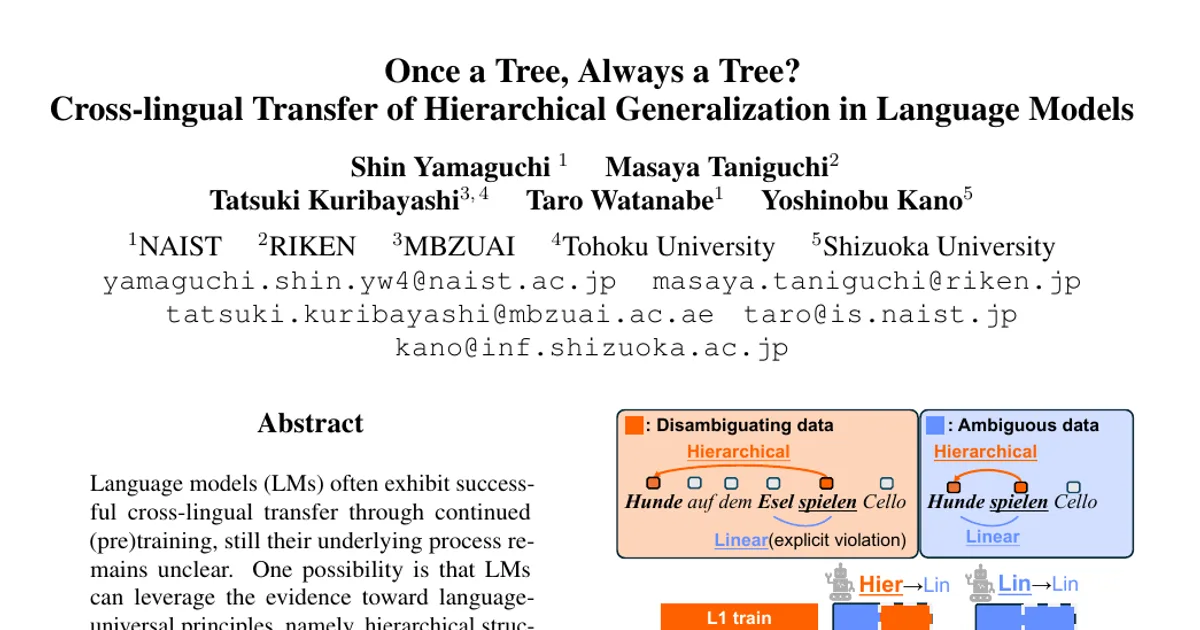
Language models trained on one language often improve on another, but it is unclear whether this reflects transfer of an abstract, language-universal property such as hierarchical structure, or something non-linguistic such as more data or better-initialized position embeddings. The authors build a controlled cross-lingual "poverty-of-stimulus" setting in which positive evidence for a hierarchical grammar rule exists only in the L1 corpus, and the L2 corpus is deliberately ambiguous between a hierarchical and a linear rule. Any above-chance hierarchical behavior on L2 must then come from L1.
Key Contributions
- A cross-lingual poverty-of-stimulus (CPOS) design. The authors extend the monolingual POS paradigm to a two-stage L1→L2 continued-pretraining setup where the amount of disambiguating evidence is manipulated only on the L1 side, isolating transfer from confounds such as data scale or position-embedding initialization.
- A controlled corpus-construction pipeline. Using Stanza parses of Wikipedia, sentences are classified as "positive-evidence" (containing attractors and embedding depth ≥ 1) or "non-evidential" (no attractors, depth 0), producing matched-size Ambiguous and Disambiguating corpora in English, German, Russian and Japanese.
- An empirical demonstration of partial transfer. Models exposed to Disambiguating L1 data show above-chance hierarchical accuracy on English L2 with the Transformer layers frozen, with the effect size varying by L1 language.
- A vocabulary-overlap ablation with statistical modeling. Following Kallini et al. (2025), the shared token inventory between L1 and L2 is manipulated (Full Overlap, 1k Overlap, No Overlap) and analyzed with a Bayesian Bernoulli-logit mixed-effects model over 72 independently trained runs.
Main Findings
-
Transfer happens, but weakly. Under full vocabulary overlap on CLAMS, the Hier→Lin minus Lin→Lin difference (Δacc) is positive for every L1: English +5.45 (56.04 → 61.49), German +1.68 (52.83 → 54.52), Russian +1.04 (51.07 → 52.11), Japanese +0.53 (51.24 → 51.77). The authors describe this as a small but detectable hierarchical bias.
-
The baseline sits at chance. Under Lin→Lin, accuracy on CLAMS ranges from 51.07 to 56.04 across the four L1s, confirming the model does not acquire the hierarchical rule from ambiguous data alone (chance = 0.50).
-
A language gradient appears on the synthetic benchmark. Δacc on CLAMS decreases monotonically from English (+5.45) > German (+1.68) > Russian (+1.04) > Japanese (+0.53), broadly tracking typological distance from English and the frequency of attractor-licensing agreement constructions in the L1.
-
The naturalistic benchmark only partly agrees. On MultiBLiMP, English as L1 shows a larger positive effect (+8.53; 61.39 → 69.92), while German is negative (−2.54; 60.45 → 57.91), Russian is +0.56 and Japanese +1.98. The authors treat CLAMS as the primary benchmark and MultiBLiMP as a directional check because it has far fewer items.
-
Removing vocabulary overlap nearly erases transfer. Under No Overlap on CLAMS, Δacc falls to +0.79 (En→En), +0.77 (De→En), +0.14 (Ru→En) and −0.26 (Ja→En). On MultiBLiMP, En→En drops to +2.53, with De→En at −1.13, Ru→En at −2.82 and Ja→En at +0.00.
-
A tiny lexical bridge can be enough. Under 1k Overlap (1,000 shared tokens retained), En→En reaches +5.76 on CLAMS and +11.25 on MultiBLiMP; the paper reports that the En→En case behaves like No Overlap early in L2 training but recovers to Full-Overlap levels by late stages, most clearly with training extended to 16 epochs.
-
The statistics support the overlap dependence. The mixed-effects model gives an overall transfer contrast of Δhier = 0.121 [0.092, 0.150] on CLAMS; the contrast comparing overlap-present conditions against No Overlap is 0.144 [0.083, 0.205], while the No Overlap contrast alone is 0.025 [−0.025, 0.074] and is not credible. Credible intervals exclude zero for English and German under overlap; every No Overlap interval includes zero.
-
Transfer is not tied to a particular epoch. The gains emerge and then stabilize after several epochs of L2 training rather than at one specific point.
Methodology in Plain English
The authors run a two-stage training recipe. First, a GPT-2-small model is trained from scratch for 8 epochs on an L1 corpus. The Transformer layers are then frozen, and training continues for another 8 epochs on an L2 (always English) corpus. Each stage uses a 50M-token training set and a 5M-token validation set, giving 50M × 8 = 400M tokens seen per stage. A single byte-level BPE tokenizer with a 64,000-token vocabulary is trained on the concatenation of the L1 and L2 corpora.
The corpus manipulation is the heart of the design. L1 corpora for English, German, Russian and Japanese are drawn from Wikipedia and parsed with Stanza. Sentences are split into Ambiguous data (no intervening nouns between subject and verb, no clausal embedding) and Disambiguating data (attractors present, embedding depth ≥ 1). In the Hier→Lin condition, L1 training uses Disambiguating data and L2 training uses Ambiguous data; in the Lin→Lin baseline, both use Ambiguous data. Because the L2 data are identical across conditions, any difference in L2 agreement behavior must come from L1.
Evaluation uses minimal-pair accuracy: a model scores an item correct if it assigns lower perplexity to the grammatical sentence than to its minimally different ungrammatical counterpart. Agreement with the syntactic subject indicates hierarchical generalization; agreement with the linearly nearest noun indicates linear generalization. Tracking the difference between the Hier→Lin and Lin→Lin conditions (Δacc) isolates the contribution of L1 evidence.
Finally, the tokenizer's shared inventory is controlled: Full Overlap keeps the native intersection of L1 and L2 tokens; 1k Overlap retains only 1,000 shared tokens; No Overlap offsets all of them so that, even for English-as-L1 and English-as-L2, the same word carries different token IDs. All results are averaged over three random seeds, and item-level correctness is modeled with a Bayesian mixed-effects regression including random intercepts for run and item.
Why This Matters
Impact on research. The paper separates genuine transfer of abstract syntactic structure from confounds that are hard to rule out in ordinary multilingual pretraining. It also connects the monolingual poverty-of-stimulus literature to the L2-LM paradigm: the inductive bias for hierarchy is not tied to one language, but it is conditionally deployed — a nuance that reframes strong claims about language-universal structure in LMs.
Real-world applications:
- Multilingual tokenizer design: if shared token IDs act as the anchor for reusing syntactic abstractions, vocabulary construction becomes a decision about capability transfer, not just compression.
- Low-resource language extension: predicting when continued pretraining in a new language will or will not carry over structural knowledge from the source language.
- Evaluation of multilingual models: minimal-pair agreement tests as a cheap probe for whether a model has actually acquired a rule rather than memorized surface statistics.
- Psycholinguistic modeling: a controlled baseline for comparing LM L2 trajectories against human second-language acquisition.
Industry relevance. Continued pretraining on a new language is a standard, expensive step in deploying models across markets. Knowing that transfer is gated by lexical overlap gives practitioners a concrete, cheap lever — controlling the shared subword inventory — for deciding whether structural competence will survive adaptation.
Future Directions
- Scale and architecture. All experiments use GPT-2-small; the authors explicitly leave larger models and alternative architectures untested, and note their position that a phenomenon should be established at small scale before its scaling behavior is examined.
- Varying L2 and widening typology. L2 is fixed to English and the four L1s are English, German, Russian and Japanese; the authors state that replicating the language gradient with L2 varied is needed to disentangle L1/L2 status from pair-specific lexical and structural proximity, especially outside Indo-European.
- Unfreezing the Transformer. Freezing isolates transfer of L1-acquired generalization from embedding-layer adaptation, but it means the findings do not directly extrapolate to standard multilingual pretraining or joint training where all layers update.
- Reconciling synthetic and naturalistic results. The language gradient holds on CLAMS but not on MultiBLiMP, where only English shows a credible effect and the German point estimate reverses sign; the authors list three compatible explanations (synthetic-data artifacts, lexical frequency and collocation confounds in natural data, or low statistical power) and state their data do not adjudicate among them. Larger naturalistic benchmarks and more seeds are proposed as the way forward. Other hierarchical phenomena such as filler–gap dependencies and island constraints are explicitly out of scope.
Target Audience
Researchers in computational linguistics and NLP working on cross-lingual transfer, multilingual pretraining, and tokenizer design; scientists studying the linguistic competence and inductive biases of language models; and psycholinguists using LMs as models of second-language acquisition. It is also useful for engineers deciding how to allocate subword vocabulary across languages in a multilingual deployment. Readers unfamiliar with agreement-attractor minimal pairs will need the background sections, so it is not an entry-level paper.
Authors’ abstract
Language models (LMs) often exhibit successful cross-lingual transfer through continued (pre)training, still their underlying process remains unclear. One possibility is that LMs can leverage the evidence toward language-universal principles, namely, hierarchical structure, from a source language (L1) to a new language (L2), while many other non-linguistic explanations, e.g., improved initialization of position embeddings, can be potentially possible. In this study, to quantify the cross-linguistic transferability of linguistic evidence in cross-lingual LM training, we introduce a new experimental design, namely, a cross-lingual poverty-of-stimulus (CPOS) setting that ablates how LMs' hierarchical generalization in L2 can be led by structural evidence provided in L1. We contrast counterfactual L1 and L2 learning scenarios where the L2 corpus is ambiguous between linear and hierarchical grammar rules, while the amount of positive evidence for the hierarchical rule is controlled on the L1 side. Our experimental results show that LMs can partially, yet not perfectly, transfer L1 structural evidence to L2, yielding only a small but detectable hierarchical bias, while the strength of transfer depends on language pairs. We further ablate the conditions for successful transfer, motivated by recent reports on the substantial impact of vocabulary overlap. We indeed find that vocabulary overlap is crucial even for the cross-lingual transfer of hierarchical syntactic generalization. This suggests that this also explains the language-pair-dependent tendencies in the main experiments and suggests that the transfer of linguistic evidence in continued new-language learning is only conditionally achievable.