Research
OmniCam: Omni-Camera Trajectory Generation via Geometry-Grounded Pose Token Learning
Overview Research area: Computer Vision — camera trajectory generation for controllable video generation, 3D scene reconstruction, and robotic perception, combining panoramic (360°) geometry with lang
- arXiv
- 2610.09513
- Published
- 2026-10-07
- Authors
- Zhenyang Liu, Chenjie Cao, Yisu Zhang, Xuhui Zuo, Xiangyang Xue, Yanwei Fu, Tengfei Wang, Chunchao Guo
AI summary
Overview
Research area: Computer Vision — camera trajectory generation for controllable video generation, 3D scene reconstruction, and robotic perception, combining panoramic (360°) geometry with language conditioning.
Technical level: Advanced. The paper assumes familiarity with autoregressive transformers, SE(3) pose representations, quaternions, point-cloud/voxel encoders, and standard trajectory error metrics (ATE, FDE, RPE).
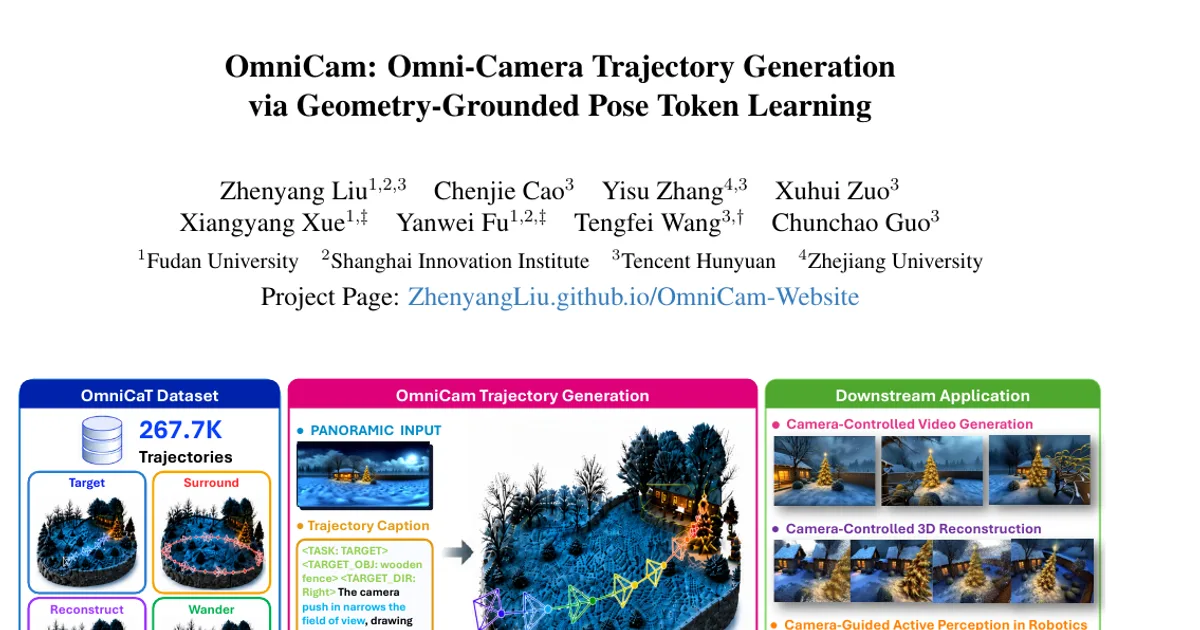
Scope: OmniCam is an autoregressive model that turns a single panorama plus a text description into a full camera pose sequence, trained on a new 267,700-trajectory synthetic dataset (OmniCaT) built on reconstructed panoramic geometry.
What This Paper Is About
Deciding where a camera should move, how it should rotate, and what object it should keep in view is the control problem behind camera-controllable video generation, scene reconstruction, and robot perception. Existing trajectory generators either see only a narrow field of view (perspective RGB-D) or require hand-built spatial representations and planning. OmniCam instead predicts camera trajectories directly from one panoramic image and a natural-language instruction, using 360° point-cloud geometry and an explicit 3D anchor for the object being filmed.
Key Contributions
- Panorama-conditioned trajectory generation. OmniCam combines explicit point-cloud features, separate geometric and semantic conditioning pathways, and an attention-derived 3D target centroid to generate SE(3) camera trajectories from panoramic imagery and language.
- Hybrid pose serialization. The model encodes rotations as absolute unit quaternions with sequential sign alignment (to resolve quaternion double-cover ambiguity) and translations as relative increments in a scene-normalized coordinate frame, packaged as 9 tokens per frame (4 rotation, 3 translation, 2 intrinsics). The paper provides error/representation analyses and empirical comparisons of absolute, relative, and hybrid schemes.
- The OmniCaT dataset. 267,700 trajectories across 9,998 scenes (21.7M rendered frames), spanning four camera behaviors — Surrounding (97,702), Target (90,065), Reconstruction (43,316), and Wandering (36,617) — each paired with hierarchical text annotations (task, target, motion).
- Empirical and downstream validation. Comparisons against retrained and pre-trained baselines on OmniCaT and DataDoP, component ablations, plus downstream studies in camera-controlled video generation (with WorldStereo) and robotic active perception, including a qualitative real-robot demonstration.
Main Findings
- Main benchmark gains on OmniCaT: OmniCam reaches ATE 0.868, FDE 1.462, RPE-R 1.135, RPE-T 0.027, collision 10.4%, visibility 52.0%, and angular deviation 10.9°, versus retrained GenDoP at 1.624 / 2.483 / 1.577 / 0.038 / 30.4% / 33.6% / 27.6°. The paper states this as 46.6%, 41.1%, 28.0%, and 28.9% reductions on the four error metrics, a 65.8% relative collision reduction, and a 54.8% relative visibility increase.
- Comparison to the strongest baseline per metric: Against Director3D (the best baseline for ATE and collision), the reported reductions are 43.0% for ATE and 62.3% for collision.
- Zero-shot cross-dataset transfer to DataDoP: With no DataDoP fine-tuning, OmniCam reports ATE 0.925, collision 8.9%, visibility 64.2%, and angle 12.7°, compared with GenDoP trained on DataDoP at 1.437, 28.5%, 36.6%, and 29.8°.
- Gap to a privileged planner: A heuristic planner with access to reconstructed geometry, navigation meshes, and semantic annotations achieves 5.2% collision and 58.7% visibility, versus OmniCam's 10.4% and 52.0%. The paper explicitly calls this a reference point, not a performance bound, and reports runtimes of 0.84s (OmniCam) versus roughly 16.5s (planner).
- Both conditioning branches matter: Removing the semantic branch drops visibility from 52.0% to 11.5%; removing the geometric branch raises collision from 10.4% to 45.8%.
- Explicit 3D geometry beats image-only input: Collision is 38.7% with panorama RGB only, 22.6% with panorama RGB-D, and 10.4% with the point-cloud pathway.
- Target anchoring drives visibility: Removing target cross-attention changes visibility from 52.0% to 25.8% and angle from 10.9° to 35.6°; removing only the localization loss gives 32.4% and 28.7°; removing both gives 21.3% and 40.2°.
- Hybrid tokenization wins: RPE-R/RPE-T is 1.135/0.027 for the full hybrid versus 1.625/0.058 for all-absolute and 1.984/0.062 for all-relative; dropping quaternion sign alignment raises RPE-R to 1.847.
- All four behaviors improve: ATE versus retrained GenDoP is 1.150 vs. 2.421 (Wander), 0.677 vs. 1.088 (Target), 1.258 vs. 1.932 (Surround), and 0.385 vs. 1.055 (Reconstruct) — described as 37.8% and 63.5% reductions for Target and Reconstruct.
- Scaling trends within the tested range: ATE falls from 1.483 to 0.868 and collision from 19.8% to 10.4% as nominal data scale goes from 27K to 267K; ATE falls from 1.127 (Small, ~120M) to 0.743 (Large, ~1B) and collision from 13.8% to 8.7% with model size.
- Downstream video generation: With WorldStereo, OmniCam trajectories improve the reported CLIP score by 14.1% and consecutive-frame SSIM by 15.4% relative to GenDoP.
- Cost: OmniCam Base (~500M parameters) trains for roughly 24h on 8× H20 GPUs at 0.84s inference per trajectory, versus GenDoP at roughly 18h, 0.42s, and ~380M parameters.
Methodology in Plain English
- Build a scene representation from one panorama. A monocular depth estimator turns the 360° image into a depth map, which is unprojected into a filtered 3D point cloud, voxelized at 0.02 m, and encoded with sparse convolutions plus a transformer. This branch never sees the text.
- Keep a second, language-aware pathway. A frozen SAM 3 vision encoder (1024-dimensional features) and a pretrained text encoder process the panorama and caption separately, so target-related appearance information is available. Text and the target descriptor guide a "Language-Guided Semantic Resampler" that repeatedly attends over the semantic queries themselves, the 3D point coordinates, and the text features.
- Compress everything into a short prefix. Two resamplers turn the dense visual/semantic and geometric features into compact latent token sequences, which are concatenated with the text features as the decoder's condition.
- Point at the target in 3D. Attention logits over individual points are converted by a temperature-scaled soft-argmax into a 3D centroid, positionally encoded into a small "target memory" that the decoder reads through gated cross-attention. An auxiliary loss supervises this centroid against the annotated 3D target.
- Serialize poses into tokens. Positions are normalized by a per-scene centroid and scale. Rotations are absolute quaternions, each sign-aligned to the previous aligned frame so equivalent rotations get one label; translations are per-step increments with a small normalized displacement limit. Everything is uniformly binned into 256 levels, giving 9 tokens per frame, plus boundary tokens.
- Decode autoregressively with a format constraint. An OPT-style decoder (hidden 1024, 8 heads, 12 layers) predicts tokens; at inference the end-of-sequence token is masked inside each 9-token group so trajectories can only terminate on frame boundaries. Sampling uses top-k with k=10.
- Train with weighted objectives. Cross-entropy is weighted by channel (rotation 2.0, translation 1.5, intrinsics 0.5), by temporal decay (2.0 on the first frame down to 1.0), and by a curriculum mask that starts on early frames. Structured caption dropout varies how much of the instruction is shown.
- Create supervision synthetically. Because real panorama–trajectory–text triples are scarce, the authors reconstruct geometry from panoramas, build navigation meshes with Recast, and plan four families of feasible trajectories on those meshes with spline and SLERP smoothing, then render frames and generate hierarchical text with a vision-language model.
Why This Matters
Impact on research. The paper reframes camera control as a pose-token sequence-prediction problem grounded in explicit 3D geometry, and it isolates a detail most pose-learning work glosses over: quaternion sign ambiguity when discretizing rotations. Its representation analysis (absolute rotations keep a per-frame quantization bound; integrating relative rotations can accumulate up to min{π, (T−1)ε} error) and the accompanying ablations give concrete evidence for a hybrid scheme, and the 267,700-trajectory OmniCaT dataset fills a gap the authors identify — no existing resource combines omnidirectional geometry, diverse spatial behaviors, and hierarchical text.
Real-world applications:
- Camera-controlled video generation: supplying precise, scene-aware camera paths to world models and video generators instead of hand-authored orbits.
- 3D/4D scene reconstruction: automatically planning multi-view capture paths that cover a target object or space (the Reconstruction behavior, where OmniCam's ATE gap to GenDoP is largest: 0.385 vs. 1.055).
- Robotic active perception: repositioning a robot's camera to resolve occlusion of a target, demonstrated qualitatively on a real robot.
- Virtual production and aerial/cinematic capture: turning short directorial instructions into physically feasible camera moves around a referenced subject.
Industry relevance. Better trajectory priors directly affect content-creation pipelines, simulation/world-model training data generation, and embodied AI stacks; the reported cost profile (0.84s per trajectory, ~500M parameters) and the availability of a ~1B variant make the approach practical for integration into generation pipelines.
Future Directions
- Dynamic scenes and closed-loop planning. The conclusion names dynamic scenes and closed-loop planning as future work; the current system assumes static panoramic observations.
- Reducing dependence on estimated geometry and planner-derived supervision. Depth errors, thin structures, and outliers propagate into both the training labels and the model's inputs; the authors state that evaluation on independently measured geometry and independently specified tasks is needed.
- Isolating what causes each gain. The paper repeatedly flags that removing a branch also changes capacity and available information, calling for capacity-matched single-branch comparisons, and that per-behavior gate strengths cannot be inferred from aggregate results.
- Tighter evaluation protocols. The authors ask for verified split manifests, matched timing conditions, data-overlap checks for the DataDoP transfer claims, and verification of the robot success-rate aggregation, since generated-supervision errors mean low ATE measures agreement with planner output rather than ground-truth correctness.
Target Audience
Researchers and engineers working on controllable generative video, world models, 3D vision, and embodied/robotic perception — particularly those interested in pose representation for sequence models, panoramic or point-cloud conditioning, or synthetic data generation for spatial tasks. Readers need comfort with autoregressive transformers and SE(3) parameterizations; newcomers can still extract the dataset design and the high-level argument that geometry and explicit target anchoring should be handled by separate pathways.
Authors’ abstract
Camera trajectories control viewpoint changes in video generation, scene reconstruction, and robotic perception. Generating them from language requires both scene geometry and target-aware framing. We introduce OmniCam, an autoregressive model that generates camera pose sequences from a single panorama and textual trajectory descriptions. Its geometry-grounded pose token learning combines three components: a panoramic point-cloud encoder for omnidirectional geometric context; hybrid absolute-rotation and relative-translation tokenization with temporally consistent quaternion signs; and separate geometric and semantic conditioning streams with an explicit 3D target anchor. We also construct OmniCaT, containing 267,700 trajectories across four camera behaviors. On the reported OmniCaT evaluation, OmniCam reduces trajectory errors by 28--47% and collision rate by 65.8% relative to GenDoP retrained on OmniCaT. Against the best baseline for each metric, the ATE and collision reductions are 43.0% and 62.3%, respectively. Component ablations support the use of geometric and target-aware conditioning, while downstream experiments examine camera-controlled video generation and robotic active perception.