Research
MULTI3IR: A Benchmark for Multi-perspective Multi-domain Multi-modal Information Retrieval
Overview Research area: Information retrieval (cs.IR), specifically open-ended retrieval benchmarking and retrieval diversification with multimodal dense retrievers. Technical level: Intermediate. The
- arXiv
- 2608.30949
- Published
- 2026-08-31
- Authors
- Seokwon Song, Sohyeon Kim, Gunhee Kim
AI summary
Overview
- Research area: Information retrieval (cs.IR), specifically open-ended retrieval benchmarking and retrieval diversification with multimodal dense retrievers.
- Technical level: Intermediate. The benchmark construction and evaluation are easy to follow; the proposed method (SPIN) involves transformer layer analysis, noise-vector steering and a noisy-OR coverage loss.
- Scope: The paper introduces Multi3IR, a 104.9K-query open-ended retrieval benchmark spanning multiple domains and modalities, and SPIN, a parameter- and label-efficient training method that steers a frozen retriever into multiple perspective-aware embeddings.
What This Paper Is About
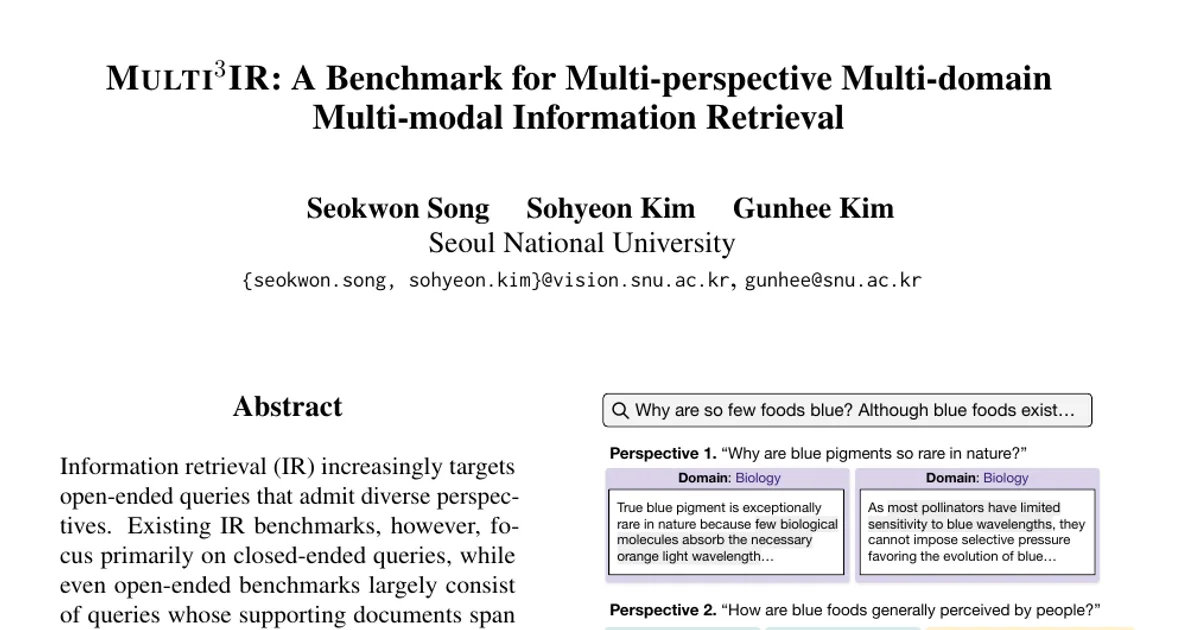
Open-ended questions implicitly contain several distinct facets, called perspectives, and a good retriever should surface documents covering all of them. Existing benchmarks mostly use closed-ended queries, and even open-ended ones draw supporting documents from a single subject domain and a single modality (usually text). The authors build a benchmark that measures how well retrievers cover the multifaceted perspectives of open-ended queries across many domains and both text and image modalities, and propose a training method that reduces the tendency of current retrievers to collapse onto one dominant perspective.
Key Contributions
- Multi3IR benchmark: A large-scale open-ended IR benchmark of 104.9K queries collected from Stack Exchange, annotated with perspective descriptions and the documents supporting each perspective, spanning 3.34 subject domains and 1.91 modalities per query on average.
- Identification of single-perspective bias: The paper documents that current multimodal retrievers concentrate retrieval on a few dominant perspectives of a query while neglecting the rest, and traces the bottleneck to the query embedding rather than the document space.
- SPIN (Steering Perspectives by Injecting Noise): A parameter- and label-efficient training method that learns noise vectors injected at an intermediate layer of a frozen retriever to produce multiple perspective-aware query embeddings, using only perspective descriptions and no document-level relevance annotations.
- Empirical validation and analysis: Experiments on three state-of-the-art multimodal retrievers showing higher perspective coverage than existing diversification methods, generalization to the unseen PIR and BeRDS benchmarks, and analyses of injection layer, adaptation-method comparison, knowledge source coverage and document dispersion.
Main Findings
- Retrievers exhibit single-perspective bias. Zero-shot naive retrievers on Multi3IR reach only up to 28.83 HC@10 and 39.52 SC@10, far below the oracle setting where perspective descriptions are given explicitly. Providing perspectives boosts performance by 15.58 to 35.31 points on HC@10 and 31.28 to 36.72 points on SC@10.
- The bottleneck is query understanding, not retrieval depth. The gap persists at k = 100, with a difference of 19.45 to 35.60 points on HC@100, indicating the failure is not one of retrieval depth.
- Multiple query vectors alone do not help. LLM-Expansion uses m = 5 embeddings but falls below the naive baseline on HC@10, whereas SPIN outperforms it by 8.18 to 13.13 points on HC@10 and 17.99 to 21.92 points on SC@10 using the same annotations and the same number of query embeddings.
- Perspective-level supervision beats document-level supervision. SPIN outperforms ARE by 3.62 to 4.47 points on HC@10 and by 14.47 to 14.62 points on SC@10, while perspective-level supervision is also cheaper to obtain since document relevance annotation dominates the overall synthesis cost.
- Intermediate-layer injection is essential. Injecting noise at the mid layer (L = 18 for Qwen3-VL, 36 layers total) yields consistent improvement as m grows (63.4 at m = 5, 64.2 at m = 9), while late-layer injection (L = 30) plateaus as m increases (60.5 to 61.0 range across larger m).
- SPIN is far more parameter-efficient than other adaptation methods. At the intermediate layer, SPIN achieves HC@100 of 63.4 with 20.5K parameters, outperforming LoRA (r = 16, 104.9M parameters, 55.9) and adapter (r = 64, 41.9M parameters, 55.9) by 7.5 points with over three orders of magnitude fewer parameters.
- Modality coverage nearly saturates the oracle; domain coverage does not. SPIN reaches 78.2 versus an oracle 81.1 on modality coverage at k = 100 (closing 91% of the naive-to-oracle gap), but only 68.3 versus 84.8 on domain coverage, closing 35–47% of the gap.
- SPIN helps most on dispersed positives. On the top quartile of document dispersion, SPIN at m = 5 improves HC@100 by 24.4 points over naive, while also gaining 8.7 points on tightly clustered queries.
- Generalization to unseen benchmarks. On PIR, SPIN improves over the naive retriever by 9.37 to 11.73 points on HC@10 and 3.81 to 6.09 points at k = 100. On BeRDS, gains are smaller for MM-Embed and Qwen3-VL but reach 20.10 points on HC@10 for GME-Qwen2; the only exception is MM-Embed at HC@100 on BeRDS, where both methods exceed 98%.
- Human verification supports annotation quality. Nearly all perspectives are judged relevant (99.1%) and unique (96.2%), with 90.2% of documents exclusively supporting their target perspective.
Methodology in Plain English
The authors start from Stack Exchange, which naturally contains questions with many answers reflecting different viewpoints. They gather posts from 77 sites across five categories (technology, culture & recreation, science, business, life & arts), keeping questions with more than three answers and more than three distinct voters. From the raw pool they obtain 29,785,033 questions, which reduce to 4,010,742 after quality filtering and 353,901 after category-level uniform sampling.
From each question's answers, GPT-5-mini extracts candidate perspectives. Two filters verify them: near-duplicate perspectives are removed using all-MiniLM-L6-v2 with a cosine similarity threshold of 0.8, and perspectives not entailed by the answers are removed using Bespoke-MiniCheck-7B. Questions with fewer than four perspectives are dropped, leaving 104.9K questions and 521.7K perspectives.
Each perspective is then used as a search query to retrieve the top-10 documents from Google Image Search (images) and the Colossal Clean Crawled Corpus (text). Because retrieved documents may support several perspectives at once, Qwen3-VL-30B-A3B-Instruct enforces exclusive support, keeping only documents that support their target perspective alone. EAI-Distill-0.5b assigns a subject domain label from a two-level taxonomy of 10 top-level classes and 100 sub-classes. The result is 1,012,061 multimodal documents. Human annotators then check relevance, closeness to other perspectives, redundancy, and how fully each document supports its perspective, producing a test split of 1.0K queries, 4.8K perspectives and 12.5K supporting documents.
For the method, the authors first show that when perspective descriptions themselves are used as queries and results are merged by Round Robin, previously missed documents become retrievable. This points to the query embedding as the problem. SPIN therefore freezes the retriever, injects small learnable noise vectors into the query's hidden representation at an intermediate layer, and forwards the result through the remaining layers. The perspectives are encoded with the same frozen model as target embeddings, and the noise vectors are trained so that each target is covered by at least one steered embedding (a noisy-OR positive loss), while all steered embeddings must reject documents belonging to other queries in the batch (negative loss). At inference, each noise vector produces one query embedding, each embedding retrieves its own ranked list, and the lists are merged by Round Robin.
Evaluation uses HardCoverage@k, which checks whether an annotated supporting document appears in the top-k results, at k ∈ {5, 10, 20, 100}, and SoftCoverage@k, which uses GPT-5-mini to judge whether retrieved documents support a perspective, at k ∈ {5, 10, 15, 20}. Experiments use 72K training instances, 32K validation instances, frozen document embeddings, and three backbones: MM-Embed-8B, GME-Qwen2-VL-7B-Instruct, and Qwen3-VL-Embedding-8B. Baselines are naive retrieval (zero-shot and document-fine-tuned), LLM-Expansion with Qwen3-4B, Auto-Regressive Embedding (ARE), and an oracle that retrieves with the ground-truth perspective descriptions.
Why This Matters
- Impact on research: Multi3IR shifts evaluation of open-ended IR from single-domain, text-only retrieval to comprehensive retrieval across heterogeneous knowledge sources, and provides a training signal (perspective descriptions) that is far cheaper than document relevance annotations. The diagnosis of single-perspective bias gives the field a concrete failure mode to target.
- Real-world applications:
- Question-answering assistants that must assemble an answer from several fields (for example biology and psychology) rather than returning one dominant source.
- Multimodal search over mixed text and image collections, such as product or travel knowledge bases.
- Educational and research tools that need balanced coverage of multiple viewpoints on an open-ended topic.
- Enterprise knowledge search where a single query should surface documents from different internal domains (legal, engineering, management).
- Industry relevance: Because SPIN trains only 20.5K parameters on a frozen retriever with no query-time LLM call and no document-level labels, it offers a low-cost path to diversify an existing deployed retriever, in contrast to query expansion (an LLM call per query) and multi-vector training methods that need costly document annotations.
Future Directions
- Developing an adaptive mechanism that selects the number of perspective vectors m per query, since the number of perspectives varies substantially across queries while SPIN fixes m.
- Jointly leveraging perspective descriptions and their supporting documents during training to improve perspective-specific retrieval, rather than relying only on perspective descriptions.
- Learning domain-aware steering vectors, since SPIN closes only 35–47% of the naive-to-oracle gap on domain coverage while nearly saturating modality coverage.
- Reducing LLM-induced bias in the automated pipeline (perspective extraction, document retrieval, exclusive-support verification), which may affect the absolute scores reported.
Target Audience
Researchers and practitioners working on information retrieval, retrieval diversification, and multimodal search, especially those building or evaluating open-ended question answering and retrieval systems. It is also relevant to engineers who want to improve an existing dense retriever without large annotation budgets or extra inference-time LLM calls, and to benchmark designers interested in multi-domain, multi-modal dataset construction.
Authors’ abstract
Information retrieval (IR) increasingly targets open-ended queries that admit diverse perspectives. Existing IR benchmarks, however, focus primarily on closed-ended queries, while even open-ended benchmarks largely consist of queries whose supporting documents span a single subject domain and modality. We introduce Multi$^3$IR, a benchmark that evaluates how well retrievers cover the multifaceted perspectives of open-ended queries across diverse domains and modalities. It comprises 104.9K Stack Exchange queries, each annotated with perspective descriptions that capture the query's implicit viewpoints. We further propose SPIN, a parameter- and label-efficient method that learns noise vectors to steer embeddings toward diverse yet meaningful semantic directions. Experiments show that existing multimodal retrievers suffer from single-perspective bias, while SPIN substantially improves perspective coverage on Multi$^3$IR and generalizes well to unseen open-ended IR benchmarks. The dataset and experimental code are available at https://github.com/seokwon99/Multi3IR.