Research
MMSD3.0: A Multi-Image Benchmark for Real-World Multimodal Sarcasm Detection
Overview Research area: Multimodal sarcasm detection in social media content (vision–language), with a new dataset and a new detection model. Technical level: Advanced — the paper assumes familiarity
- arXiv
- 2510.23299
- Published
- 2025-10-27
- Authors
- Haochen Zhao, Yuyao Kong, Yongxiu Xu, Gaopeng Gou, Hongbo Xu, Yubin Wang, Haoliang Zhang
AI summary
Overview
- Research area: Multimodal sarcasm detection in social media content (vision–language), with a new dataset and a new detection model.
- Technical level: Advanced — the paper assumes familiarity with vision transformers, cross-attention, state-space sequence models, and instruction-tuned multimodal LLMs.
- Scope: The paper introduces MMSD3.0, a benchmark of over 10,000 multi-image samples built from Twitter and Amazon reviews, and proposes CIRM, a Cross-Image Reasoning Model that is evaluated on MMSD, MMSD2.0, and MMSD3.0.
What This Paper Is About
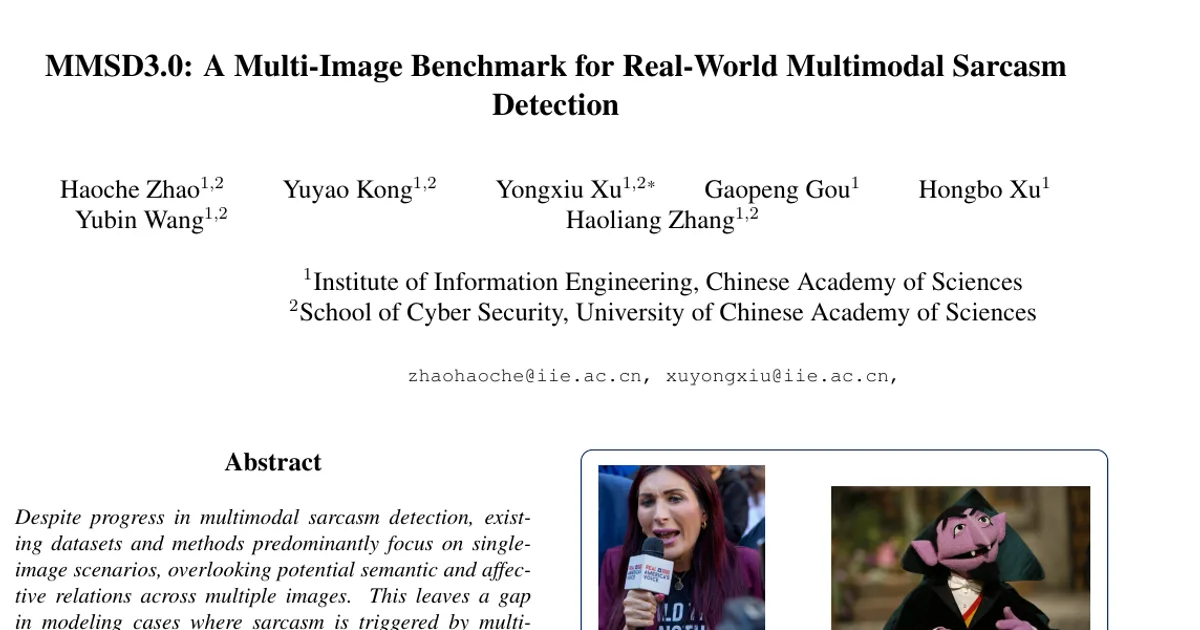
Existing multimodal sarcasm datasets and models assume a post contains only one image, so they cannot handle real posts where sarcasm emerges from the relationship or contrast between several images (the paper's example: a left image of Laura Loomer next to a right image of Count von Count, where the joke only works if both images are seen). The authors build MMSD3.0, a benchmark composed entirely of multi-image samples from tweets and Amazon reviews, and propose CIRM, a model designed to reason across images and align them with text. The goal is to move multimodal sarcasm detection closer to real-world conditions and to show how poorly single-image methods transfer to them.
Key Contributions
- Identification of the "multi-image sarcasm gap." The authors state they are the first to identify that multimodal sarcasm detection has been confined to single-image settings, and they propose MMSD3.0 to push the task toward real-world applicability.
- The MMSD3.0 dataset. Over 10,000 instances, each with two to four images (four being the maximum allowed on Twitter), sourced from tweets without specific hashtags and from Amazon reviews, and annotated in two rounds by nine graduate-student annotators with a Cohen's Kappa of 0.816.
- The CIRM model. A multi-image sarcasm reasoning framework performing Dual-Stage Bridging (Pre-Bridge, sequential modeling, Post-Bridge) and Relevance-Guided Fusion to improve text–image alignment.
- Extensive experiments and ablations. CIRM is reported as state-of-the-art in both single-image and multi-image settings, while prior single-image methods transfer poorly to MMSD3.0.
Main Findings
- Dataset statistics. MMSD3.0 has 7,583 training samples (3,007 sarcastic, 4,576 non-sarcastic, 39.65% sarcastic, average text length 31.81 words and 2.57 images), 1,626 validation samples (655/971, 40.28%, 30.59 words / 2.59 images), and 1,624 test samples (634/990, 39.04%, 33.03 words / 2.61 images). By comparison, MMSD averages 15.65–15.82 words with 1.00 image and MMSD2.0 averages 13.42–13.64 words with 1.00 image.
- Rich auxiliary signals. Over 65% of images in MMSD3.0 contain OCR-detectable text, and around 23–25% of samples include emojis, which MMSD3.0 retains rather than replacing with placeholders.
- Single-image results. On MMSD2.0, CIRM reaches 92.12 Acc and 91.69 F1, exceeding the previous best by about 1.5 points. On MMSD it reaches 94.02 Acc / 93.76 F1, though the authors note the dataset's text bias may slightly inflate results.
- Multi-image results. On MMSD3.0, CIRM achieves 85.16 Acc / 84.42 F1, the best overall. With image order randomly permuted ("shuffled"), F1 drops only slightly to 83.51, indicating robustness to order perturbation.
- Weak single-image transfer. Multimodal baselines on MMSD3.0 cluster near text-only performance: Multi-view CLIP 81.96 F1, Tang et al. 80.91 F1, DIP 76.11 F1, MoBA 75.13 F1. Image-only ResNet (49.57 F1) and ViT (51.30 F1) are far behind, and text-only RoBERTa reaches 79.67 F1.
- General-purpose MLLMs underperform. GPT-4o scores 72.62 Acc / 71.39 F1, Qwen2.5-VL-32B 71.94 Acc / 71.52 F1, and LLaVA-1.5-7B 61.12 Acc / 59.84 F1 on MMSD3.0, despite natively accepting multi-image input.
- Ablations. Removing the full DSBM (81.41 F1) or the RGFM (81.36 F1) causes the largest declines from the full model's 84.42 F1. Omitting positional encoding (83.25 F1) or emoji cues (82.31 F1) costs less, while removing OCR causes a clear drop (81.59 F1). Removing the Pre-Bridge (81.81 F1), sequential modeling (81.23 F1), or Post-Bridge (81.99 F1) individually also degrades performance.
- Mixing weight matters. The relevance score blends cosine similarity and a learned scorer via a weight alpha; performance peaks at alpha = 0.3 with the highest F1 of 84.42%, and accuracy stays around 84% for most values in the sweep from 0 to 1.0.
- No-tiling protocol. When images are encoded separately and features concatenated instead of tiled into one canvas, CIRM still leads with 85.16 Acc / 84.42 F1, versus Tang et al. at 82.39 Acc / 81.54 F1 and Multi-view CLIP at 82.20 Acc / 77.79 F1.
- Real-world versus AI-generated split. Performance drops substantially on real-world data. CIRM reaches 83.31 Acc / 80.39 F1 on real-world samples versus 98.48 Acc on AI-generated samples. DIP scores 79.59/75.50 real-world versus 97.98 AI-generated; Multi-view CLIP 80.01/75.48 versus 95.96; MoBA 76.02/68.80 versus 88.89; Tang et al. 80.36/75.93 versus 95.45; GPT-4o 71.34/67.60 versus 82.61; LLaVA-1.5-7B 59.62/55.78 versus 72.83; Qwen2.5-VL-32B 68.90/66.65 versus 95.65.
- Length sensitivity. In a paired-truncation study on 500 MMSD3.0 long-text samples with L ≥ 30, CIRM's full-text accuracy of 86.40 [83.12, 89.13] drops to 73.40 [69.36, 77.08] after truncation, a difference of +13.00 accuracy points, +15.24 precision points, and +17.98 F1 points.
- Qualitative alignment. Attention visualizations show CIRM focusing on facial regions and expressions for emotionally descriptive captions, and on documents when the text references a "real estate portfolio."
Methodology in Plain English
The authors first build the dataset. Rather than reusing MMSD's hashtag-based sampling (which they describe as introducing spurious cues), they collect tweets without any specific hashtags plus Amazon customer reviews for out-of-domain coverage, keep emojis, and add AI-generated content: Qwen2.5-VL-32B generates three sarcastic candidates from images drawn from 1,444 real samples, GPT-4o scores them on six criteria such as Naturalness and Authenticity, and the top candidate is kept, yielding 1,444 sarcasm-labeled samples. Nine graduate students annotate in two rounds with two annotators per sample and a 70:15:15 train/validation/test split.
The model, CIRM, has five parts. Images are encoded with a Vision Transformer, padded up to a maximum of four images with blank placeholders. Text is encoded with RoBERTa-Emoji, and OCR text extracted by PP-OCRv5 is encoded separately rather than concatenated with the caption. Image order is injected through positional embeddings, and a padding mask ensures blank images are ignored.
The Dual-Stage Bridge Module performs cross-modal attention twice — once before sequence modeling (Pre-Bridge, with gated residual connections) and once after (Post-Bridge). In between, a state-space inspired sequential block normalizes and projects features into two streams, applies a depthwise Conv1D with SiLU activation for local dependencies, and uses a selective state update for long-range context before gating and fusing with a residual path.
The Relevance-Guided Fusion Module first aligns both text and visual features with OCR embeddings through attention, then summarizes the text by averaging and scores each image against that summary using both a cosine similarity term and a learnable MLP term, mixed by alpha. Those scores become softmax weights, multiplied by the valid-image mask, and are used to aggregate an emphasis-weighted multimodal feature. Finally, pooled text and vision representations, the relevance-guided vector, and an optional star-rating embedding are concatenated, passed through an MLP, and classified with a linear layer trained under weighted cross-entropy to mitigate label imbalance. Training uses AdamW, a learning rate of 2e-5, weight decay of 1e-5, batch size 8, 20 epochs, on a single NVIDIA H100 GPU (80 GB).
Why This Matters
Impact on research. The paper argues that existing benchmarks have been measuring a simplified version of the task. By releasing a dataset where sarcasm depends on relations across two to four images, it creates a harder and more realistic target that current single-image architectures do not solve, and it documents that state-of-the-art multimodal methods lose roughly the same amount of accuracy as text-only methods when moving to this setting.
Real-world applications:
- Content moderation and platform trust-and-safety systems that must distinguish sincere praise from sarcastic criticism in image-heavy posts.
- Brand and reputation monitoring, where sarcasm in customer reviews and social posts is easily misread by sentiment tools as positive.
- Opinion mining and market research that depends on correctly reading customer attitude from review text plus product images.
- Assistive or accessibility tooling that surfaces sarcastic intent in social feeds, where the meaning is carried by combinations of images rather than the caption alone.
Industry relevance. The paper's most directly commercial finding is the real-world versus AI-generated gap: models score far higher on AI-generated samples (CIRM reaches 98.48 Acc) than on real-world ones (80.39 F1). Companies deploying sarcasm or sentiment classifiers on genuine user content should expect substantially lower accuracy than benchmark numbers suggest. The dataset and code are publicly released at https://github.com/ZHCMOONWIND/MMSD3.0.
Future Directions
- Closing the real-world gap. The reported drop from AI-generated to real-world data points to distribution shift and greater complexity in authentic posts; the paper does not propose a specific remedy.
- Improving MLLM performance on multi-image sarcasm. GPT-4o, LLaVA-1.5-7B, and Qwen2.5-VL-32B all score well below CIRM on MMSD3.0 despite native multi-image input, leaving open how to adapt or prompt general vision-language models for this task.
- Handling longer texts. The paired-truncation study shows CIRM loses 13.00 accuracy points when long texts are cut, while MMSD3.0's average length is roughly double that of earlier datasets; better long-context modeling is an open problem.
- Beyond the four-image limit and beyond order permutations. The design caps images at four (Twitter's maximum) and shuffling order costs only about one F1 point, so the degree to which explicit image-order reasoning is being exploited, and how the approach scales to more images or interleaved content, remains open.
Target Audience
Researchers and graduate students in multimodal NLP, affective computing, and vision-language modeling who work on sarcasm, irony, or stance detection; benchmark and dataset builders interested in annotation protocols for subjective labels; and applied machine-learning engineers building sentiment, moderation, or opinion-mining systems on social media and review data. Readers need background in transformer architectures and multimodal fusion to follow the methodology section, though the dataset statistics, main results, and real-world-versus-AI comparison are accessible without it.
Authors’ abstract
Despite progress in multimodal sarcasm detection, existing datasets and methods predominantly focus on single-image scenarios, overlooking potential semantic and affective relations across multiple images. This leaves a gap in modeling cases where sarcasm is triggered by multi-image cues in real-world settings. To bridge this gap, we introduce MMSD3.0, a new benchmark composed entirely of multi-image samples curated from tweets and Amazon reviews. We further propose the Cross-Image Reasoning Model (CIRM), which performs targeted cross-image sequence modeling to capture latent inter-image connections. In addition, we introduce a relevance-guided, fine-grained cross-modal fusion mechanism based on text-image correspondence to reduce information loss during integration. We establish a comprehensive suite of strong and representative baselines and conduct extensive experiments, showing that MMSD3.0 is an effective and reliable benchmark that better reflects real-world conditions. Moreover, CIRM demonstrates state-of-the-art performance across MMSD, MMSD2.0 and MMSD3.0, validating its effectiveness in both single-image and multi-image scenarios. Dataset and code are publicly available at https://github.com/ZHCMOONWIND/MMSD3.0.