Research
MatAnyone 2: Scaling Video Matting via a Learned Quality Evaluator
Overview Research area: Computer vision — video matting (estimating a per-pixel alpha matte that separates a foreground subject from its background across video frames), with a focus on dataset constr
- arXiv
- 2512.11782
- Published
- 2025-12-12
- Authors
- Peiqing Yang, Shangchen Zhou, Kai Hao, Qingyi Tao
AI summary
Overview
Research area: Computer vision — video matting (estimating a per-pixel alpha matte that separates a foreground subject from its background across video frames), with a focus on dataset construction and training supervision.
Technical level: Advanced. The paper assumes familiarity with matting metrics, memory-propagation video models, segmentation priors, and diffusion-based generation backbones.
Scope in one sentence: This paper introduces a learned Matting Quality Evaluator (MQE) that supervises video matting training online and curates a large-scale real-world video matting dataset (VMReal) offline, yielding the MatAnyone 2 model.
What This Paper Is About
Video matting is held back by the fact that real, high-quality video alpha-matte datasets barely exist — the largest prior collection, VM800 [42], contains only 826 sequences, roughly 1/60 the size of the video object segmentation data used by SAM 2. Researchers have tried to compensate by mixing in segmentation data, but segmentation only supervises non-boundary regions (alpha 0 or 1) reliably, so boundary supervision stays weak and mattes end up looking like segmentation masks rather than fine-detail alphas. This paper builds a model that can judge matte quality pixel-by-pixel without ground truth, then uses that judge both to guide training and to automatically annotate a 28K-clip real-world dataset.
Key Contributions
-
A learned Matting Quality Evaluator (MQE). Given a video frame, a predicted alpha matte, and a segmentation mask, MQE outputs a pixel-wise binary map marking regions as "reliable" (1) or "erroneous" (0), assessing both semantic accuracy and boundary detail without needing ground-truth mattes.
-
Two ways of scaling video matting with MQE. Online, its error-probability map acts as a penalty signal during training; offline, it acts as a quality arbiter in an automated dual-branch annotation pipeline.
-
VMReal, a large-scale real-world video matting dataset. About 28K clips and 2.4M annotated frames, described as roughly 35 times larger than the previous dataset [42]. A high-quality subset of 4.5K clips comes from video footage websites and YouTube at 1080p; the remainder is derived from the SA-V dataset [29], typically at 720p.
-
A reference-frame training strategy. Long-range reference frames are added to memory beyond the local training window, with a random dropout augmentation, so the model handles large appearance changes in long videos without extra memory cost.
Main Findings
- State-of-the-art across synthetic benchmarks. On VideoMatte (512×288), MatAnyone 2 achieves MAD 4.73, MSE 0.55, Grad 0.51, dtSSD 1.12, and Conn 0.20, beating MatAnyone [42] (5.15, 0.93, 0.67, 1.18, 0.26) and all other compared methods across all metrics.
- Best scores at high resolution. On VideoMatte (1920×1080), it records MAD 4.10, MSE 0.28, Grad 3.45, and dtSSD 1.15. On YoutubeMatte (512×288): MAD 2.30, MSE 0.78, Grad 0.78, dtSSD 1.45, Conn 0.32. On YoutubeMatte (1920×1080): MAD 1.61, MSE 0.50, Grad 7.14, dtSSD 1.53.
- Large relative gains over MatAnyone. The paper reports reductions of 27.1% in Grad and 22.4% in Conn compared with the leading mask-guided MatAnyone [42].
- Best performance on a real-world benchmark. On the CRGNN real-world dataset [35] — 19 videos with ground-truth alpha mattes manually annotated every 10 frames — MatAnyone 2 reaches MAD 4.24, MSE 2.00, Grad 11.74, and dtSSD 4.54, versus MatAnyone's 5.76, 3.04, 15.55, and 5.44.
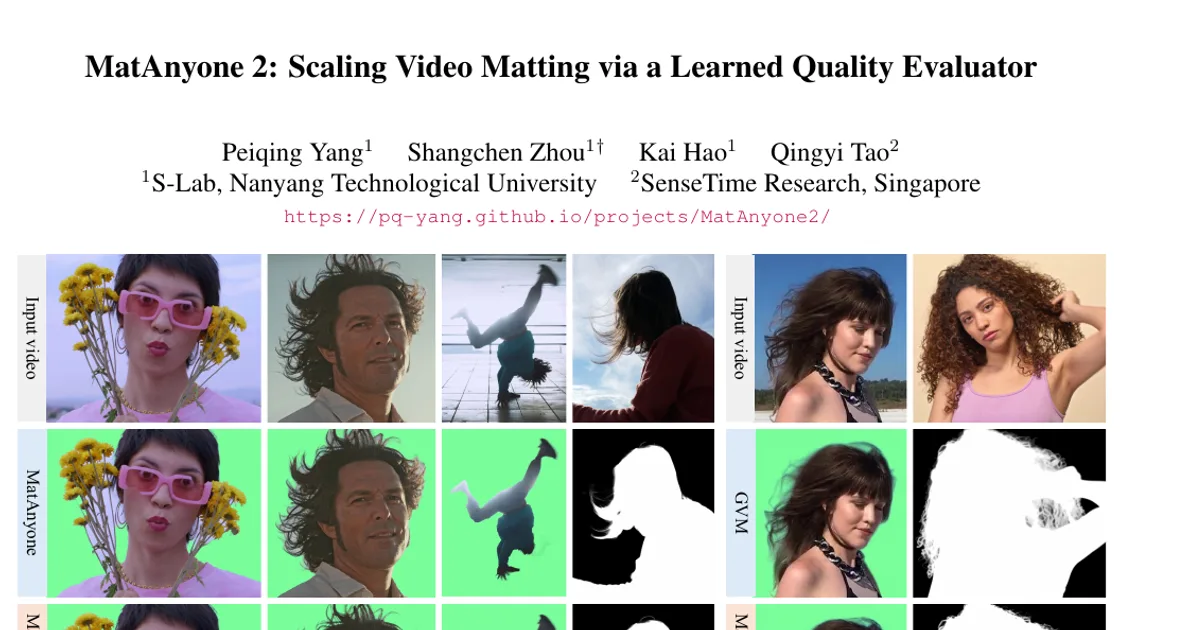
- A CNN beats diffusion and per-frame-mask rivals. The authors note GVM [5] benefits from Stable Video Diffusion priors and MaGGIe [9] requires an instance mask for every frame, while MatAnyone 2 is purely CNN-based and needs a mask only on the first frame — yet it still outperforms both.
- Online guidance helps most on semantics and detail. In the ablation on YouTubeMatte (1920×1080), adding the online guidance loss alone moves the baseline (MAD 1.99, MSE 0.71, Grad 8.91, dtSSD 1.65) to 1.90, 0.62, 8.20, 1.63.
- VMReal adds comprehensive gains. Training with VMReal on top of the online loss improves results to MAD 1.76, MSE 0.61, Grad 7.65, dtSSD 1.54, with the paper noting gains in semantic robustness, boundary fidelity, and temporal consistency. RVM [20] trained on VMReal also improved across all metrics (reported in the supplementary Table 6).
- Reference frames add further improvement. Adding the reference-frame strategy yields MAD 1.61, MSE 0.50, Grad 7.13, dtSSD 1.53, with the largest gains in semantic accuracy (MAD, MSE).
- MQE identifies realistic failure modes. Figure 4 shows it detecting (a) low-quality matting detail along boundaries and (b) semantically wrong regions in core areas, pixel by pixel, without ground-truth mattes.
Methodology in Plain English
The work rests on one new component and two ways of using it.
The component, MQE, is trained as a binary segmentation problem. Because no ground-truth "quality maps" exist, the authors synthesize them from the image matting dataset P3M-10k [12], which has human-annotated alpha mattes. Each image is split into a 7×7 grid of non-overlapping patches, and for each patch a discrepancy score is computed as 0.9·MAD + 0.1·Grad between the ground-truth alpha and a predicted one. Values are min–max normalized to [0, 1], and a pixel is labeled reliable if the discrepancy falls below a threshold δ = 0.2. Because reliable pixels vastly outnumber erroneous ones, training uses focal loss [21] (γ = 2, α = 0.25) plus dice loss [43]. MQE uses a pretrained DINOv3 [32] encoder with a DPT [28] decoder, trained for 80K iterations at a learning rate of 3×10⁻⁶ for the encoder and 10× larger for the decoder, on 8 A800-80G GPUs with batch size 16.
Online use. MQE outputs a probability map of error per pixel. That map becomes a penalty term, ℒ_eval, defined as the L1 norm of the error-probability map, pushing the matting network away from unreliable regions. Unlike the earlier unsupervised boundary loss in MatAnyone, this gives usable supervision on boundary regions using only segmentation masks.
Offline use. An automated dual-branch annotation pipeline produces VMReal. One branch (B_V) runs a video matting model such as MatAnyone [42], which is temporally stable; the other (B_I) runs an image matting model such as MattePro [47] guided by per-frame SAM 2 [29] masks, which gives sharper boundaries but weaker temporal consistency. MQE evaluates both, and a fusion mask M^fuse = M_I^eval ⊙ (1 − M_V^eval) selects pixels where only the image branch is reliable. The mask is smoothed with a Gaussian blur to avoid seam artifacts, and the final alpha is α_V ⊙ (1 − M^fuse) + α_I ⊙ M^fuse. The fused reliability map is the union M_V^eval ∪ M_I^eval. Training then uses a masked matting loss (masked L1, pyramid Laplacian over 5 levels, and masked temporal coherence) computed only where the reliability map equals 1, so the model no longer needs joint matting-plus-segmentation training.
Long videos. Because the training window is short, subjects' new clothing or body parts can be missed. The reference-frame strategy samples frames from outside the local window into memory, using the training scheme of [52], and applies random dropout of 0–3 boundary patches and 0–1 non-boundary patches per reference frame, each sized between 50 and 100 pixels, setting both RGB and alpha values to zero there.
The matting model itself is trained on 8 A800-80G GPUs, batch size 16, with clips cropped to 480×480 and 8 frames, following the MatAnyone backbone.
Why This Matters
Impact on research. The paper reframes a data problem as a supervision problem: instead of hand-annotating video mattes, it learns a model that can judge matte quality, then uses that judge both as a training signal and as an annotation engine. It also argues that the field's reliance on segmentation priors for semantic stability is what causes segmentation-like boundaries — and proposes an alternative rather than a better trade-off. The release of VMReal (about 28K clips, 2.4M frames) changes what is available for training video matting models at scale.
Real-world applications include:
- Visual effects and film post-production, where clean alpha channels with natural hair and edge detail are required for compositing.
- Video editing and short-form content creation, where creators isolate subjects without a green screen.
- Live streaming, video conferencing, and virtual backgrounds, where temporal stability (dtSSD, Conn) matters as much as per-frame accuracy.
- AR/VR and real-time avatar or telepresence systems, where a subject must be separated from arbitrary, uncontrolled backgrounds.
Industry relevance. The method is CNN-based and needs a segmentation mask only on the first frame, whereas GVM [5] relies on a video diffusion model and MaGGIe [9] needs a per-frame instance mask. That combination of simpler inference and higher accuracy is directly relevant to deployment in editing tools and streaming pipelines.
Future Directions
- Push MQE evaluation further. The paper defers additional evaluation and analysis of MQE to supplementary Sec. C.3, leaving open how reliable the evaluator is across domains beyond P3M-10k-derived training pairs.
- Close the loop between online guidance and offline curation. The two uses of MQE are currently separate stages; using curated data and online guidance more tightly together is a natural extension.
- Extend to non-human or more general subjects. The dataset discussions and pipeline lean on human-centric matting and filtering of a human-centric SA-V subset, so generalization to other foreground types is unaddressed in the main text.
- Improve the remaining hard cases. The paper's own qualitative examples still center on wind-blown hair and complex or backlit lighting, and the authors include a limitations discussion in supplementary Sec. D.
Target Audience
Researchers and graduate students in computer vision working on matting, segmentation, or video generation; dataset builders interested in model-assisted annotation and quality-assessment-driven curation; and applied engineers at VFX, video editing, streaming, or AR/VR companies who need production-quality alpha mattes from real footage. Readers should be comfortable with matting metrics (MAD, MSE, Grad, Conn, dtSSD) and modern encoder-decoder architectures.
Authors’ abstract
Video matting remains limited by the scale and realism of existing datasets. While leveraging segmentation data can enhance semantic stability, the lack of effective boundary supervision often leads to segmentation-like mattes lacking fine details. To this end, we introduce a learned Matting Quality Evaluator (MQE) that assesses semantic and boundary quality of alpha mattes without ground truth. It produces a pixel-wise evaluation map that identifies reliable and erroneous regions, enabling fine-grained quality assessment. The MQE scales up video matting in two ways: (1) as an online matting-quality feedback during training to suppress erroneous regions, providing comprehensive supervision, and (2) as an offline selection module for data curation, improving annotation quality by combining the strengths of leading video and image matting models. This process allows us to build a large-scale real-world video matting dataset, VMReal, containing 28K clips and 2.4M frames. To handle large appearance variations in long videos, we introduce a reference-frame training strategy that incorporates long-range frames beyond the local window for effective training. Our MatAnyone 2 achieves state-of-the-art performance on both synthetic and real-world benchmarks, surpassing prior methods across all metrics.