Research
Let Samples Speak: Mitigating Spurious Correlation by Exploiting the Clusterness of Samples
Overview Research area: Computer vision and natural language processing — specifically, robustness of deep neural networks against spurious correlations (model bias) in the training data. Technical le
- arXiv
- 2512.22874
- Published
- 2025-12-28
- Authors
- Weiwei Li, Junzhuo Liu, Yuanyuan Ren, Yuchen Zheng, Yahao Liu, Wen Li
AI summary
Overview
- Research area: Computer vision and natural language processing — specifically, robustness of deep neural networks against spurious correlations (model bias) in the training data.
- Technical level: Intermediate. The paper pairs an accessible geometric intuition with formal theorems and a standard benchmark suite, so it assumes familiarity with feature embeddings, empirical risk minimization (ERM), and worst-group accuracy.
- Scope: The paper proposes NSF (Neutralizing Spurious Features), a four-stage pipeline that detects, neutralizes, eliminates, and compensates for spurious features without bias attribute annotations, evaluated on four image/text debiasing benchmarks plus the CheXpert medical dataset.
What This Paper Is About
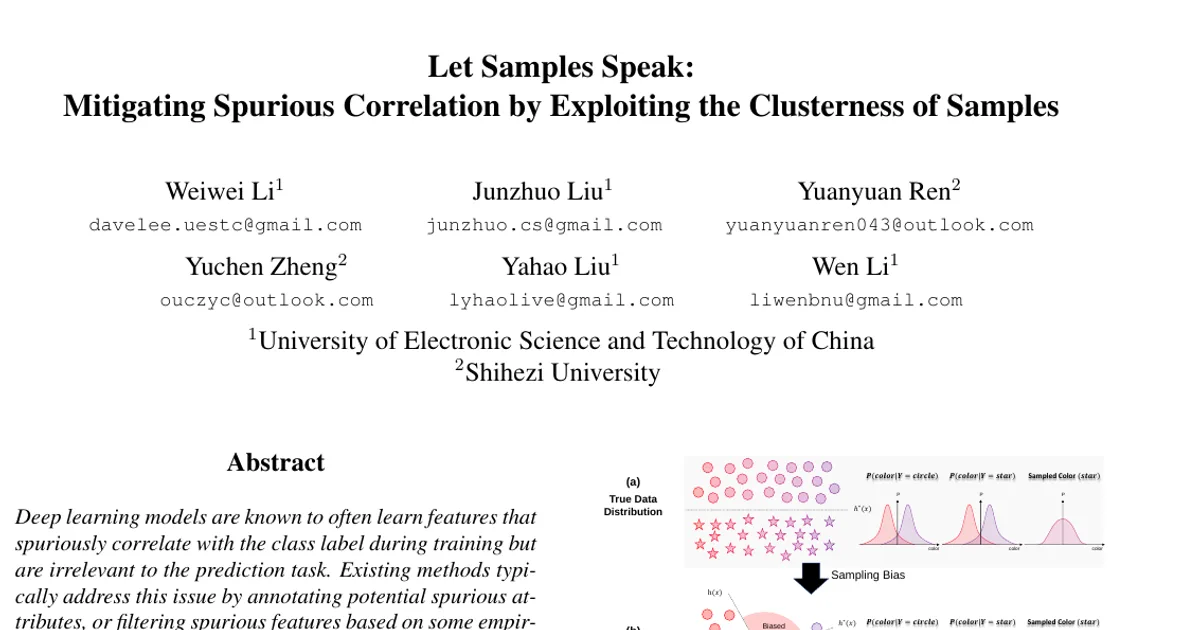
Deep models often latch onto features that happen to correlate with a label in the training data but are not actually predictive — such as background in bird photos or medical devices in chest X-rays — and this hurts performance on minority groups where the correlation does not hold. Most existing fixes either require human annotations of the spurious attribute or rely on task-specific assumptions such as "simple features are bias." This paper instead exploits a property of the feature space itself: samples influenced by a strong spurious feature sit away from their own class centroid, which lets the method separate and then remove those features without any bias labels.
Key Contributions
- A task-independent spurious-feature assumption. The paper introduces the "strong spurious assumption," which holds that samples affected by spurious features (minority groups) deviate from their class centroid while majority samples cluster near it. The authors provide a theoretical proof of its correctness for binary classification using a widely accepted debiasing data model.
- A bias-invariant representation estimator. Using only the sign of the relative distance to class centroids, the method separates a class into groups (denoted U_k and V_k) and estimates the unbiased conditional mean C_k of the true data distribution, without access to bias attributes or labels.
- A non-intrusive debiasing framework (NSF). Four steps — identifying bias presence, neutralizing spurious features, eliminating them via a learned linear transformation t(x) applied after a frozen encoder, and updating the classifier by fine-tuning on balanced minority sampling.
- Extensive empirical validation. Experiments on Waterbirds, CelebA, MultiNLI, CivilComments-WILDS, and CheXpert, plus ablations, training-time comparisons, a ViT-s architecture test, and a target/attribute swap on CelebA.
Main Findings
- Large worst-group accuracy gains over ERM: The abstract and introduction state an improvement in worst-group accuracy (WGA) of more than 20% compared to standard ERM; the introduction describes an average improvement of 20% in WGA across four image and text tasks with known spurious correlations plus one medical dataset.
- Best average WGA among compared methods: In Table 1, NSF achieves a mean WGA of 82.01 across Waterbirds, CelebA, MultiNLI, and CivilComments-WILDS, versus 61.24 for ERM. Per-dataset WGA: Waterbirds 91.12 (± 0.0063), CelebA 84.27 (± 0.0047), MultiNLI 73.12 (± 0.0008), CivilComments 79.51 (± 0.0022), with standard deviations over 10 random seeds. Corresponding i.i.d. accuracies are 95.65, 88.70, 80.43, and 87.19.
- Competitive without bias labels: NSF requires no bias labels in either the training or validation set, yet reaches WGA superior or comparable to GroupDRO (mean WGA 81.98) and DFR (81.50), which use bias labels. On Waterbirds, GroupDRO reaches 91.40 WGA and DFR 92.90, both above NSF's 91.12; on CelebA and MultiNLI NSF's 84.27 and 73.12 exceed GroupDRO's 88.90 and 77.70 respectively — note the paper reports these values as given.
- Medical domain improvement: On CheXpert, NSF reaches 70.21 WGA and 81.94 i.i.d. accuracy, a gain of +40.00 over ERM (31.21 WGA, 89.78 i.i.d.). GroupDRO, which uses bias labels in both training and validation, reaches 74.50 WGA (+43.29); JTT reaches 60.40 (+29.19).
- Ablations confirm each component: On Waterbirds, ERM + t(x) gives 87.85 WGA, minority resampling (MR) + x gives 86.92, and the full combination gives 91.43 (baseline 72.60). Finetuning the classifier with transformed features t(x) without resampling alone raises WGA by 15.25%.
- Unbiased means matter: Replacing samples in U_k and V_k with randomly chosen examples drops mean accuracy to 90.60% and WGA to 73.99 (versus 95.65 and 91.12), a roughly 6% mean-accuracy drop; the authors explain this by analogy — transforming a white cat toward the majority-group mean turns it black.
- Low-weight channels correspond to spurious features: Discarding channels with the lowest coefficient w in the transformation t(x) outperforms randomly discarding the same proportion, supporting that low w correlates with spurious features.
- ViT-s results: On Waterbirds, ViT-s with NSF shows +5.56 in mean accuracy (90.78 to 96.34) and +21.96 in WGA (67.13 to 89.09) compared to ERM.
- Swapping target and spurious attribute on CelebA: +1.87 in WGA (90.56 to 92.43) and -2.79 in mean accuracy (98.60 to 95.81) compared to ERM.
- Fast runtime: Table 5 reports the transformation t(x) takes 1s on Waterbirds, 2s on CelebA, 15s on MultiNLI, 2s on CivilComments-WILDS (mean 5s); the classifier h'(x) takes 1s on each (mean 1s).
- Failure mode acknowledged: The assumption that models favor strong features may limit NSF's applicability under weaker biases.
Methodology in Plain English
The authors start from a data-generation model in which each input is composed of three parts: a core feature tied to the label y, a spurious feature a that correlates with the label with probability ρ (where ρ ∈ (0.5, 1)), and Gaussian noise. A scalar B ≥ 1 controls how influential the spurious attribute is. If ρ = 0.5, sampling is fair and the spurious feature carries no signal; otherwise the spurious feature shifts the conditional expectation of the data away from the true distribution.
From this model the paper derives Theorem 1: when 1 − (2ρ − 1)²B⁴ < 0, two samples of the same class sit on opposite sides of the centroid — measured by the relative-distance function d(x_i, ρ) — exactly when their spurious attributes differ. In practice, this means the method can flag spurious features simply by checking whether any same-class samples have relative distances with opposite signs, and can sort each class into a majority group and a minority group without knowing what the bias actually is.
Theorem 2 then shows the true (unbiased) class mean C_k can be estimated by averaging the majority group U_k and the minority group V_k with equal weight — half from each. Classes that do not contain both a majority and minority group are masked out.
With C_k in hand, NSF learns a channel-wise linear transformation t(x) = w(x − b) + b on top of a frozen ERM-trained encoder, trained to pull every sample toward the estimated unbiased mean. The paper shows analytically that the optimal solution sets the weight on the spurious and noise channels to zero and preserves the core channel, so the transformation deletes spurious information while keeping the class signal. Finally, a new classifier h' is trained on the transformed features using cross-entropy, with a balanced sampling scheme drawn from the majority and minority groups found earlier. Stop-gradient operations keep the frozen encoder and the transformation from being updated during classifier training.
Why This Matters
Impact on research. The paper offers a bias-agnostic alternative to methods that depend on known bias attributes, group labels, or task-specific heuristics like simplicity bias. Its core claim — that bias-influenced samples are geometrically separable from majority samples — turns a statistical problem into a clustering-style geometry problem and gives practitioners a post-hoc, non-intrusive correction that operates on frozen embeddings.
Real-world applications:
- Medical diagnosis from chest radiographs, where models trained on CheXpert-like data can key on medical devices instead of pathology; the paper reports the ERM model focusing on devices, and the debiased model on clinically relevant areas.
- Facial attribute analysis (e.g., CelebA), where gender can spuriously correlate with hair color; the paper's CAM visualizations show ERM attending to hair and the debiased model to the face.
- Content moderation and toxicity detection, where demographic identity terms in CivilComments-WILDS can spuriously correlate with the toxic/non-toxic label.
- Wildlife and object recognition, where background context in Waterbirds-type datasets substitutes for the actual object.
Industry relevance. Because NSF adds only a lightweight linear transformation and a classifier fine-tune, the reported runtimes of a few seconds per dataset (mean 5s for t(x), 1s for the classifier) make it far cheaper than retraining or heavy group annotation. Avoiding bias-attribute labeling also removes a costly, often infeasible data-collection step, making it attractive for deployment teams that cannot enumerate every bias in their data.
Future Directions
- Weaker-bias regimes. The authors explicitly flag that the strong spurious assumption may not hold when biases are weak, and state this should be addressed in future work. The theoretical condition also requires 1 − (2ρ − 1)²B⁴ < 0, so the behavior near that boundary is an open question.
- Mixing with label-supervised methods. On CheXpert, GroupDRO with bias labels reaches 74.50 WGA versus NSF's 70.21, suggesting room to combine NSF with group-aware techniques when partial annotation exists.
- Broader architectures and modalities. The paper reports a ViT-s test on Waterbirds only; extending the pipeline to more backbones, tasks, and non-vision domains is a natural next step.
- Reconciling high i.i.d. accuracy with WGA. NSF's i.i.d. numbers on Waterbirds (95.65) and CelebA (88.70) are below ERM's (97.30 and 95.60), so characterizing the accuracy-robustness trade-off and closing that gap remains an open problem.
Target Audience
Researchers and graduate students working on robustness, fairness, and out-of-distribution generalization in machine learning; practitioners who need to debias deployed vision or NLP models without bias attribute annotations; and medical-AI or content-moderation teams evaluating lightweight post-hoc corrections. Readers who want a concrete geometric mechanism plus a formal treatment of why it works will find the theorems and ablation tables the most valuable parts, while engineers focused on deployment will find the runtime figures and the frozen-encoder design most relevant.
Authors’ abstract
Deep learning models are known to often learn features that spuriously correlate with the class label during training but are irrelevant to the prediction task. Existing methods typically address this issue by annotating potential spurious attributes, or filtering spurious features based on some empirical assumptions (e.g., simplicity of bias). However, these methods may yield unsatisfactory performance due to the intricate and elusive nature of spurious correlations in real-world data. In this paper, we propose a data-oriented approach to mitigate the spurious correlation in deep learning models. We observe that samples that are influenced by spurious features tend to exhibit a dispersed distribution in the learned feature space. This allows us to identify the presence of spurious features. Subsequently, we obtain a bias-invariant representation by neutralizing the spurious features based on a simple grouping strategy. Then, we learn a feature transformation to eliminate the spurious features by aligning with this bias-invariant representation. Finally, we update the classifier by incorporating the learned feature transformation and obtain an unbiased model. By integrating the aforementioned identifying, neutralizing, eliminating and updating procedures, we build an effective pipeline for mitigating spurious correlation. Experiments on image and NLP debiasing benchmarks show an improvement in worst group accuracy of more than 20% compared to standard empirical risk minimization (ERM). Codes and checkpoints are available at https://github.com/davelee-uestc/nsf_debiasing .