Research
Jev in the Wild: A Data-Driven Analysis of the Jev Model's Functionality, Applications and Ecosystem
Overview Research area: Empirical software engineering / mining software repositories, applied to an emerging AI decision model ecosystem (cs.SE). Technical level: Intermediate. The core ideas are acc
- arXiv
- 2609.30216
- Published
- 2026-09-24
- Authors
- Guoming Ling, Muen Xue, Zijian Ye
AI summary
Overview
Research area: Empirical software engineering / mining software repositories, applied to an emerging AI decision model ecosystem (cs.SE).
Technical level: Intermediate. The core ideas are accessible, but the paper uses GitHub-derived metrics (stars, repository counts), decision-model interface terminology (Choice, Noul, Score), and annotation pipelines that assume some familiarity with LLM-based tooling.
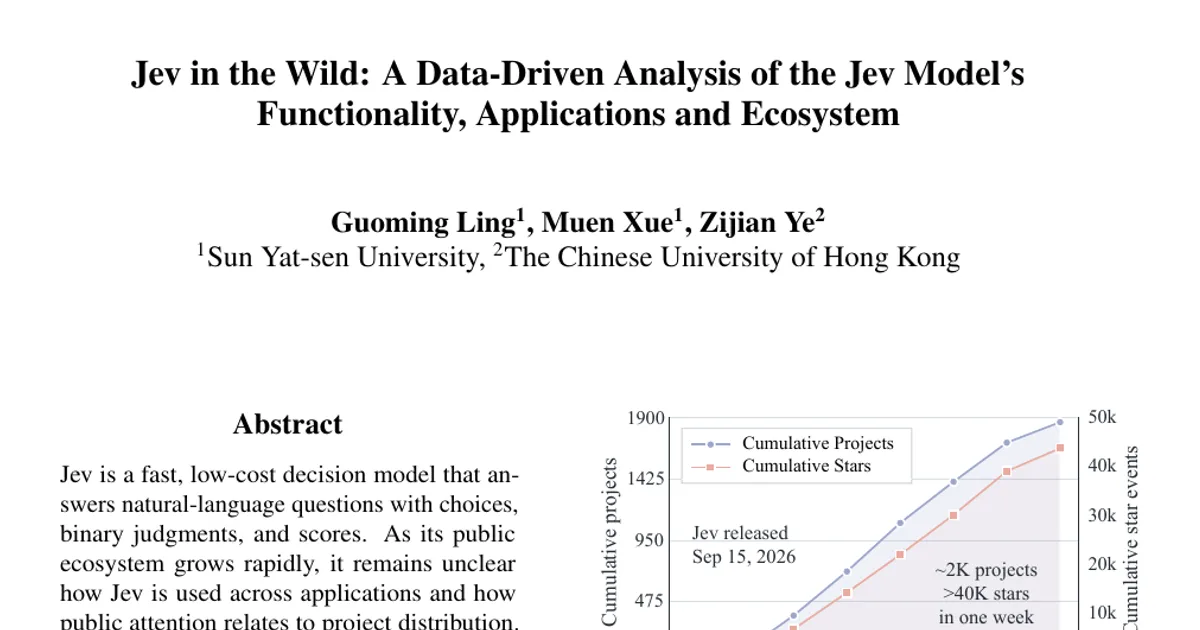
One-sentence scope: A quantitative snapshot of 2,170 public GitHub projects built around the Jev decision model as of September 22, 2026, covering how the ecosystem grew, what Jev is used to decide, which interfaces developers adopt, and how public attention compares with project volume.
What This Paper Is About
Jev is a model that answers natural-language decision questions with a choice, a binary judgment, or a score, and it exposes three interfaces: Choice (select among options), Noul (binary judgments), and Score (rate an input against predefined levels). After Jev's release on September 15, 2026, a large number of public projects appeared quickly, but nobody had systematically measured how the model is actually being used or whether public attention matches where the projects are. The authors build a verified dataset of 2,170 public Jev repositories and analyze growth, application domains, decision purposes, interface combinations, and star distribution across categories.
Key Contributions
- Growth quantification. The authors measure the growth of public Jev projects and GitHub attention over time, describing the ecosystem's expansion as rapid and bursty, with both new repositories and integration into pre-existing repositories.
- Usage characterization. They characterize how Jev is used along three axes: application domain, decision purpose, and interface adoption (single, paired, or all-three combinations of
Choice,Noul, andScore). - Supply-versus-attention comparison. They compare the distribution of project counts (treated as supply) with mean GitHub stars per project (treated as a proxy for demand), showing that attention is concentrated in ways that do not track project volume.
- A dataset and taxonomy. They release the 2,170-project dataset and an 8-category, 18-subcategory taxonomy intended to support representative evaluation design and future study of how decision models integrate into larger systems.
Main Findings
-
Explosive first-week growth. Of the 2,170 repositories in the dataset, 1,865 were created in the week following Jev's September 15, 2026 release, while 305 existing repositories integrated Jev. During that same week, the new repositories gained 43,750 stars.
-
No single domain dominates. The two largest categories, Content & Expert Tasks and Search & Memory, account for only 17.8% and 17.6% of projects, respectively. In absolute counts, Content & Expert Tasks has 387 projects and Search & Memory has 381.
-
Attribute judgment is the leading decision purpose. Attribute judgment appears in 77% of projects, followed by scoring or ranking at 52% and action selection at 31%. Among projects with an identified purpose, 69.7% use Jev for two or more purposes.
-
All three interfaces are widely used.
Choiceappears in 81.0% of projects,Noulin 72.2%, andScorein 45.4%. Most projects use at least two interfaces, and 36.8% use all three. -
Jev's role shifts with the surrounding workflow. Action selection accounts for 52% of purpose labels in Simulation & Control and 47% in Interface Agents. Model and tool selection accounts for 27% of labels in Routing & Automation but only 6% in Software Engineering. Content filtering is 21% of labels in Search & Memory, and outcome judgment is 24% in Safety & Governance. Despite these differences, attribute judgment remains the leading purpose in six of the eight categories, and attribute judgment plus scoring account for about 70% of labels in Search & Memory and 75% in Content & Expert Tasks.
-
Attention is far more concentrated than project supply. Routing & Automation receives 41.4% of all stars, with Model & Tool Routing alone at 32.6%. Routing & Automation contains 250 projects averaging 364 stars per project, and Interface Agents contains 175 projects averaging 271 stars. Together these two categories are 19.6% of projects but receive 63.0% of all stars. By contrast, Content & Expert Tasks (387 projects) averages 31 stars per project and Search & Memory (381 projects) averages 37.
-
Nearly identical project counts, very different attention. Routing & Automation and Simulation & Control have 250 and 252 projects respectively, but average 364 and 8 stars per project. The authors interpret this as uneven visibility rather than unmet demand, noting that stars measure interest in whole repositories and may concentrate in a few prominent projects.
-
Documented limitations. The analysis is a snapshot as of September 22, 2026, and covers only public GitHub repositories, excluding private repositories and commercial applications.
Methodology in Plain English
The authors built the dataset in three stages. First, candidate retrieval: they searched GitHub with predefined queries based on Jev-related keywords, API endpoints, and SDK references, combining repository search and code search, then deduplicated results using GitHub repository IDs. Second, project verification: each candidate repository was inspected by a GPT-6 Luna Max agent, and a repository was included only when its public code or documentation gave clear evidence that Jev is used for a concrete task; repositories that merely mentioned Jev or provided generic wrappers or SDKs without a concrete application were excluded. Third, annotation: a GPT-6 Luna Max agent labeled each included project's primary application domain, decision purposes, interface usage, and other attributes. Application domain describes what the project is built for, while decision purpose describes the role Jev plays inside the project. Key inclusion decisions and application-domain labels were independently reviewed by a second GPT-6 Luna Max agent, with disagreements resolved by inspecting the original repository materials. This yielded 2,170 verified projects. The authors then analyzed growth over time, distribution across 8 major categories and 18 subcategories, decision purposes, interface combinations, and the relationship between project counts and star counts.
Why This Matters
Impact on research. The paper turns a fast-moving, anecdotal phenomenon into a measured one. It provides a taxonomy and dataset for selecting evaluation settings, and it argues that evaluation of general-purpose decision models should cover both recurring decision purposes and the application contexts in which the models are embedded, including less visible applications that the star-based attention signal misses. It complements prior task-level evaluations of Jev (for example, work on service orchestration, agent memory, and action selection with confidence-based fallback) with an ecosystem-level view.
Real-world applications. The appendix documents seven representative integration patterns that show how typed decisions become program actions:
- Browser agents: Jev Ultrafast submits a
Choicequestion for the next browser operation plus separate target questions, and a separate small language model generates text to be typed into a field. - Code review: Jev Review uses
Noulquestions to screen for correctness, security, reliability, compatibility, and test-coverage concerns,Choiceto select a supporting diff hunk and classify a failure mechanism, andScoreto estimate severity, producing triage leads rather than a free-form review. - Context management: Fast Jev Compaction asks two
Noulquestions per eligible tool interaction—whether remembering the tool call is useful and whether the full tool result is needed—and retains, shortens, or removes the interaction based on thresholds. - Safety gating: pi-jev places
Noulquestions about destructive behavior, data exfiltration, and scope exceedance plus aScorefor potential impact in front of agent tool execution, with shadow and enforce modes. - Routing and games: jev-router recommends a model tier with a confidence value per turn, and TypeSafe Mario uses
Choiceto select legal controller macros,Noulto judge whether a forward jump is useful, andScoreto rate immediate danger.
Industry relevance. The finding that most projects combine multiple interfaces suggests that teams building decision components should support categorical selection, binary judgment, and scoring together rather than picking one. The finding that surrounding code, not the model, usually holds final authority—thresholds, policy, fallback, and user overrides in the documented examples—gives practitioners a concrete integration template. The supply-versus-attention mismatch also warns that star counts are a poor proxy for where a model is actually deployed.
Future Directions
- Tracking ecosystem change over time. Because the study is a snapshot as of September 22, 2026, the authors note that project counts, usage patterns, and public attention may shift and could change the conclusions. Longitudinal follow-up would test whether the observed patterns persist.
- Covering non-public adoption. Private repositories and commercial applications are outside the scope, and the authors state these may exhibit different usage patterns. Extending the analysis beyond public GitHub is an open problem.
- Building representative evaluations. The authors call for evaluation settings that include both recurring decision purposes and the application contexts in which they are used, and specifically for including less visible applications rather than relying on attention-concentrated ones.
- Understanding the attention mismatch. The routing and interface-agent categories receive attention disproportionate to their project counts, while several larger categories receive much less. Why visibility concentrates this way—and whether it reflects genuine deployment differences—remains unexamined.
Target Audience
Researchers and practitioners in software engineering and applied machine learning who study or build LLM-based decision components; developers integrating lightweight decision models into agents, routing layers, or review pipelines; and evaluation designers who need a taxonomy of real-world decision purposes and application domains to construct representative benchmarks. Tooling and platform teams assessing how a new model gets adopted in practice will also find the supply-versus-attention analysis useful.
Authors’ abstract
Jev is a fast, low-cost decision model that answers natural-language questions with choices, binary judgments, and scores. As its public ecosystem grows rapidly, it remains unclear how Jev is used across applications and how public attention relates to project distribution. To answer these questions, we conduct a large-scale, data-driven analysis of 2,170 publicly available Jev projects collected from GitHub as of September 22, 2026. We find rapid early growth in Jev's public ecosystem, with both new projects and integration into existing repositories. Across diverse domains, projects use Jev for multiple decision purposes and combine its interfaces. Attribute judgment and scoring are widely used, while the use of action selection, content filtering, and model and tool selection varies across domains. These patterns suggest that Jev serves as a reusable decision component whose functionality varies with the surrounding workflow. Meanwhile, public attention is concentrated in routing and interface agents and does not track project counts. Our findings provide a quantitative view of Jev's emerging ecosystem and inform the design and evaluation of general-purpose decision models across diverse application contexts.