Research
Inverting Multi-Vector Visual Document Indices
Overview Research area: Information retrieval security and privacy, specifically the invertibility of multi-vector (late-interaction) visual document indices built by vision-language retrievers. Falls
- arXiv
- 2610.09920
- Published
- 2026-10-07
- Authors
- Zhuchenyang Liu, Yao Zhang, Yu Xiao
AI summary
Overview
Research area: Information retrieval security and privacy, specifically the invertibility of multi-vector (late-interaction) visual document indices built by vision-language retrievers. Falls at the intersection of cs.IR and embedding-inversion privacy research.
Technical level: Advanced. Following the argument requires familiarity with late-interaction retrieval (ColPali-style), patch-based vision transformer encoders, flow matching / diffusion generative models, and re-identification metrics.
Scope: The paper demonstrates that a stored multi-vector index of a document page can be inverted back into a legible page image by an attacker with no side information, and evaluates two cheap defenses against that attack.
What This Paper Is About
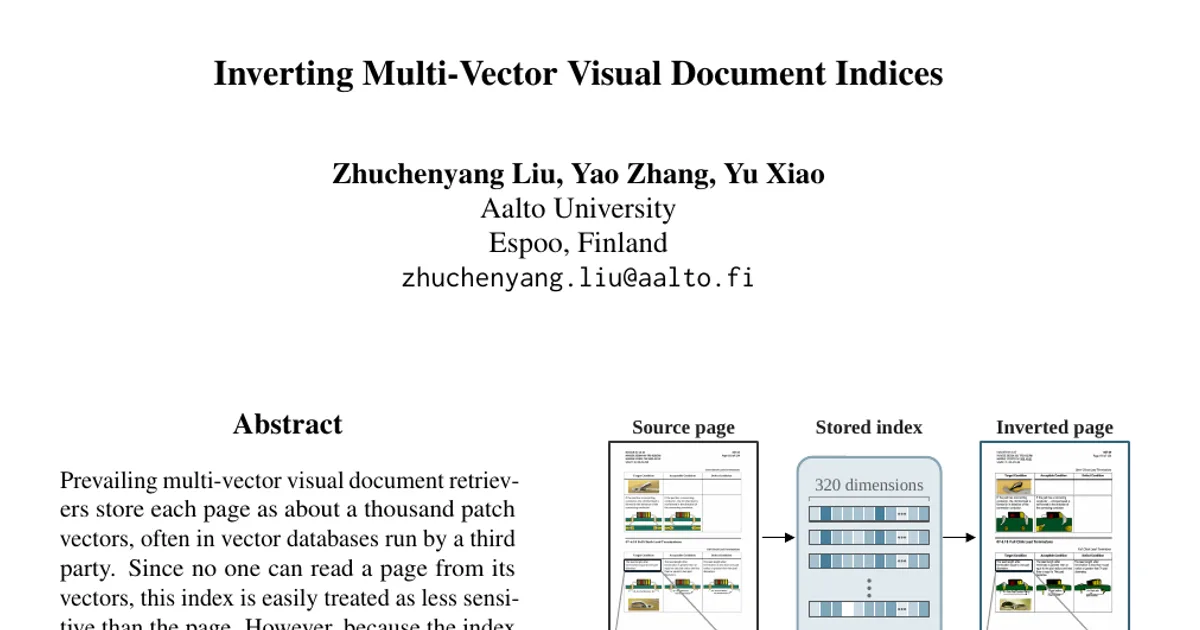
Visual document retrievers encode each page image as roughly a thousand patch vectors, stored in vector databases that are frequently run by a third party. Because no one can read a page from its vectors, these indices are often treated as less sensitive than the pages themselves. The paper asks whether whoever runs or breaches such a store can reconstruct the page from its stored index alone, and finds that they can.
Key Contributions
-
A conditional flow-matching inverter for visual document indices. The attack reframes index inversion as conditional document image generation: a dual-stream MMDiT (following the Qwen-Image design) is repurposed with the stored index replacing the text prompt, generating the page in the latent space of a frozen VAE with spatial factor 8 and 16 channels.
-
An attack that operates under zero side information. The authors show that the three facts a stored index omits — which encoder produced it, the page shape, and (for a shuffled index) the permutation — can each be inferred from the vectors alone. Encoder identification is evaluated against a pool of 13 public multi-vector retrievers with embedding dimensions 128, 320 and 640.
-
Measurement of leakage along two axes. Content leakage (word recall, NED, sensitive-token recall via PaddleOCR transcripts) and identity leakage (re-identification, where the inverted page is encoded as a query and ranked against all 19,252 indexed pages, plus an independent-judge variant that uses an encoder which played no part in producing the index).
-
Evaluation of two cheap protections, pooling and shuffling. The paper reports that hierarchical token pooling at factors 3 and 9 resists inversion in their experiments, while shuffling does not, because a trained position model can restore the vector order.
Main Findings
-
Raw indices are invertible. From the raw index of Tomoro-ColQwen3-8B (E_A), inverted pages recover 47.4% of reference words at NED 0.292 and 45.0% of sensitive tokens, against a kNN baseline of 0.234 word recall / 0.146 sensitive recall and a null model of 0.001 word recall. The pages rank their source page first 98.4% of the time among 19,252 pages (top-5 0.995, MRR 0.989, median rank 1), and 0.977 under the independent judge E_B.
-
The null model and shared vocabulary do not explain the result. Sampling the same inverter with its condition dropped recovers 0.1% of words. Two samples from the same index agree with each other (word F1 0.476) about as much as each agrees with the source (0.480).
-
OCR underestimates leakage. 75.0% of the 44 scored pages with word recall below 0.1 still rank their source page first, and the two measures correlate only weakly (ρ = 0.13).
-
Pooling resists the attacks tested here. Word recall falls to 7.6% at pooling factor 3 and 8.1% at factor 9, below the kNN baseline, with NED rising to 0.858 and 0.879. Only 21 and 10 of the 2,000 inverted pages rank their source first, against 1,968 from the raw index. Inverting a pooled index remains open.
-
Shuffling alone also suppresses the attack. Without a position model, the permutation-invariant set inverter reaches 8.4% word recall and 3.8% re-identification, though it is given the true page shape.
-
But the order can be recovered. A trained position model places shuffled vectors of E_A with a mean absolute error of 1.8 index rows and 4.5 index columns, against 12.6 and 11.3 for a random order. Fed the re-ordered index, re-identification rises from 3.8% to 93.5% (87.7% under the independent judge), with word recall 23.1% and sensitive-token recall 21.2%.
-
Identity recovers more fully than content. With the restored order, NED stays near its cap (0.925) even as word recall reaches 23.1%, because whole lines and blocks appear at the wrong height. It indicates each vector carries the content of its own patch.
-
The attack transfers to a second retriever. Applied unchanged to ColQwen3.5-4.5B (E_B), trained on 346,770 pages instead of 682,818 and without VDR-MEGA-2, inverted pages rank their source first 70.2% of the time (60.5% under the independent judge), against 15.4% for the kNN baseline — but word recall, 7.9%, stays below the baseline's 22.3%.
-
The encoder, not the data, explains the weaker E_B content result. An inverter for E_A trained on the same three collections as the E_B inverter recovers 55.5% of words and re-identifies 98.9% of pages.
-
Preliminaries are nearly always correct. Encoder identification succeeds in all 26,000 decisions; periodicity recovers the shape of 99.2% of raw E_A indices, the set classifier 99.1% and 95.7% at pooling factors 3 and 9, the aspect head 99.95% of shuffled ones, and the shape is 0.795 correct for E_B raw indices.
Methodology in Plain English
The authors define an attacker who holds the stored indices and a set of public encoders, may train on public documents, but has no page shape, source, metadata, or access to any indexed page — what they call zero side information. They consider three storage configurations the attacker must handle: raw (vectors in the encoder's raster order), pooled (vectors merged by hierarchical token pooling at factor 3 or 9), and shuffled (raw vectors stored under a random permutation).
The attack proceeds in stages. First, the attacker identifies which public encoder produced a store by checking candidate output dimensions, unit norm and vector count, then comparing each stored index against a reference set of 2,000 public pages encoded by each candidate. Second, models are trained for that encoder on public pages. Third, at inference, the page shape is inferred — for a raw index, from the lag at which vector similarity peaks (the row width is a period of the sequence, because vectors one row apart in the same column tend to be similar); for a pooled index, from a small permutation-invariant set classifier whose logits are masked to shapes compatible with the vector count; for a shuffled index, from an aspect-ratio head on the position model. For shuffled indices, a Transformer encoder over the unordered set predicts each vector's normalised row and column, the Hungarian algorithm assigns those coordinates one-to-one to the n_h × n_w slots, and the re-ordered index goes to the ordered inverter.
The inverter itself is trained to generate pages rather than regress them, because the L2 optimum of a regression decoder is the conditional mean E[I | C], which blurs every glyph the index leaves ambiguous. It minimises the flow-matching objective on the rectified-flow path, with the condition dropped with probability 10% and replaced by a learnable null token for classifier-free guidance. Sampling integrates the guided velocity over 50 Euler steps at guidance scale γ = 4, chosen once on 100 in-distribution validation pages.
Evaluation uses the eight public corpora of ViDoRe v3 (19,252 pages), with a fixed set of 2,000 pages, 250 sampled uniformly from each domain, covering 11 page shapes. Only 8 of those 2,000 pages (0.4%) have a near-identical training counterpart, and removing them changes no reported number. Baselines are the null model, a kNN baseline using the nearest training page's stored index, chance for rank metrics, and VAE reconstruction of the source page as an upper bound.
Why This Matters
Impact on research. Embedding inversion was already established for text embeddings; this paper extends that known class of risk to multi-vector visual indices, where the target modality is pixels carrying legible, laid-out text rather than a short string. The finding that each vector carries patch-level content and that a random permutation can be undone by a trained position model is the most distinctive result: it means a shuffle changes storage order without changing what the store reveals, since late-interaction scoring does not depend on vector order.
Real-world applications affected:
- Hosted vector databases. The threat applies where indices are held apart from pages under opaque identifiers while the page images sit in separate, access-controlled storage — the index becomes the only copy an intruder obtains.
- Separate access tiers. Systems that grant a provider or engineer access to the index but not to the documents it encodes would leak page content under this attack.
- Backups and index snapshots. Snapshots and backups of a late-interaction index carry the same recoverability as the live store.
- Retrieval-augmented generation over documents. Prior privacy work on RAG targets the operational interface (prompting the generator, inferring datastore membership, protecting raw query text); this paper targets the stored representation itself, which those interfaces do not cover.
Industry relevance. Late-interaction retrievers are described as among the strongest on current benchmarks and are deployed through vector databases and dedicated engines, often run by third parties. The authors stress that the weakness is a property of the stored representation rather than elicited model behaviour: the encoders function as designed, and the risk follows from storing one vector per patch in raster order — a practice shared across late-interaction retrievers — so no single vendor can patch it. The remedy lies with the store operator, which is who the recommendations address.
Future Directions
- Inverting pooled indices, which the authors explicitly say remains open and which their attacks do not achieve.
- Separating real leakage from invented content. Because the inverter samples from a learned distribution, it can output a plausible page even when nothing was recovered; drawing several samples per index and keeping only what they share is proposed as a way to isolate high-confidence leakage.
- Larger or longer-trained inverters and better-matched training data. The ordered inverter's validation loss was still falling at 100k steps, and a smaller, better-matched training set alone raised word recall from 0.474 to 0.555, so the reported leakage is framed as a lower bound.
- Untested protections. The paper lists additive noise, quantisation, keyed random projections, encrypted or private late-interaction retrieval, and access control on the store as defenses it did not evaluate.
- Encoders outside the pool. Stores produced by a private encoder, and encoder identification beyond the 13 public retrievers tested, are outside the paper's scope.
Target Audience
Researchers in information retrieval, privacy and security of machine learning systems, and multimodal representation learning will get the most from this paper, along with engineers who operate or procure vector databases for document retrieval and need to decide how a late-interaction index should be stored and protected. Readers without a background in late-interaction retrieval or generative image models will need to work through the retrieval scoring and flow-matching preliminaries first.
Authors’ abstract
Prevailing multi-vector visual document retrievers store each page as about a thousand patch vectors, often in vector databases run by a third party. Since no one can read a page from its vectors, this index is easily treated as less sensitive than the page. However, because the index keeps one vector per patch in raster order, and each vector is computed by a vision-language model pre-trained to read documents, we hypothesize that whoever runs or breaches the store can reproduce a page from its index alone. We frame inversion as conditional document image generation and infer from the vectors what the attack needs: the encoder, the page shape and, for shuffled vectors, their order. On the ViDoRe v3 benchmark, pages inverted from raw indices recover 47% of the words and 45% of the sensitive tokens. Used as queries against the stored indices, they rank their source page first 98.4% of the time. We test two cheap protections, token pooling and shuffling, which both cut word recall to about 8%. A model that restores the order of a shuffled index raises the share of source pages ranked first from 3.8% to 93.5%, while inverting a pooled index remains open. To test generalisation, we apply the same attack unchanged to another multi-vector retriever: its inverted pages still rank their source page first 70.2% of the time, though its word recall stays below a nearest-neighbour baseline. Multi-vector visual document retrievers are therefore vulnerable to inversion through their stored index, which should be protected like the documents it encodes.