Research
GTR: Gated Token Recurrence for Efficient Dense Prediction
Overview Research area: Computer vision — efficient vision backbones for dense prediction (object detection, segmentation, pose, depth), with hardware-aware kernel and deployment work. Technical level
- arXiv
- 2609.26590
- Published
- 2026-09-22
- Authors
- Zhe Feng, Longfei Liu, Wei Liu, Kai Chen, Jiangang Kong, Wei Zhou, Yifeng Qian, Dexiong Chen, Xuanlong Yu, Xi Shen
AI summary
Overview
Research area: Computer vision — efficient vision backbones for dense prediction (object detection, segmentation, pose, depth), with hardware-aware kernel and deployment work.
Technical level: Advanced. The paper assumes familiarity with attention, linear/recurrent token mixers, knowledge distillation, and GPU kernel execution, though the core ideas are stated clearly enough for a motivated non-specialist.
Scope: The paper introduces Gated Token Recurrence (GTR), a softmax-free linear-complexity vision backbone built on gated linear attention with alternating scan directions and a spatially enhanced SwiGLU block, distilled from a detection-specialized DINOv3 teacher, and evaluates it across six dense-prediction tasks, four model scales, and edge deployment on NVIDIA DRIVE AGX Thor.
What This Paper Is About
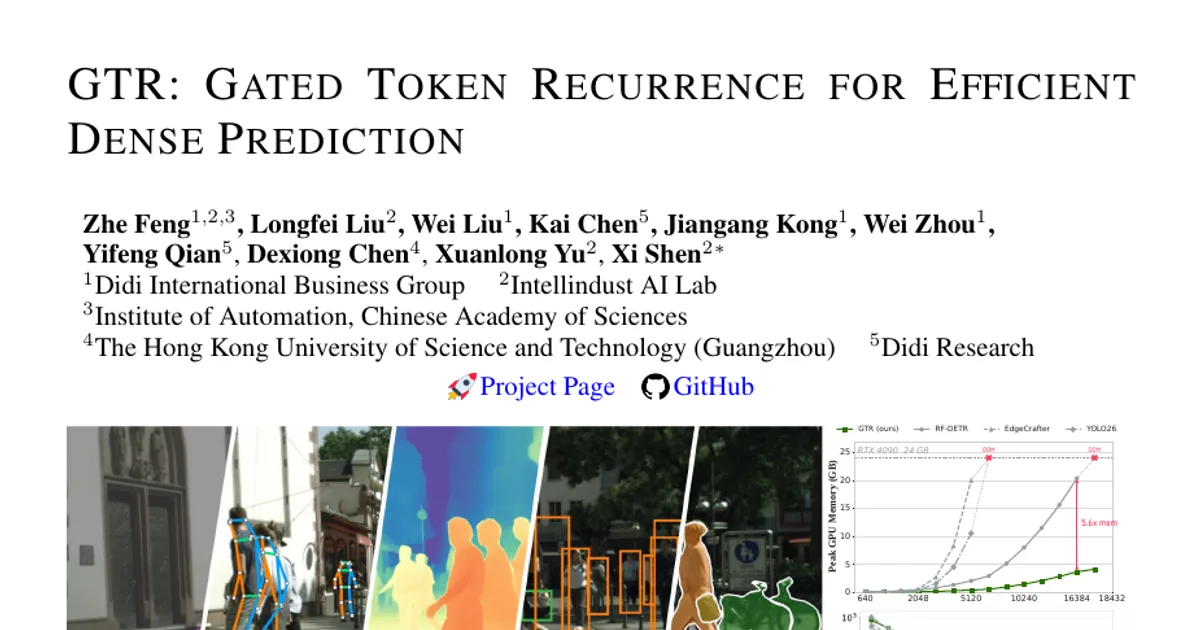
Self-attention vision backbones work well on dense prediction, but global softmax attention scales quadratically with the number of image tokens, so high-resolution images become increasingly expensive to process — especially on edge hardware. The authors ask whether linear attention can serve as a general-purpose vision backbone that stays accurate across many dense-prediction tasks while converting its theoretical efficiency into real measured gains in memory and latency. Their answer is GTR, a single-scale recurrent backbone that combines gated linear attention, four-directional scanning across depth, and depthwise-convolution-augmented SwiGLU, trained by a deliberately minimal distillation objective.
Key Contributions
-
A single-scale linear-attention backbone. GTR combines gated token recurrence with four-directional scanning cycled across depth and "Spatial SwiGLU" (depthwise convolution inside the SwiGLU value branch), providing complementary global and local spatial modeling while remaining linear in the number of tokens.
-
Demonstrated generality and scalability. The same backbone design is distilled and adapted across six dense-prediction tasks (object detection, instance segmentation, human pose estimation, oriented object detection, semantic segmentation, monocular depth estimation) and four model scales (S, M, L, X).
-
A minimal distillation recipe. GTR is aligned to a frozen, detection-specialized DINOv3 teacher using only final-layer patch-token alignment through a learned linear projection and a single squared L2 loss — no masked-token prediction, no intermediate-layer supervision, no attention-module alignment.
-
Practical edge deployment. A specialized chunkwise CUDA operator computes chunk summaries in parallel and propagates recurrent context through a boundary-state scan (4.0x faster than FLA v0.5.0 at 1.6K tokens on RTX 4090), and TensorRT graph-kernel co-optimization brings GTR to DRIVE AGX Thor with 2.282–8.769 ms median batch-one latency across six tasks and four scales.
Main Findings
-
Detection accuracy and latency. With Objects365 detector pre-training, GTR-S/M/L/X reach 53.6/57.3/58.9/59.4 COCO val2017 box AP. GTR-L reaches 58.9 AP at 1.908 ms median latency under compiled FP16, batch-one inference on an RTX 4090, outperforming all L-scale baselines in both AP and latency. GTR-X reaches 59.4 AP at 2.115 ms, compared with 58.6 AP at 3.243 ms for RF-DETR-X. Without Objects365 pre-training, GTR reduces latency relative to ECDet across all four scales.
-
Transfer across tasks. GTR-S/X achieve 45.0/49.8 mask AP on COCO instance segmentation without SAM2-generated pseudo masks, with GTR-X reaching 49.8 mask AP at 25.3% lower latency than RF-DETR-Seg-X. Pose estimation reaches 70.1/75.5 keypoint AP, improving on ECPose at both S and X scales with lower latency. On DOTA-v1.0 oriented detection, GTR-X achieves 81.3 AP50 at 3.960 ms versus 5.085 ms for YOLO26x-obb. On Cityscapes semantic segmentation, GTR-S/X achieve 81.5/83.6 mIoU with a lightweight FCN head, with GTR-X matching 83.6 mIoU at 19.5% lower latency than YOLO26-sem. On NYU Depth V2, GTR improves delta-1, AbsRel, and RMSE over the evaluated YOLO26 depth variants at both scales, without NYU-specific fine-tuning.
-
Simple distillation outperforms more complex recipes. Under the same teacher, student, and COCO schedule, final-output squared L2 alignment reaches 50.7 AP with one distillation stage and one loss, versus 50.0 AP for ViT-Linearizer (one stage, two losses) and 48.2 AP for ViT-AdaLA (two stages, one loss). Training from scratch reaches only 31.1 AP.
-
Local spatial mixing matters. Replacing learned positional embeddings with S-SwiGLU improves GTR-S by 1.2 AP at 768² and 1.3 AP at 1024², for only 0.2 GFLOPs (47.6 to 47.8) and 0.5 GFLOPs (83.2 to 83.7) of additional computation respectively.
-
Multi-directional scanning adds a complementary gain. On GTR-L, four-direction scanning achieves 55.5 AP, compared with 55.1 for horizontal bidirectional, 55.0 for vertical bidirectional, and 54.4 for a single direction. Under single-direction scanning, replacing S-SwiGLU with learned positional embeddings drops AP to 45.6.
-
Softmax attention brings no accuracy benefit. Replacing GLA with softmax attention in three of the twelve GTR-L blocks yields 55.4–55.6 AP versus 55.5 AP for pure GLA, but raises median latency from 1.908 to 2.094–2.117 ms and computation from 106 to 119 GFLOPs, with identical 37.2M parameters and 0.19 GB peak memory.
-
Favorable resolution scaling. For GTR-S, going from 640² to 1280² raises AP from 53.6 to 57.0, with a 6.0 AP gain on small objects (36.4 to 42.4). Median latency rises from 1.225 to 2.529 ms and peak memory from 0.096 to 0.249 GB — latency grows only 2.06x despite a 4x increase in image tokens.
-
Kernel-level speedups. The inference-only chunkwise CUDA operator is 2.6x, 4.0x, and 6.4x faster than FLA v0.5.0 at 256, 1.6K, and 16.4K tokens, respectively, under FP16 and CUDA Graph execution on RTX 4090 (a 640x640 input corresponds to 1.6K stride-16 patch tokens).
-
Edge deployment fidelity. TensorRT deployment on DRIVE AGX Thor maintains at least 0.9989 cosine similarity to the PyTorch FP32 reference across all 48 task–scale–batch configurations.
-
Memory and throughput trend. As input resolution increases, GTR-S shows slower growth in peak GPU memory and higher inference throughput than the softmax-attention-based EdgeCrafter-S, alongside RF-DETR-S and YOLO26-S.
Methodology in Plain English
The authors start from gated linear attention (GLA), a recurrent alternative to softmax attention that keeps a running summary state instead of comparing every token to every other token. GTR uses a key-only variant of GLA, so only the key-side state decays over the scan while the value-side decay is fixed at one; a separate data-dependent output gate is applied to the RMS-normalized output. The backbone keeps a single stride-16 patch grid throughout 12 blocks, so there is no hierarchy of shrinking feature maps.
Because a recurrent scan is causal, one pass only sees context from one direction. To get two-dimensional context, each block performs exactly one directional scan — left-to-right, right-to-left, top-to-bottom, or bottom-to-top — cycling through the four directions across depth and restoring spatial order each time. To cover local interactions that the scan order does not guarantee, the authors add Spatial SwiGLU, which inserts a 3x3 depthwise convolution into the value branch of a SwiGLU block, reshaping the value branch back into the 2D patch grid, convolving, and restoring sequence order. GTR uses no explicit positional embeddings.
Training happens in stages. First, a frozen DINOv3 backbone that has been adapted for detection (following EdgeCrafter) acts as teacher. Teacher and student see the same full image, and a learned linear projection maps the student's final patch tokens into the teacher's feature dimension; the only objective is the mean squared L2 distance between the projected student and teacher final representations over patch positions, excluding non-patch tokens. Only the student and the projection are optimized.
For detection, features from blocks 4, 8, and 12 feed a lightweight three-scale projector that builds a feature pyramid at strides 8, 16, and 32, which a query-based decoder then consumes. Detectors are trained 36 epochs on Objects365 followed by 30 epochs on COCO train2017, with "Direct-COCO" variants skipping the Objects365 stage, and evaluated on COCO val2017 at 640x640. For other tasks, the same backbone is paired with task-specific heads and recipes.
Finally, the authors hand-write a chunkwise CUDA operator for inference: chunk summaries are computed in parallel across chunks and heads, only the boundary states are propagated sequentially, and then all chunk outputs are computed independently, with the output kernel fusing within-chunk computation with the boundary-state readout. The operator is specialized to the GTR configuration (FP16, chunk size C = 64, d_k = 32, d_v = 64, zero initial state), while training uses the reference FLA kernels. For DRIVE AGX Thor, fused CUDA kernels for GLA and S-SwiGLU are combined with standard TensorRT operators and graph transformations without changing the computation.
Why This Matters
Impact on research. The paper is a concrete datapoint that homogeneous linear attention can match softmax-based backbones on dense prediction while cutting latency and computation — the ablation showing softmax layers in a hybrid give 55.4–55.6 AP versus 55.5 AP for pure GLA, at higher latency, argues against the common assumption that some softmax mixing is necessary. The distillation result is also notable: a single final-token squared L2 loss beats staged recipes (ViT-Linearizer at 50.0 AP, ViT-AdaLA at 48.2 AP) in this setting. The specialized operator shows that the chunkwise formulation can be re-scheduled for inference, translating linear-attention theory into measured wall-clock speedups.
Real-world applications.
- Automotive perception: the demonstrated DRIVE AGX Thor deployment with 2.282–8.769 ms median batch-one latency targets real-time surround-view detection, segmentation, and depth for driver assistance.
- Edge and embedded vision: slower peak-memory growth and higher throughput as resolution increases make high-resolution processing feasible on resource-constrained devices.
- Robotics and industrial inspection: a single backbone that transfers to detection, instance segmentation, pose, oriented detection, semantic segmentation, and depth reduces the number of distinct architectures to maintain.
- Mixed-resolution deployments: favorable resolution scaling (2.06x latency growth for a 4x increase in tokens) suits applications that must process large or high-resolution imagery.
Industry relevance. The affiliations (Didi International Business Group, Didi Research, Intellindust AI Lab, Institute of Automation of the Chinese Academy of Sciences, HKUST (Guangzhou)) and the explicit TensorRT/DRIVE AGX Thor evaluation show this is aimed at production inference stacks, not only benchmark leaderboards. Baselines are drawn from the same practical space — RF-DETR, YOLO26, and ECDet/EdgeCrafter — and are compared on latency measured under the authors' own protocol (FP16, batch size one, torch.compile, CUDA Graphs, median CUDA-event latency), which is the kind of comparison a deployment team needs.
Future Directions
- Extending the recurrence to temporal data. The paper evaluates single images, including a qualitative multi-view depth visualization from temporally fused predictions on nuScenes, but does not report a recurrent video backbone; carrying the state across frames is a natural extension.
- Scaling and supervision for distillation. The single final-output L2 loss was tested in a detection-specialized DINOv3-to-GLA setting; whether the conclusion holds for larger students, other teachers, or non-detection tasks is reported only as a limitation of the tested setting, not as an answer.
- Broadening kernel and hardware coverage. The custom operator is specialized to FP16, chunk size 64, d_k = 32, d_v = 64, and a zero initial state on RTX 4090 and DRIVE AGX Thor; generalization to other precisions, chunk sizes, and hardware targets is not reported.
- Task and scale coverage beyond the six evaluated. Results for instance segmentation and pose are reported at S and X scales in the main table, with the other scales in the appendix; the paper does not report all scales for every task in the main text, leaving broader cross-scale transfer as an open question.
Target Audience
Researchers and engineers working on efficient vision backbones, linear-attention or state-space vision models, and real-time dense prediction; practitioners deploying perception models to edge or automotive hardware who care about latency, peak memory, and accuracy trade-offs; and readers interested in cross-architecture distillation, since the paper's minimal final-token alignment recipe is a useful contrast to staged distillation methods. Readers without background in attention mechanisms or GPU kernels will find the architecture description accessible but the efficiency analysis and operator details demanding.
Authors’ abstract
Self-attention-based vision backbones perform well on dense prediction, but the quadratic computational cost of global softmax attention limits their efficiency as image resolution increases. We introduce Gated Token Recurrence (GTR), a softmax-free recurrent vision backbone that combines gated linear attention, alternating spatial scan directions, and spatially enhanced SwiGLU blocks. GTR is distilled from a detection-specialized DINOv3 teacher using only final-layer patch-token alignment through a linear projection and squared $\ell_2$ loss, without masked-token prediction or intermediate-layer supervision. With Objects365 detector pre-training, GTR-L achieves 58.9 box AP on COCO \texttt{val2017} with 1.908\,ms median batch-one latency under compiled FP16 execution on an RTX~4090. The same backbone also transfers to instance segmentation, pose estimation, oriented detection, semantic segmentation, and monocular depth estimation. In an isolated kernel benchmark, our specialized chunkwise CUDA operator is $4.0\times$ faster than FLA v0.5.0 at 1.6K tokens on RTX~4090. TensorRT deployment on DRIVE AGX Thor achieves 2.282--8.769\,ms median batch-one latency across the evaluated models. These results show that recurrent token mixing can provide an efficient alternative to global softmax attention for high-resolution dense prediction and edge deployment. Project page: https://intellindust-ai-lab.github.io/projects/GTR/