Research
GAVEL: Graph World Models for Verified and Efficient Long-Horizon LLM Task Planning
Overview Research area: Robotics and embodied AI — specifically long-horizon task planning for robots that use large language models (LLMs) as high-level planners, with formal methods for verifying an
- arXiv
- 2609.19315
- Published
- 2026-09-16
- Authors
- Ruiyang Wang, Hao-Lun Hsu, Swarajh Mehta, Jiwoo Kim, Zhihao Dou, Miroslav Pajic
AI summary
Overview
Research area: Robotics and embodied AI — specifically long-horizon task planning for robots that use large language models (LLMs) as high-level planners, with formal methods for verifying and repairing those plans under partial observability.
Technical level: Advanced. The paper formalizes planning as a constrained optimization problem over belief states, defines graph-valued action preconditions and effects, and uses terminology from belief-space planning, POMDP-style belief updates, and task-and-motion-adjacent abstractions.
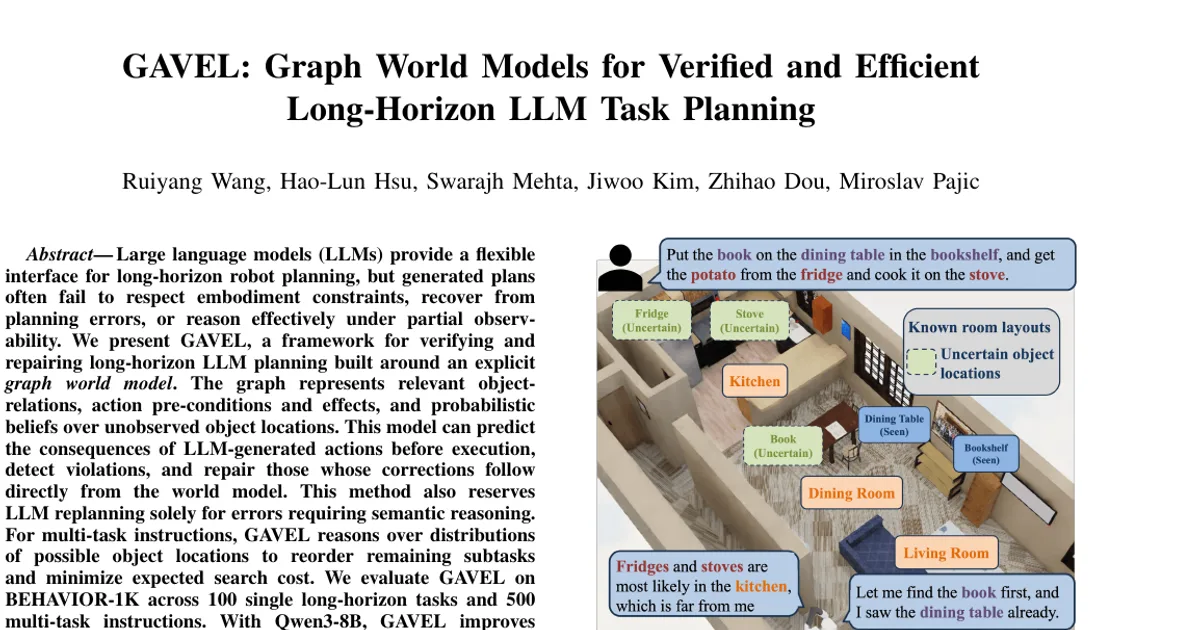
Scope in one sentence: The paper introduces GAVEL, a framework that pairs an LLM planner with an explicit graph world model that simulates, verifies, and repairs generated action plans and reorders multi-task schedules using probabilistic beliefs about where unseen objects are, evaluated on BEHAVIOR-1K.
What This Paper Is About
LLMs can turn natural-language instructions into robot action sequences, but the resulting plans frequently omit prerequisite actions, violate physical/embodiment constraints, or end without reaching the intended goal state — and these failures get worse as the planning horizon grows and as the LLM gets smaller. Existing fixes either send every failure back to the LLM (costly and error-prone for compact models) or use the scene graph purely as a pre-execution checker. GAVEL's goal is to treat the graph as an active world model that predicts action consequences, fixes the failures its own action semantics already imply, and uses stored uncertainty over unobserved object locations to decide which subtask to do next.
Key Contributions
-
A graph world model for verification and repair. It checks LLM plans against action preconditions, goal completion, and trace-level safety constraints. Failures whose correction follows directly from the modeled action semantics are repaired locally; only failures requiring genuine semantic reasoning are passed back to the LLM as structured feedback.
-
An extension to partially observed multi-task execution. GAVEL keeps full distributions over the room locations of unobserved objects (rather than committing to the most likely room), converts them into expected search and navigation costs, and re-optimizes the remaining task order online after each completed task as new observations arrive.
-
A large-scale evaluation on BEHAVIOR-1K covering 100 single long-horizon tasks and 500 multi-task instructions, tested with both compact local LLMs and frontier hosted LLMs, showing improvements in success rate and execution efficiency and that world-model reasoning remains complementary to increasing LLM capability.
Main Findings
-
Compact LLMs are unreliable standalone planners, but GAVEL closes most of the gap on single tasks. With Qwen3-8B, single-task success rises from 41.2% (LLM-only) to 91.8% with GAVEL, and with Qwen3-4B from 21.8% to 88.8%.
-
Graph-derived repair beats feedback-only replanning at a fraction of the LLM cost. The
gavel-basicvariant — which performs only graph repairs and never re-queries the LLM — reaches 67.7% with Qwen3-4B and 76.2% with Qwen3-8B using 1.00 ± 0.0 LLM calls. On Qwen3-4B this exceeds the SayPlan-style feedback baseline's 55.4% by 12.3 points using 1 rather than 3.4 queries; on Qwen3-8B it matches that baseline's 76.4% at the same cost. -
Full GAVEL cuts planning time as well as raising success. Qwen3-4B goes from 27.6 ± 12.0 s under feedback-only replanning to 15.0 ± 11.1 s with GAVEL, at 88.8% success, using 1.7 ± 1.3 LLM calls on average.
-
Multi-task success rises sharply. On 500 multi-task instructions with Qwen3-8B, LLM-only completes 19.9% ± 0.7, SayPlan-style reaches 75.6% ± 2.1, and GAVEL reaches 92.6% ± 1.0. The oracle upper bound is 100.0% ± 0.0.
-
Pure graph-edit planning cannot express semantic goals. The EPoG-style baseline succeeds on 60.2% ± 0.0 of multi-task instructions, and its failures correspond exactly to instructions needing an appliance-induced semantic state (e.g.,
cooked,washed,dried) — for example, "wash the plate" requires inferring that the dishwasher must be run, which a graph-state difference alone cannot specify. -
Distributional beliefs and online reordering reduce travel. Mean distance falls from 82.45 ± 0.23 m (
gavel-map, most-likely room, fixed order) to 79.69 ± 0.45 m (gavel-static, full distribution, fixed order) to 78.01 ± 0.71 m (GAVEL, full distribution with online reordering) — a saving of 4.45 m, or approximately 5.4%. The ordering optimization itself takes only 17 ms per instruction. GAVEL also reduces distance from 83.01 m (SayPlan-style) to 78.01 m on the matched sets both methods succeeded, and cuts planning time by roughly 12 s per instruction. -
Most of GAVEL's remaining multi-task failures are upstream of planning. Of its 38 residual failures on Experiment 2, 21 come from object extraction, only 5 from unexecutable plans, and 9 from unmet goals.
-
Most-likely-room summarization discards real information. The RSN reaches AUC 0.904 and Brier score 0.057, yet across 832 held-out queries the true room ranks first only 47% of the time.
-
The pairwise cost model is accurate enough to avoid enumerating rollouts. It tracks actual driven distance at R² = 0.93 for four-task and R² = 0.89 for five-task instructions, justifying the O(N²) construction instead of rolling out every permutation.
-
Scaling the LLM does not replace the world model. On the same 100-instruction subset, GPT-5.6 Sol and Claude Sonnet 5 without GAVEL reach only 24.6% ± 3.9 and 38.6% ± 2.2, while Qwen3-4B with GAVEL reaches 75.2% ± 2.1 and Qwen3-8B with GAVEL reaches 89.2% ± 1.3. With GAVEL, GPT-5.6 Sol reaches 99.2% ± 0.8 and Claude Sonnet 5 reaches 99.4% ± 0.5.
-
The simulated executor matches the full simulator on validated tasks. All 100 single-task instructions were run in OmniGibson, and success outcomes agreed with the lightweight 2-D executor on every instance; the executor reduces execution time from roughly 17 minutes per plan to about one second, enabling 5,500 evaluations at scale.
(Note: the provided paper text is truncated mid-sentence in the discussion of Experiment 3, so the authors' full concluding remarks on that experiment are not available in the content summarized here.)
Methodology in Plain English
Representing the world as a graph. The robot's environment is a typed scene graph whose nodes are rooms, objects, and the robot itself. Edges encode relations such as near, under, room_connect, room_inside, object_inside, on_top, next_to, and holding; unary flags capture states like open, toggled, cooked, washed, and dried. The paper distinguishes the hidden physical state from the robot's believed graph, which is what the planner actually reasons over.
Giving every action a model. The robot has nine grounded primitives: NavigateTo, Grasp, Release, PlaceOnTop, PlaceInside, Open, Close, ToggleOn, ToggleOff. Each has graph-valued preconditions — proximity, affordance, gripper state, accessibility — and effects that update relations and object states. Because the model can roll an action forward symbolically, GAVEL can predict what a plan will do before anything moves.
Splitting the work between graph and LLM. A single LLM query produces one grounded action sequence per decomposed task. The graph model rolls each sequence forward, checking applicability, goal satisfaction (unmet(g, G) = ∅), and trace-level safety (containers opened must be closed; safety-critical appliances turned on must be turned off). Failures that the action model itself implies — a failed grasp because the robot is too far away, or an object sealed inside a closed container — are repaired locally by inserting the implied actions. A visited-plan set prevents repair loops, and a ranking function keeps the best candidate seen so far, since repairs do not always improve a plan monotonically. Only unresolved failures go back to the LLM, up to a budget T (e.g., 5).
Handling uncertainty. Task understanding uses lightweight LoRA adapters of Qwen3-1.7B, trained on 8,000 synthetic instruction–target pairs with a disjoint 500-instruction validation set, to extract task-relevant objects and goals. Objects whose locations are still unknown get room-location beliefs from a Relational Semantic Network following SEEK: a frozen BAAI/bge-small-en-v1.5 encoder producing 384-dimensional embeddings, then a three-layer MLP (256–128–64, dropout 0.2), trained with weighted binary cross-entropy and calibrated with Platt scaling. The RSN is trained on 11,218 placements across 51 scenes, 197 object categories, and 37 room types, with scenes held out.
Choosing what to do next. For multi-task instructions, GAVEL estimates the expected cost of searching for each unlocalized object by summing over candidate rooms ordered by decreasing belief, weighted by shortest-path distance and an approximate room search cost based on traversable area and sensor coverage width (w_cov = 1.2 m). It builds a first-task cost vector and pairwise transition cost matrix via O(N²) belief-conditioned rollouts, evaluates all permutations (N ≤ 5, so all are enumerated exactly), executes only the first task of the cheapest valid ordering, then updates beliefs from observations and re-optimizes.
Evaluation setup. All 100 single-task instructions were verified in OmniGibson against a lightweight 2-D executor that keeps the original floor plans, object properties, task predicates, and navigation geometry, with A* path planning on traversability maps eroded by the robot base radius and frontier-based exploration using a wedge-shaped camera. The single-task benchmark has 100 long-horizon tasks across 10 scenes with reference plans averaging 12.2 primitives (8–17) and 240 goal predicates total; the multi-task benchmark has 500 instructions with N ∈ {2, 3, 4, 5} independent tasks averaging 18.8 primitives across 4.66 rooms, of which 199 need an appliance-induced semantic state. Results are averaged over five random seeds and reported as mean ± std.
Why This Matters
Impact on research. GAVEL reframes the scene graph from a passive verifier into a world model that carries action semantics and uncertainty. It shows that the right question is not "should the graph or the LLM plan?" but "which failures does each component actually resolve?" — a division-of-labor framing that explains why EPoG-style graph-edit planning fails on semantic procedures and why feedback-only replanning wastes LLM calls on errors the action model already implies. It also demonstrates, against GPT-5.6 Sol and Claude Sonnet 5 on the same 100-instruction subset, that scaling the LLM alone leaves most long-horizon failures in place.
Real-world applications:
- Home and service robotics — fetching, delivering, and appliance operation across multi-room households, where object locations are not known in advance and instructions contain several subtasks.
- Warehouse and logistics robots — retrieving ordered items where the retrieval sites are uncertain and the robot must sequence pickups to minimize travel.
- Edge-deployed assistive robots — devices that must run compact local models rather than call a hosted frontier LLM, which is precisely where LLM-only planning succeeds on only 2.4% to 23.6% of instructions without GAVEL.
- Safety-constrained automation — settings where trace-level constraints matter, such as closing opened containers and switching off safety-critical appliances before a plan terminates.
Industry relevance. The cost profile matters as much as the success rate: GAVEL reduces LLM calls per single task to 1.5–1.7 on average versus 2.7–3.4 for feedback-only replanning, cuts planning time from 27.6 s to 15.0 s with Qwen3-4B, and lowers planning time by roughly 12 s per multi-task instruction relative to the SayPlan-style baseline. The 2-D executor reduces per-plan evaluation time from roughly 17 minutes to about one second, which is what made 5,500 evaluations feasible in the first place — a practical pattern for validating embodied planners at scale.
Future Directions
-
Reducing object-extraction errors. 21 of GAVEL's 38 residual multi-task failures trace back to object extraction, not to planning, repair, or ordering — an upstream bottleneck that improving the world model alone would not fix.
-
Uncertainty-aware task dependencies. The framework assumes multi-task instructions whose goal-object sets are disjoint, so every ordering is admissible and order affects cost rather than feasibility. Extending belief-aware ordering to tasks that share objects or interact through auxiliary state changes is an open question.
-
Closing the residual gap to the oracle. The oracle reaches 100.0% ± 0.0 success at 56.17 m, compared with GAVEL's 92.6% ± 1.0 at 78.01 m; 5 of GAVEL's remaining failures are unexecutable plans and 9 are unmet goals, indicating room for stronger verification or better prompting.
-
Scaling the belief and cost machinery. The exact permutation enumeration relies on N ≤ 5 in these experiments; whether the same approach holds for substantially larger task sets, and whether the O(N²) cost-model approximation (R² = 0.93 for four-task and 0.89 for five-task instructions) degrades gracefully, is not established here.
Target Audience
Robotics and embodied-AI researchers working on LLM-based task planning, neuro-symbolic integration, and planning under partial observability; engineers deploying language-model planners on resource-constrained or edge hardware; and readers already familiar with scene graphs, PDDL-style action preconditions and effects, and belief-space planning who want a concrete, quantitatively evaluated example of treating a graph as a full world model rather than a validator. Beginners would find the formal problem definition and belief-update notation demanding, though the experimental framing in Sections V-E through V-G is readable on its own.
Authors’ abstract
Large language models (LLMs) provide a flexible interface for long-horizon robot planning, but generated plans often fail to respect embodiment constraints, recover from planning errors, or reason effectively under partial observability. We present GAVEL, a framework for verifying and repairing long-horizon LLM planning built around an explicit graph world model. The graph represents relevant object-relations, action pre-conditions and effects, and probabilistic beliefs over unobserved object locations. This model can predict the consequences of LLM-generated actions before execution, detect violations, and repair those whose corrections follow directly from the world model. This method also reserves LLM replanning solely for errors requiring semantic reasoning. For multi-task instructions, GAVEL reasons over distributions of possible object locations to reorder remaining subtasks and minimize expected search cost. We evaluate GAVEL on BEHAVIOR-1K across 100 single long-horizon tasks and 500 multi-task instructions. With Qwen3-8B, GAVEL improves single-task success from 41.2% to 91.8% and multi-task success from 19.9% to 92.6%. Distributional belief reasoning also reduces travel distance by approximately 5.4% compared with a static variant. These improvements show that an explicit graph world model harness can substantially improve the reliability and efficiency of long-horizon embodied planning across compact and frontier hosted LLM capabilities.