Research
FineTec: Fine-Grained Action Recognition Under Temporal Corruption via Skeleton Decomposition and Sequence Completion
Overview Research area: Computer vision — skeleton-based human action recognition, specifically fine-grained action recognition (FAR) on temporally corrupted skeleton sequences, using graph convolutio
- arXiv
- 2512.25067
- Published
- 2025-12-31
- Authors
- Dian Shao, Mingfei Shi, Like Liu
AI summary
Overview
Research area: Computer vision — skeleton-based human action recognition, specifically fine-grained action recognition (FAR) on temporally corrupted skeleton sequences, using graph convolutional networks (GCNs), in-context learning, and Lagrangian rigid-body dynamics.
Technical level: Advanced. The paper assumes familiarity with GCN-based skeleton action recognition (ST-GCN, CTRGCN), in-context learning, and Lagrangian mechanics.
Scope: The paper proposes FineTec, a three-module framework (context-aware sequence completion, skeleton-based spatial decomposition, physics-driven acceleration modeling) that restores corrupted skeleton data and improves fine-grained action recognition, plus a new 288-class dataset, Gym288-skeleton.
What This Paper Is About
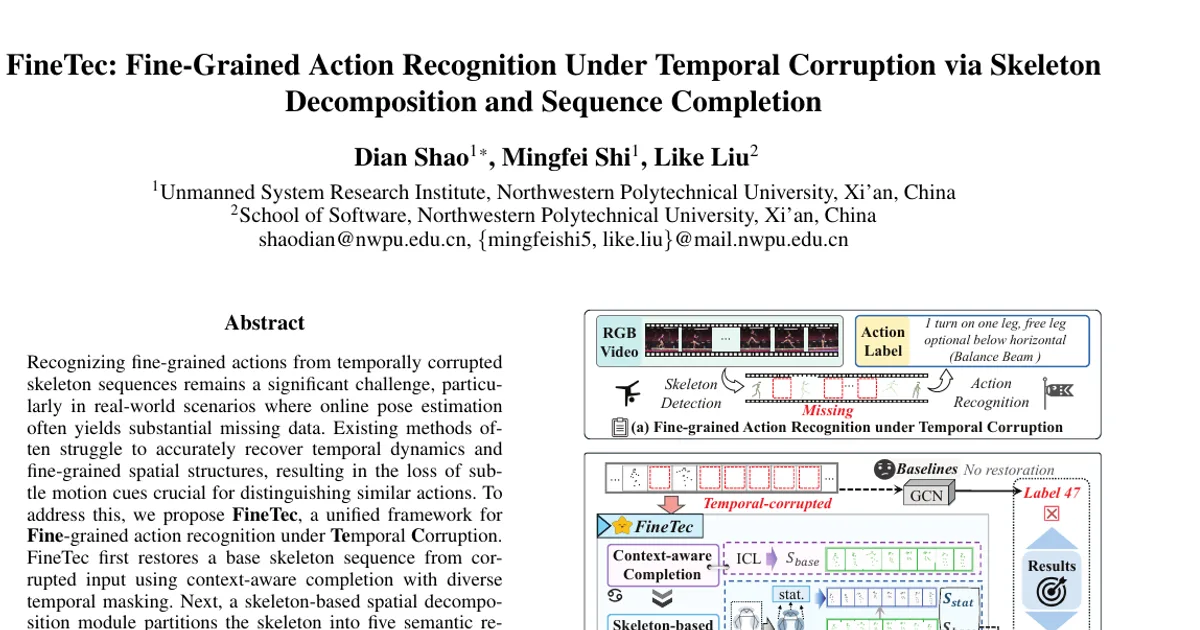
Skeleton sequences captured by online pose estimation frequently lose frames — the paper cites dropping rates reaching up to 69.6% during rapid motion (Zheng et al. 2024) — and this loss of temporal continuity disproportionately damages fine-grained actions, which depend on subtle motion cues. Existing skeleton recognition methods are mostly trained on clean, offline-annotated sequences and model mainly joint displacement, so they neither recover missing frames nor exploit the physical structure of human motion. FineTec addresses both gaps by first completing the corrupted sequence, then decomposing and augmenting it by anatomical region and motion level, and finally re-estimating joint accelerations from Lagrangian dynamics before classification.
Key Contributions
- A formalized benchmark for fine-grained action recognition under temporal corruption. The authors define the task, simulate corruption by randomly dropping 25% (minor), 50% (moderate), or 75% (severe) of frames, and construct Gym288-skeleton, a large-scale dataset extending the open-source Gym99 to 288 fine-grained action classes.
- The FineTec framework, combining three modules: a Context-aware Sequence Completion module, a Skeleton-based Spatial Decomposition module guided by biological priors, and a Physics-driven Acceleration Modeling module based on Lagrangian dynamics.
- Dataset construction pipeline for Gym288-skeleton, built by manually annotating roughly 11,000 initial-frame bounding boxes, applying OSTrack for athlete tracking, and performing pose estimation inside the tracked boxes.
- Extensive evaluation on both fine-grained (Gym99-skeleton, Gym288-skeleton) and coarse-grained (NTU-60, NTU-120, and UCF101 in the appendix) benchmarks under multiple corruption levels.
Main Findings
- Fine-grained recognition gains: FineTec achieves top-1 accuracies of 89.1% on Gym99-severe and 78.1% on Gym288-severe, the best of all compared methods under every reported corruption level in Table 1.
- Mean class accuracy on Gym288-severe: FineTec improves on the best baseline by 13% and outperforms the latest compared work (Sparse, Xie et al. 2025) by 50% in mean class accuracy — a metric included because of significant class imbalance in Gym288.
- Coarse-grained gains: Under severe corruption, FineTec improves top-1 accuracy by 1.3% on NTU-60-xsub and 1.7% on NTU-120-xsub over competing baselines.
- Skeleton restoration: FineTec attains the lowest MPJPE at all corruption levels. Relative to the strongest competing method (SiC-Dyna), the paper reports MPJPE reductions of 43.6% (minor), 27.4% (moderate), and 23.4% (severe). (Note: this sentence in the paper names the method "MaskICL," which appears to refer to the same proposed completion component.) The method also achieves the best N-MPJPE and MPJVE across all settings.
- Ablation — all three modules matter: On Gym288-skeleton, the full model reaches 0.815 / 0.797 / 0.781 (minor / moderate / severe). Removing completion drops severe performance to 0.751; removing spatial decomposition gives 0.787 / 0.780 / 0.770; removing physics-driven modeling gives 0.789 / 0.776 / 0.775.
- Ablation — dynamic and static variants are complementary: Using only the dynamic variant (S_dyna) gives 0.790 / 0.774, only the static variant (S_stat) gives 0.786 / 0.764, while combining both gives 0.797 / 0.781.
- Fusion strategy: Cross-attention fusion beats MLP-based integration, both at moderate (0.797 vs. 0.779) and severe (0.781 vs. 0.771) corruption.
- Sequence completion helps recognition: Comparing with Interpolation and Duplication baselines, FineTec yields the highest top-1 accuracy at all corruption levels on both datasets. In Figure 4, FineTec is reported at 0.919 / 0.906 / 0.885 on Gym99 and 0.815 / 0.797 / 0.778 on Gym288 across minor, moderate, and severe settings.
- Robustness to noisy inputs: Under spatial Gaussian noise and temporal frame dropping at two severity levels, FineTec remains accurate; the no-perturbation reference is 0.926 / 0.995 top-1/top-5 on Gym99-minor and 0.804 / 0.924 on Gym288-severe.
- UCF101 results (appendix): FineTec reaches top-1 / top-5 of 0.652 / 0.861 (minor), 0.638 / 0.859 (moderate), and 0.621 / 0.847 (severe), compared with ST-GCN's 0.648 / 0.852, 0.632 / 0.858, 0.582 / 0.844 and AAGCN's 0.634 / 0.851, 0.636 / 0.861, 0.638 / 0.843.
Methodology in Plain English
FineTec processes a corrupted 2D skeleton sequence (T frames, K = 17 joints) in three stages.
- Context-aware sequence completion. The system learns by analogy. A bank of Human3.6M 2D skeletons provides an average prior sequence. For training, sequences are sampled from the bank and corrupted by one of five masking strategies — random, pattern-based, left-side, right-side, and middle masking — which simulate sporadic loss, structured gaps, delayed capture start, early termination, and mid-action occlusion. The clean sequence and its masked counterpart form a "prompt" pair demonstrating recovery; the actual corrupted input paired with the prior forms the "query" pair. Lightweight spatial and temporal MLPs (48-layer S-MLPs and T-MLPs in the implementation) then approximately reconstruct a base sequence S_base.
- Skeleton-based spatial decomposition. S_base is split into five anatomical regions: head (G0), left arm (G1), right arm (G2), left leg (G3), and right leg (G4). Each joint's average frame-wise displacement is computed, and regional motion intensity is the mean displacement within a region. The two most active regions are treated as dynamic and the other three as static. Dynamic regions receive strong spatio-temporal perturbation, static regions only weak spatial perturbation, producing S_dyna and S_stat, which are fused with S_base into S_pred.
- Physics-driven acceleration modeling. The Lagrangian equation M(S)·S̈ + C(S,Ṡ)·Ṡ + g(S) = τ is rewritten to isolate acceleration, with the inverse inertia matrix, Coriolis-like term, gravity term, and driving force each estimated by separate neural networks from global and local features of joint positions and velocities. Symmetry is enforced by estimating only upper-triangular matrix parts. This physics-derived acceleration is fused with a data-driven pseudo-acceleration from second-order finite differences to give the final acceleration feature.
- Recognition. The fused position sequence and fused acceleration sequence are combined via cross-attention and fed to a GCN with a classification head. Training uses two stages: pre-training the completion module (MSE losses on both prompt and query pairs), then training the rest with the completion module frozen, using cross-entropy plus a weighted acceleration-consistency MSE loss. Batch size is 64 for FineTec training (max 150 epochs), while completion pre-training uses batch size 256, Adam, learning rate cycling between 1×10⁻⁵ and 5×10⁻⁸ over 40,000 iterations, weight decay 1×10⁻⁴, and a fixed seed of 304. The Gym288-skeleton training stage ran on 4 NVIDIA 4090 GPUs within 5 hours. NTU inputs use 100-frame sequences; fine-grained inputs use 16-frame clips represented as 43-dimensional per-frame vectors (34 skeletal features, 1 mask indicator, 8 positional encodings).
Why This Matters
Impact on research. FineTec reframes skeleton-based action recognition as a problem of recovering temporal continuity rather than only classifying clean inputs, and pushes physics-informed modeling into the fine-grained regime. It also supplies a harder benchmark (Gym288-skeleton, 288 classes) for measuring robustness to frame dropping, and reports mean class accuracy to expose performance under class imbalance.
Real-world applications (as motivated by the paper's setting):
- Online pose estimation in sports analytics, particularly gymnastics, where actions differ by small temporal and semantic details (for example, "salto forward stretched with 2 twists" or "pike sole circle backward with 0.5 turn to handstand").
- Real-time coaching and technique scoring where rapid motion causes frequent dropped frames.
- Surveillance or monitoring systems that must operate on fragmented skeleton streams from imperfect detectors.
- Any downstream system taking skeleton input from an online pose estimator, where missing frames are routine rather than exceptional.
Industry relevance. The framework targets the practical gap between offline-annotated training data and online detection artifacts, which is exactly where deployed skeleton pipelines break. Improvements under 75% frame loss matter directly for latency-constrained or bandwidth-constrained deployments, and the reported training cost (4 GPUs, under 5 hours for Gym288-skeleton fine-tuning) is modest by modern standards.
Future Directions
- Replacing the fixed skeleton bank. The authors note that sequence completion currently relies on a fixed skeleton bank, and suggest more adaptive, data-driven approaches as future work.
- Replacing manually defined subgroups. The dynamic/static partition is manually defined and could also be made data-driven.
- Extending acceleration modeling beyond the joint level. The paper proposes extending joint-level acceleration modeling to subgroup or limb-level dynamics to better capture human motion.
- Broadening scope. The conclusion lists expansion to multi-modal contexts and enhanced biomechanical modeling as future directions.
Target Audience
Researchers and graduate students working on skeleton-based action recognition, human motion analysis, and physics-informed computer vision; practitioners building pose-driven sports analytics or monitoring systems who need robustness to dropped frames; and dataset/benchmark builders interested in fine-grained, class-imbalanced action data. Readers without a background in GCNs, in-context learning, or Lagrangian mechanics will find the methodology section demanding, though the three-module pipeline is conceptually accessible.
Note on completeness: the provided paper content is truncated after the "Appendix C Gym288-skeleton Datase[t]" heading, so the detailed dataset construction analysis and remaining appendix material referenced in the text are not available in the supplied content and are not summarized here.
Authors’ abstract
Recognizing fine-grained actions from temporally corrupted skeleton sequences remains a significant challenge, particularly in real-world scenarios where online pose estimation often yields substantial missing data. Existing methods often struggle to accurately recover temporal dynamics and fine-grained spatial structures, resulting in the loss of subtle motion cues crucial for distinguishing similar actions. To address this, we propose FineTec, a unified framework for Fine-grained action recognition under Temporal Corruption. FineTec first restores a base skeleton sequence from corrupted input using context-aware completion with diverse temporal masking. Next, a skeleton-based spatial decomposition module partitions the skeleton into five semantic regions, further divides them into dynamic and static subgroups based on motion variance, and generates two augmented skeleton sequences via targeted perturbation. These, along with the base sequence, are then processed by a physics-driven estimation module, which utilizes Lagrangian dynamics to estimate joint accelerations. Finally, both the fused skeleton position sequence and the fused acceleration sequence are jointly fed into a GCN-based action recognition head. Extensive experiments on both coarse-grained (NTU-60, NTU-120) and fine-grained (Gym99, Gym288) benchmarks show that FineTec significantly outperforms previous methods under various levels of temporal corruption. Specifically, FineTec achieves top-1 accuracies of 89.1% and 78.1% on the challenging Gym99-severe and Gym288-severe settings, respectively, demonstrating its robustness and generalizability. Code and datasets could be found at https://smartdianlab.github.io/projects-FineTec/.