Research
EmbodiedWorld-200K: Toward Embodied World Agents via Embodied-Planning Dataset and Interactive World Models
Overview Research area: Embodied AI — vision–language–action (VLA) models, open-world navigation planning, datasets and benchmarks, and video world models used as training environments. Technical leve
- arXiv
- 2610.25959
- Published
- 2026-10-19
- Authors
- X. Feng, J. Tang, Z. Lin, L. Chen, S. Shao, Q. Lu, K. Huang
AI summary
Overview
Research area: Embodied AI — vision–language–action (VLA) models, open-world navigation planning, datasets and benchmarks, and video world models used as training environments.
Technical level: Intermediate. Readers should be comfortable with vision–language models, supervised fine-tuning, reinforcement learning from preferences (DPO), and the idea of a generative video model acting as a simulator.
Scope (one sentence): This paper introduces a 200K-sample open-world embodied-planning dataset built from 3D gameplay video, defines a navigation-planning task with four evaluation metrics, and proposes a two-stage training recipe — offline supervised pretraining followed by interactive RL post-training inside a video world model — for a baseline agent built on Qwen3-VL-4B.
What This Paper Is About
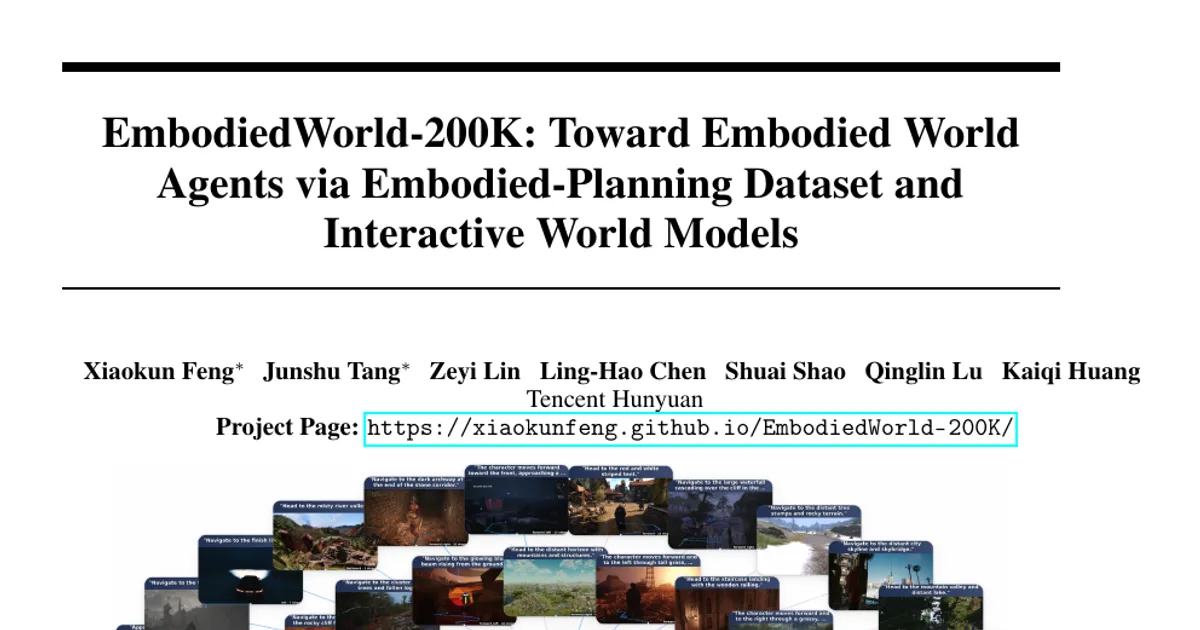
Most embodied agents are built for one task in one scene (a single indoor simulator, a single robot, a single game) and transfer poorly elsewhere. The authors argue that the field lacks both a large, diverse dataset with layered annotations and a practical, reproducible training recipe for what they call Embodied World Agents (EWAs) — agents that can understand many different 3D visual environments and act in them. They address this gap by instantiating EWAs as open-world embodied navigation-planning, releasing a dataset of over 200K samples derived from 150 3D open-world games, and showing that offline pretraining on it plus interactive post-training inside a video world model improves planning, including on scenes outside the training distribution.
Key Contributions
-
A named research direction. The paper formalizes Embodied World Agents — general-purpose agents that perceive, reason, and act across diverse open-world 3D environments — and frames the missing infrastructure (data plus training recipe) as the main obstacle.
-
EmbodiedWorld-200K, a large multi-level dataset. Over 200K samples drawn from 150 3D open-world games, each a triplet of an initial visual observation, a natural-language navigation instruction, and an action sequence, annotated at levels from low-level camera-motion trajectories up to high-level semantic goals, together with a unified evaluation split and task-specific metrics.
-
A two-stage training framework and baseline. Offline supervised pretraining of Qwen3-VL-4B on the dataset (turning the VLLM into a VLA model that emits actions as text), followed by interactive RL post-training that uses a video world model as a low-cost environment proxy, with VQA-based rewards and DPO.
-
Empirical validation and released artifacts. The authors report that pretraining improves all four metrics over the zero-shot backbone, that the model beats every external baseline they tested on three of four metrics, and that world-model-based DPO improves adaptation on an out-of-distribution target scene (GTA5). Dataset, baseline checkpoints, and training/evaluation code are released.
Main Findings
-
Offline pretraining gives consistent gains. Stage-I supervised fine-tuning of Qwen3-VL-4B improves over its own zero-shot version on every metric: Token Match (TM) +7.1 (54.9 → 62.0), Direction Accuracy (DirAcc) +1.9 (70.1 → 72.0), nDTW +16.5 (67.1 → 83.6), and Navigation Error (NE) −16.1 (51.7 → 35.6).
-
The gains are not simply borrowed from a stronger general model. Against external baselines evaluated with the same split, metric toolkit, and prompt, the fine-tuned model leads on TM (+9.2 over the strongest competitor), nDTW (+20.2), and NE (−19.1), and matches the best DirAcc (72.0 vs. 72.4). Gemini-3.5 holds the best DirAcc (72.4) but trails clearly on trajectory-level metrics, which the authors read as evidence that strong multimodal understanding infers coarse heading but not the goal-directed action sequence.
-
The benchmark is discriminative, not saturated. Baseline scores span TM 45.3–54.9, nDTW 25.9–67.1, and NE 51.7–114.7, leaving visible headroom.
-
The task genuinely requires language grounding. NitroGen, a game foundation model that predicts gamepad actions from pixels without language conditioning, records the lowest DirAcc (39.8, close to chance) — reported as an instruction-free lower bound.
-
VLN models adapted to the W/A/S/D format underperform. Uni-NaVid reaches TM 47.9 / DirAcc 61.4 / nDTW 30.9 / NE 100.6; StreamVLN reaches 47.2 / 61.5 / 25.9 / 114.7.
-
World-model-based DPO improves out-of-distribution adaptation on GTA5. After post-training inside LingBot-World-Fast, TM rises from 65.4 to 75.0, nDTW from 66.1 to 92.7, and NE drops from 48.9 to 13.4; DirAcc dips slightly from 84.4 to 82.8.
-
Starting the RL stage from a capable actor matters. The authors initialize the actor with the Stage-I SFT model rather than the base VLLM, reasoning that base-model rollouts are too noisy to form informative preference pairs.
-
Qualitative generalization to unseen visuals. Figure 7 shows out-of-distribution examples whose initial observations are synthesized by an image-generation model, before and after Stage-I pretraining.
Methodology in Plain English
Building the data. The authors start from OGameData, a public repository of gameplay video spanning more than 150 next-generation 3D games with over one million clips. Since it was collected for video generation, not agent research, they filter it to keep only clips with clear, continuous embodied action — dropping cutscenes and menu navigation — and focus on open-world exploration, action-adventure, first-person shooter, puzzle-solving, and simulation games. This yields 260K gameplay trajectories (~708 hours).
Turning video into agent training examples. Three steps:
- Segmentation. Camera motion is recovered from each clip with VIPE to get a 6-DoF pose trajectory. The clip is cut whenever motion departs from the running principal direction by more than 90° for at least 3 consecutive frames (after smoothing with a window of 5). Candidates are dropped if their net-displacement-to-path-length ratio falls below 0.3, if curvature variance exceeds 1.5, or if they are shorter than 60 frames. This produces 215K navigation-coherent segments (NCSs), each with a single dominant direction; the first frame becomes the observation.
- Action quantization. Motion is discretized into a game-agnostic W/A/S/D vocabulary — W/A/S/D for forward/left/backward/right translation and W/A/S/D for pitch-up/yaw-left/pitch-down/yaw-right rotation, with N for no motion. Units are calibrated from dataset-level statistics; the released version uses a translation unit of 0.05 and a rotation unit of 5°. Each token thus corresponds to roughly fixed physical motion, giving a mean sequence length of 9.98.
- Instruction annotation. Qwen3.5-27B is prompted with uniformly sampled frames plus a direction descriptor to write one of two instruction types: a Detailed Movement Instruction (direction cues plus visible target) or a High-Level Goal-Navigation Instruction (destination only, no movement cue). The latter is harder and only produced when a grounding–verification step confirms the target is uniquely identifiable; otherwise the pipeline falls back to the detailed instruction.
Evaluating. Disjoint train/eval splits with four metrics: Token Match (per-step keyset-F1 averaged over translation and rotation streams), Direction Accuracy (averaged over four axes), nDTW (normalized dynamic time warping over reconstructed 3D trajectories, averaged over τ ∈ {0.5, 1.0, 2.0}), and Navigation Error (terminal xy displacement in translation units).
Training. Stage I fine-tunes Qwen3-VL-4B with LoRA for 2 epochs using cross-entropy on action tokens; the model takes the initial observation and instruction through a system prompt and emits the whole action sequence as a single JSON object, deliberately avoiding separate action heads so the action vocabulary stays in the model's native text space. Stage II rolls the SFT actor out inside the LingBot-World-Fast video world model on GTA5, a game excluded from training. During rollouts a VLLM writes task instructions conditioned on the evolving scene, a VQA-based reward judges whether the instruction was fulfilled, and the resulting preferred/rejected trajectory pairs are used for DPO.
Why This Matters
The paper's distinctive move is to treat infrastructure as the contribution: a large, multi-level, cross-game dataset plus a reproducible two-stage recipe, rather than a new architecture or RL algorithm. It also demonstrates a practical way around one of embodied AI's costliest bottlenecks — instead of building interactive simulators for every environment, it uses a generative video model as a stand-in environment for closed-loop post-training.
Real-world applications:
- Robot navigation and mobile manipulation. The instruction-to-action-sequence formulation and the offline-then-interactive recipe echo the standard robotics pattern of broad pretraining followed by platform-specific fine-tuning.
- Cheap adaptation to new deployment environments. World-model proxies could let teams specialize a policy to a new building, warehouse, or terrain without large-scale real trajectory collection.
- Simulation and game AI. Agents that read a scene and follow natural-language goals generalize to NPC behavior, playtesting, and content validation across many titles.
- Data engine for embodied learning. The annotation pipeline (segmentation, action quantization, VLM-written instructions) is a template for converting existing video into labeled agent data at scale.
Industry relevance: the work comes from Tencent Hunyuan and connects three commercially active threads — VLA models, large-scale multimodal data curation, and generative world models — while releasing checkpoints and code so that others can build on the baseline rather than re-derive it.
Future Directions
- Beyond navigation. The current instantiation covers only translation and view rotation because those actions are universal across open worlds and natively supported by today's video world models. Extending to object interaction, manipulation, or longer-horizon tasks is left open.
- How faithful are world-model proxies? Stage II relies on a video world model as an environment stand-in; the paper does not characterize how proxy inaccuracies propagate into the learned policy, or how well gains transfer back to the real environment.
- Scaling the interactive stage. Stage II is demonstrated on a single target environment (GTA5) with a single video world model (LingBot-World-Fast). Whether the recipe holds across many target scenes, and what the compute/quality trade-offs are, remains to be tested.
- Richer and harder instruction types. The high-level goal-navigation instruction can only be produced when the target is uniquely identifiable, so a large share of samples fall back to detailed movement descriptions. Automating harder, more compositional goals — and measuring how much each annotation level contributes — is a natural next step.
- Where does the DirAcc trade-off come from? DPO improves TM, nDTW, and NE on GTA5 but slightly lowers DirAcc; understanding this trade-off is an open question the paper does not resolve.
Target Audience
Researchers and engineers working on embodied AI, vision–language–action models, and navigation; teams curating large multimodal datasets from video; and practitioners interested in using generative world models as training environments. It is also useful for readers who want a concrete, reproducible baseline and benchmark rather than a new architecture, and for graduate students entering the field who need a clear statement of the data-and-recipe gap in open-world embodied agents.
Authors’ abstract
Building embodied agents that can perceive, reason, and act across diverse 3D worlds is a central research direction toward artificial general intelligence. Yet most existing work remains confined to specific tasks in a single scene and transfers poorly to new environments, leaving general embodied agents for open-world settings under-explored. We refer to such agents as Embodied World Agents (EWAs), whose defining property is the ability to understand diverse visual environments and execute general actions in open-world conditions. To advance EWA research, we study open-world embodied navigation-planning and release EmbodiedWorld-200K, a large-scale dataset of over 200K samples spanning diverse scenes. Each example is equipped with multi-level annotations, ranging from low-level camera-motion trajectories to high-level semantic instructions. The dataset also provides unified evaluation splits and task-specific metrics, supporting offline pretraining and fair evaluation of EWAs. Beyond offline supervision, a defining characteristic of an EWA is its interaction with the environment; training solely on offline data is therefore insufficient, especially for generalizing to scenes not covered in the training distribution. Building dedicated real interactive environments, however, is often prohibitively expensive. To address this, we propose a novel training scheme that employs a video world model as a low-cost environment proxy and performs interactive reinforcement-learning (RL) post-training of the EWA within it. Empirically, pretraining on EmbodiedWorld-200K substantially improves the open-world embodied planning ability of the EWA, and further RL post-training inside a world model yields clear gains on out-of-distribution scenes. The dataset, baseline checkpoints, and training and evaluation code are available at https://xiaokunfeng.github.io/EmbodiedWorld-200K/.