Research
Discover, Segment, and Select: A Progressive Mechanism for Zero-shot Camouflaged Object Segmentation
Overview Research area: Computer vision — specifically zero-shot Camouflaged Object Segmentation (COS), which combines multimodal large language models (MLLMs), the Segment Anything Model (SAM/SAM2),
- arXiv
- 2602.19944
- Published
- 2026-02-23
- Authors
- Yilong Yang, Jianxin Tian, Shengchuan Zhang, Liujuan Cao
AI summary
Overview
Research area: Computer vision — specifically zero-shot Camouflaged Object Segmentation (COS), which combines multimodal large language models (MLLMs), the Segment Anything Model (SAM/SAM2), and self-supervised visual features (DINOv2).
Technical level: Advanced. The paper assumes familiarity with prompt-based segmentation, feature clustering, and MLLM reasoning pipelines, though its core idea is expressible in plain terms.
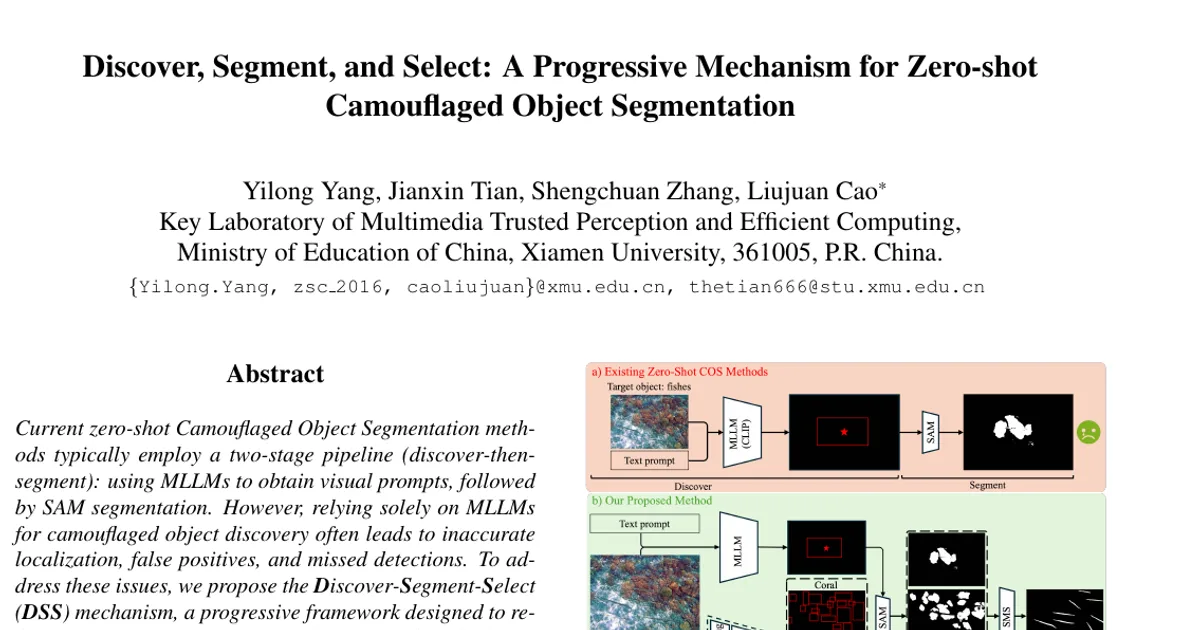
Scope (one sentence): The paper proposes a training-free, three-stage pipeline — Discover, Segment, Select (DSS) — that improves zero-shot camouflaged object segmentation by replacing MLLM-only localization with clustered visual feature proposals plus a reasoning-based final mask selection.
What This Paper Is About
Existing zero-shot COS methods follow a two-stage "discover-then-segment" recipe: an MLLM (sometimes aided by a vision-language model such as CLIP) produces visual prompts like bounding boxes or points, which are then fed into SAM to produce masks. The authors argue this is fragile, because MLLMs rely on high-level semantics rather than fine-grained cues, producing inaccurate localization, false positives, missed detections, and especially poor results in multi-instance scenes. Their goal is to add two more stages around this pipeline — one that generates proposals from intrinsic visual structure, and one that reasons over the resulting candidate masks — so that segmentation quality improves without any training or supervision.
Key Contributions
- A Discover, Segment, Select (DSS) pipeline that augments MLLM-based discovery with visual feature clustering and adds a final mask-selection stage to pick the optimal segmentation from multiple candidates.
- A Part Composition (PC) module that refines initial clustering results by iteratively enforcing intra-cluster compactness and inter-cluster separability in feature space, improving coherence and completeness for complex camouflaged objects.
- A Similarity-based Box Generation (SBG) module that derives bounding-box prompts from self-similarity maps between foreground regions and all image patches, designed to prevent the omission of instances in multi-instance scenes.
- A Semantic-driven Mask Selection (SMS) module that uses an MLLM to evaluate candidate masks through progressive pairwise comparisons, ordered by a heuristic score, to select the final mask.
Main Findings
- Zero-shot state of the art across all four benchmarks: DSS reports Fβw / M / Sα / Eφ of .766 / .078 / .808 / .870 on CAMO (250 images), .870 / .031 / .891 / .940 on NC4K (4,121 images), .849 / .022 / .887 / .942 on COD10K (2,016 in the table header; the text body states 2,026 images), and .848 / .034 / .883 / .926 on CHAMELEON (87 in the table header; the text body states 76 images). The paper states DSS outperforms all existing zero-shot methods across every dataset and metric.
- Better than fully-unsupervised methods without any training: The authors state DSS surpasses all unsupervised methods in the comparison table despite requiring no training, and narrows the gap to fully-supervised methods.
- Smallest degradation as instance count grows: On subsets containing three or more camouflaged objects, DSS shows the minimal performance drop relative to the single-instance subset, while comparison methods degrade substantially.
- SBG beats boxes from binary masks: On the "3+" subsets, similarity-map boxes give Fβw / M / Sα / Eφ of .818 / .054 / .839 / .917 versus .795 / .058 / .812 / .897 on NC4K, and .745 / .026 / .821 / .911 versus .723 / .034 / .794 / .881 on COD10K.
- Each stage contributes, and combining them is best: In the ablation table, Leiden clustering plus PC plus including the VLOS mask (row 7) gives .892 on COD10K, .888 on CHAMELEON, and .823 on CAMO — the best of all seven configurations.
- Mask selection is effective but leaves headroom: DSS scores .737 (CAMO), .869 (NC4K), .871 (COD10K), .852 (CHAMELEON) versus the VLOS baseline's .708 / .845 / .850 / .791, but remains below the "Ideal Seg." upper bound of .823 / .895 / .892 / .888.
- Pairwise, ascending-order selection is the best SMS strategy: Selection accuracy is 74.40% on CAMO and 73.68% on CHAMELEON at 30.59 s per image, versus 40.24% / 36.84% for top-K single-pass, 54.00% / 59.21% for random-order pairwise, 50.80% / 43.42% for descending-order pairwise, and 68.80% / 71.05% for pure heuristic rules at 1.14 s per image. Single-pass selection over all masks fails with out-of-memory (OOM) errors.
- Efficiency trade-off: DSS takes 41.96 s per image in total (7.74 s FOD, 3.63 s mask generation, 30.59 s SMS) and 17.90 GB of GPU memory, versus ProMaC at 130.49 s and 32.85 GB and RDVP-MSD at 18.05 s and 31.51 GB. Total inference time is 2.32 times RDVP-MSD, with the SMS module accounting for 72.9% of the time and FOD for 14.3%.
Methodology in Plain English
The method runs three sequential stages on each image, with no training at any point.
Discover. Instead of asking an MLLM alone where the camouflaged object is, the authors first extract patch-level features with a self-supervised encoder (DINOv2), reduce their dimensionality to 16 with PCA, and group them with the Leiden clustering algorithm (which picks the number of clusters automatically, unlike K-means with a fixed K). Because clustering can split one animal into several parts, a Part Composition module iteratively adjusts each patch's foreground probability based on its distance to foreground and background feature centroids, stopping when the change in a feature-coherence energy falls below a threshold. The resulting refined masks are turned into bounding boxes through self-similarity maps: for each mask, the foreground centroid is compared against every image patch, and the resulting affinity map is thresholded to produce a box. Highly correlated maps (Pearson correlation above a threshold) are merged by averaging to remove redundant proposals. Ablation shows the similarity maps produce more complete boxes than boxes taken directly from the binary masks.
Segment. The boxes are fed to SAM2 (ViT-L) to produce a set of candidate masks. The MLLM's own localization result (the VLOS baseline mask) is also included as a candidate.
Select. Each candidate receives a score combining its correlation with its similarity map and its boundary contact rate (camouflaged objects rarely touch the image border). The top-K masks are kept, and the MLLM is asked — pairwise, starting from the two lowest-scoring masks and working upward — which of two masked image crops better matches the camouflaged object in the original image. Each winner advances to face the next-higher-scoring mask, for K−1 iterations.
Hyperparameters were tuned on a validation subset of 1,000 images randomly sampled from the COD10K and CAMO training sets, using a single NVIDIA GeForce RTX 3090 GPU with 24 GB of memory, with QWen2.5-VL-Instruct as the MLLM. The reported settings are Leiden resolution r = 0.5, energy change threshold ε = 1.0, correlation de-duplication threshold τ = 0.95, and K = 5.
Why This Matters
Impact on research: The paper challenges the assumption that MLLM localization is the right "discovery" mechanism for zero-shot dense prediction, and shows that intrinsic visual features still carry discriminatory signal that language-guided proposals overlook. It also introduces a selection stage that reframes the MLLM as an evaluator rather than a localizer — a pattern potentially transferable to other prompt-based segmentation tasks.
Real-world applications (as listed by the authors):
- Medical diagnosis, where lesions can be low-contrast against surrounding tissue.
- Agricultural monitoring, for example detecting pests or plants that blend into foliage.
- Autonomous driving, where pedestrians or obstacles may be visually ambiguous in a scene.
- Military surveillance, where targets are explicitly designed to be concealed.
Industry relevance: The method is training-free and uses off-the-shelf models, so it can be deployed without annotated camouflage datasets or task-specific retraining. Its reported 17.90 GB GPU memory footprint comes in well below ProMaC (32.85 GB) and RDVP-MSD (31.51 GB), though its 41.96 s per-image latency and heavy reliance on repeated MLLM calls (30.59 s of the total) remain the main practical constraints.
Future Directions
- Improve mask selection reliability. The gap between DSS and the Ideal Seg. upper bound (.737 vs .823 on CAMO, .869 vs .895 on NC4K, .871 vs .892 on COD10K, .852 vs .888 on CHAMELEON) is the paper's own stated motivation for future work.
- Reduce MLLM inference cost. SMS consumes 30.59 s per image and 72.9% of total time; the paper notes the pairwise strategy's cost is the price of its accuracy gain, leaving room for cheaper reasoning schemes.
- Better handling of tiny camouflaged objects, which the authors say they plan to address with multi-scale feature aggregation.
- Extending the selection idea beyond camouflage, since the results suggest the reasoning-based selector is a general mechanism for resolving ambiguity among prompt-derived masks.
Target Audience
Researchers and practitioners in computer vision working on segmentation, zero-shot or training-free inference, and vision-language foundation model pipelines — particularly those interested in camouflaged object detection, prompt engineering for SAM, or using MLLMs as evaluators rather than localizers. It is also relevant to applied engineers in medical imaging, agriculture, autonomous driving, and surveillance who need segmentation without task-specific annotation or training.
Authors’ abstract
Current zero-shot Camouflaged Object Segmentation methods typically employ a two-stage pipeline (discover-then-segment): using MLLMs to obtain visual prompts, followed by SAM segmentation. However, relying solely on MLLMs for camouflaged object discovery often leads to inaccurate localization, false positives, and missed detections. To address these issues, we propose the \textbf{D}iscover-\textbf{S}egment-\textbf{S}elect (\textbf{DSS}) mechanism, a progressive framework designed to refine segmentation step by step. The proposed method contains a Feature-coherent Object Discovery (FOD) module that leverages visual features to generate diverse object proposals, a segmentation module that refines these proposals through SAM segmentation, and a Semantic-driven Mask Selection (SMS) module that employs MLLMs to evaluate and select the optimal segmentation mask from multiple candidates. Without requiring any training or supervision, DSS achieves state-of-the-art performance on multiple COS benchmarks, especially in multiple-instance scenes.