Research
Dating the Model: Hidden Dates in System Prompts Affect LLM Evaluation
Overview Research area: Evaluation methodology and reproducibility for large language models (NLP / benchmarking). Technical level: Intermediate. The experiments are simple to describe, but the paper
- arXiv
- 2609.36931
- Published
- 2026-09-29
- Authors
- Mario Sanz-Guerrero, Minh Duc Bui, Manuel Mager, Katharina von der Wense
AI summary
Overview
Research area: Evaluation methodology and reproducibility for large language models (NLP / benchmarking).
Technical level: Intermediate. The experiments are simple to describe, but the paper assumes familiarity with benchmark metrics (accuracy, pass@1, BLEU, chrF, expected calibration error) and with system prompts and chat templates.
Scope: A systematic study showing that the hidden current date that providers and chat templates inject into the system prompt causes measurable, unintended variation in LLM benchmark scores across nine models, six datasets, and four tasks.
What This Paper Is About
LLM benchmark scores are supposed to be reproducible, yet many providers and chat templates silently prepend today's date to the system prompt, outside the user's control. Because that date changes every day, an evaluation run on Monday and an identical run on Tuesday are not actually identical. The paper's goal is to isolate that one hidden variable, measure how much benchmark results and leaderboard rankings move because of it, and test whether standard prompting techniques can suppress it.
Key Contributions
-
Identification of a new source of evaluation variance. The authors name the hidden, time-varying injection of the current date into system prompts as a distinct factor from previously documented non-determinism such as batch size, numerical precision, hardware, and prompt formatting.
-
Quantification across models, datasets, and tasks. They sweep every date from January 1 to December 31, 2024 across 9 recent LLMs and 6 datasets covering multiple-choice QA, math reasoning, code generation, and machine translation, reporting worst-to-best date deltas for each model and dataset.
-
Comparison against known sources of non-determinism. Using coefficient of variation on Llama 3.1 (8B) on MMLU, they place the date effect alongside batch size, numerical precision, GPU model, option order, and system-prompt wording, and analyze which dates help or hurt.
-
Testing of mitigation strategies. They test chain-of-thought and 5-shot prompting, evaluate proprietary GPT-5.1 over one week, and propose concrete reporting and template-level recommendations.
Main Findings
-
Multiple-choice QA is date-sensitive. Worst-to-best date deltas reach up to 6% in accuracy with only the date changing. Averages across models are 2.30% on MMLU, 3.80% on GPQA, 1.46% on ARC-Challenge, and 2.52% overall. Calibration moves too: ECE deltas reach up to 6.15%, with averages of 2.55% on MMLU, 4.04% on GPQA, 1.56% on ARC-Challenge, and 2.72% overall.
-
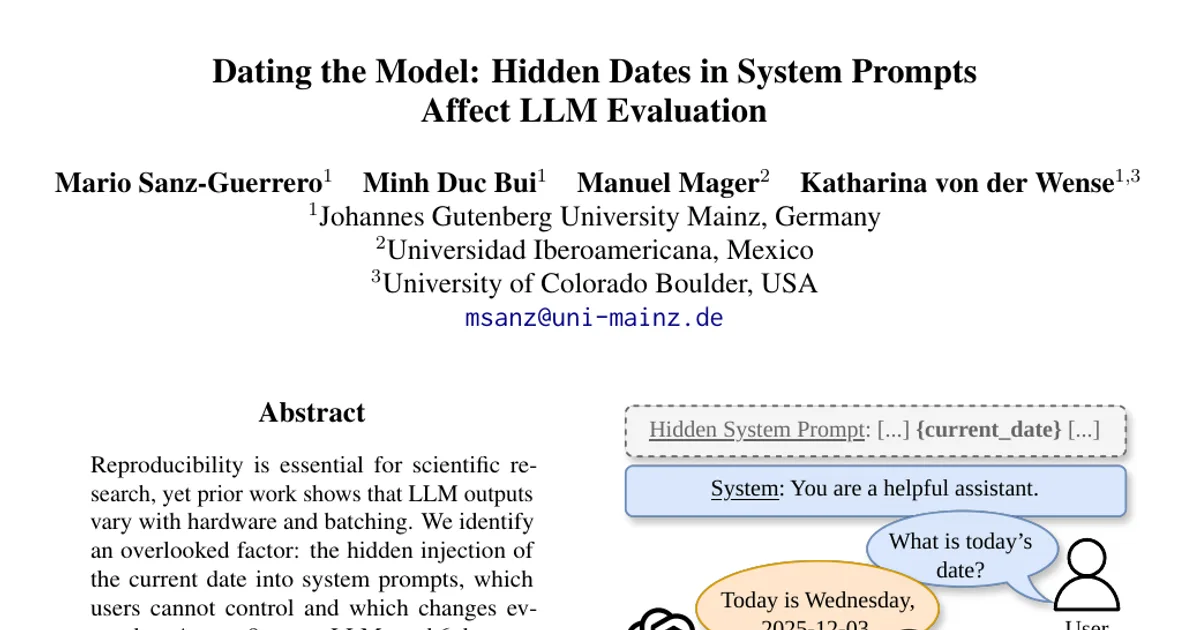
Leaderboards reorder. Changing only the date reshuffles the Top-5 model ranking on MMLU across two consecutive dates (Figure 1(b)).
-
Generation tasks are hit harder. GSM8K accuracy deltas average 7.75% (up to 14.42% for GPT-OSS 120B), larger than MCQA. HumanEval pass@1 deltas average 4.81% (up to 7.32%) even though grading is execution-based against unit tests. Machine translation deltas average up to 1.88 BLEU and 1.33 chrF, with the largest single figure being 2.84 BLEU (GPT-OSS 120B, English to Czech).
-
There is no "good" date. On MCQA, the Spearman correlation between date and accuracy has a median of 0.02 (range −0.40 to 0.53) across 27 model–dataset combinations. Correlations across datasets (median −0.03) and across models (median 0.01) hover near zero, and a date moves both accuracies in the same direction on only 51% of dates, which is chance level. The authors conclude the date acts as noise specific to each model and dataset.
-
The effect reaches proprietary models. GPT-5.1 (checkpoint gpt-5.1-2025-11-13), evaluated over December 3–9, 2025 with an empty system prompt and reasoning disabled, shows variations of up to 4% on GPQA. All 42 runs (7 days × 3 datasets × 2 repetitions) per date were identical, so the variation is attributable to the date.
-
Chain-of-thought amplifies the problem. Rather than grounding the model, CoT on MMLU with Llama 3.1 (8B) increases date sensitivity, because the date shifts the choice of early reasoning tokens and these perturbations cascade through the autoregressive generation.
-
Few-shot prompting does not help. With 5-shot prompting the gaps persist across all models, with an average accuracy delta of 2.27% versus 2.52% zero-shot.
-
The date effect exceeds batch size, precision, and hardware. Coefficient of variation of accuracy on Llama 3.1 (8B) on MMLU: current date 0.78% and ECE 2.56%; batch size 1–128 in powers of 2, 0.61% / 2.00%; numerical precision (BF16, FP16, FP32), 0.52% / 2.54%; GPU model (A100, A40, RTX4090), 0.48% / 1.60%. Option order over 5 random permutations is comparable to the date effect (0.75% / 3.12%).
-
Intentional prompt rewording matters as much as the date. Across six system-prompt wordings, the accuracy CV is 0.78%, identical to the date effect, and the ECE CV is 3.54%. This supports the hypothesis that models are brittle to any system-prompt change, and the date is one such change that happens without the user's knowledge.
-
Uncertain predictions drive the instability. On MMLU, average confidence for predictions that flip with the date is much lower than for stable predictions, for example 41.85% versus 83.71% for Llama 3.1 (8B). Some models stay overconfident even on unstable predictions, such as 88.86% for Gemma 3 (4B). ARC-Challenge deltas are lower because models score higher and are better calibrated there.
-
Without the date, scores fall inside the observed range. When the date is not injected, accuracy and ECE for all models and datasets lie within the range seen across 2024 dates, indicating the date adds variability rather than systematically helping or hurting.
-
Questions are not time-dependent. GPT-OSS (120B) classified 0.0% of questions as time-dependent in every dataset: MMLU (14,042 questions), GPQA (198), ARC-Challenge (1172), GSM8K (1319), HumanEval (164), and WMT English to German (2999), Finnish (6000), and Czech (3003).
-
Other hidden metadata also matters. Preliminary experiments with Llama 3.1 (8B) on MMLU show that varying the user location in the system prompt produces performance differences of comparable magnitude to the date effect, though the authors found no evidence that model version or user location is commonly injected.
Methodology in Plain English
The authors hold everything constant except one thing. For each model and dataset they use identical prompts, identical decoding settings, and a fixed random seed, and they change only the date written in the system prompt. They then repeat the whole evaluation for every day of 2024, which means 365 runs per model per dataset.
They cover four task types to see whether the effect depends on how much text the model generates. Multiple-choice QA is graded by reading the probability of the next answer token, a very small surface for the date to influence. GSM8K requires a full step-by-step solution but is graded on one extracted number. HumanEval requires a complete Python function that is then executed against unit tests, making the metric objective and independent of the output's wording. Machine translation grades the entire generated output with BLEU and chrF.
They verify that no benchmark question depends on the current date, using GPT-OSS (120B) as a classifier. For the proprietary comparison they leave the system prompt empty so the date is injected server-side, and repeat each date twice to confirm the model is deterministic at a fixed date. Finally, they rerun the same setting while varying batch size, numerical precision, GPU model, option order, and system-prompt wording, and compare variation using the coefficient of variation so all sources sit on the same scale.
Why This Matters
Impact on research. If benchmark scores shift by up to 6% on MCQA and 14% on math reasoning purely because of the calendar day, then two papers reporting results on different days may not be comparable, and small reported improvements may be within date noise. The authors recommend removing the date from the chat template while leaving the rest of the template unchanged, or otherwise fixing the date and reporting it alongside results. They also suggest treating confidence and calibration as primary evaluation criteria, since confidence flags which predictions are fragile in a way that accuracy alone does not.
Real-world applications:
- Model leaderboards and model cards: rankings can reorder between two consecutive dates, so published standings may not reflect stable model quality.
- Enterprise model selection and A/B testing: teams comparing two models or two prompt variants on different days can attribute a date artifact to their own change.
- Regulatory and audit reporting: evaluations used to document model behavior need a fixed, disclosed configuration, and the injected date is part of that configuration.
- Benchmark maintainers and API providers: providers who prepend the date server-side, including cases where open-weight models are served through third-party providers, control a hidden variable that their users cannot see or disable.
Industry relevance. The paper shows the effect reaches proprietary models such as GPT-5.1, not just open-weight models with visible chat templates. The Qwen3 example, where the model reports the current date through OpenRouter even with an empty system prompt and no tool use or internet access, shows that a provider can inject the date even when the model's own template does not.
Future Directions
- Broaden model and task coverage. The authors state that their experiments cover a limited set of models and datasets, and that dialogue, summarization, and other open-ended tasks remain to be studied.
- Extend the proprietary evaluation. The GPT-5.1 experiment spans only one week (December 3–9, 2025) and three MCQA datasets; longer and wider evaluations of proprietary models are left open.
- Vary the form of the date injection. Sensitivity to other date formats, other positions in the prompt, and years other than 2024 has not been explored.
- Investigate other hidden metadata. Preliminary results show user location has a comparable effect, raising the question of which other variable, injected metadata fields (the authors cite model version as a candidate they could not find in use) affect evaluations and how they should be reported.
Target Audience
This paper is most useful for benchmark maintainers and evaluation engineers who design and run LLM comparisons, for researchers who report benchmark results and need reproducible protocols, for API providers and inference platform operators who control chat templates and server-side prompt injection, and for reviewers and practitioners who interpret small differences between reported model scores. Readers with basic familiarity with LLM benchmarking will follow it easily; the analysis of calibration, coefficient of variation, and correlation statistics assumes some quantitative background.
Authors’ abstract
Reproducibility is essential for scientific research, yet prior work shows that LLM outputs vary with hardware and batching. We identify an overlooked factor: the hidden injection of the current date into system prompts, which users cannot control and which changes every day. Across 9 recent LLMs and 6 datasets spanning multiple-choice QA (MCQA), math reasoning, code generation, and machine translation, performance varies solely with the current date, with deltas of up to 6% on MCQA, 14% on math reasoning, 7% on code generation, and 2.84 BLEU on machine translation. Model rankings also shift, affecting leaderboards. This date effect exceeds other sources of non-determinism, such as batch size and numerical precision. Standard prompting techniques -- chain-of-thought and few-shot prompting -- do not reduce the sensitivity; chain-of-thought even amplifies it. Our findings underscore the need for careful evaluation protocols to ensure reproducibility and fair comparisons in LLM research.