Research
Building Rome from a Single Image
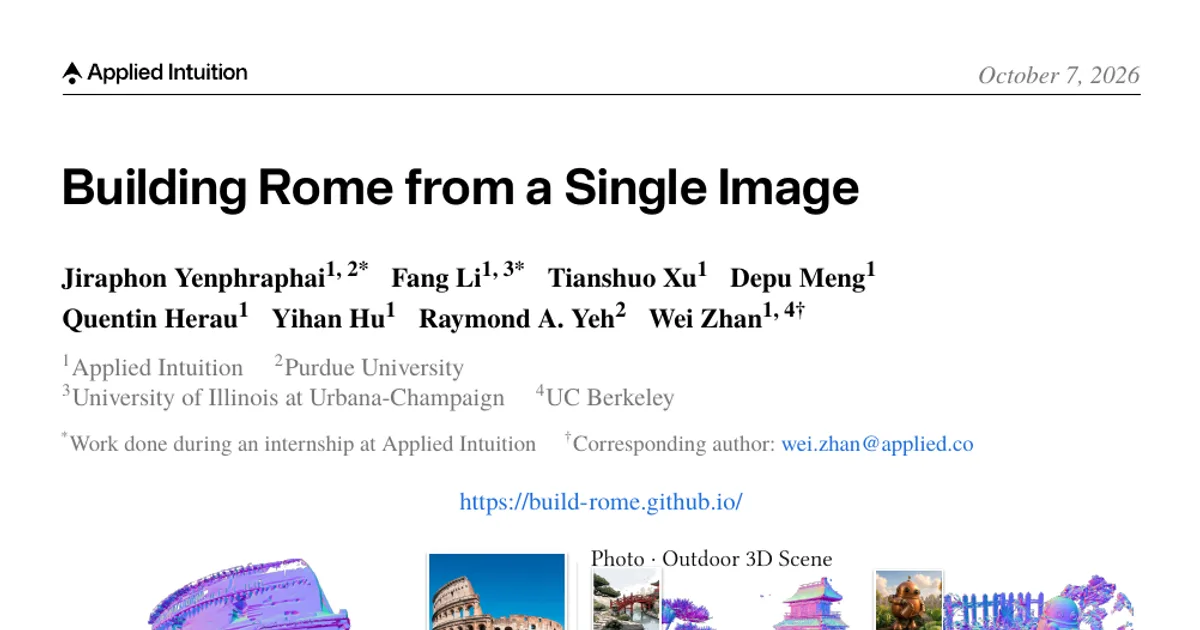
Building Rome from a Single Image Overview Research area: Computer vision and 3D graphics — single-image 3D scene mesh generation (reconstructing visible surfaces and completing geometry hidden behind
- arXiv
- 2610.08790
- Published
- 2026-10-06
- Authors
- Jiraphon Yenphraphai, Fang Li, Tianshuo Xu, Depu Meng, Quentin Herau, Yihan Hu, Raymond A. Yeh, Wei Zhan
AI summary
Building Rome from a Single ImageOverview
Research area: Computer vision and 3D graphics — single-image 3D scene mesh generation (reconstructing visible surfaces and completing geometry hidden behind them). The method builds on the pretrained object generator Trellis 2.
Technical level: Advanced. The paper assumes familiarity with flow-matching generative models, voxel/latent 3D representations, transformer conditioning, and reconstruction metrics such as Chamfer distance and F1.
Scope: One sentence: the paper presents a method that redesigns an object-centric 3D generator into a scene-level generator for both indoor and outdoor scenes by using adaptive spatial chunking, explicit 2D–3D conditioning, and roughly 4,000 synthesized outdoor training scenes.
What This Paper Is About
Producing a full 3D scene mesh from a single photograph means not only recovering the depth and shape of what the camera saw, but also inventing plausible geometry for everything occluded behind it. Pretrained 3D object generators carry a strong shape prior, but they are built for isolated objects inside a fixed canonical volume and are trained mainly on indoor data, because diverse outdoor 3D scene data are scarce. The paper's goal is to adapt such a generator — specifically Trellis 2 — so that it works on both indoor and outdoor scenes of widely varying physical extent while retaining its learned object prior.
Key Contributions
-
Adaptive scene chunks. A chunk-based scene representation whose physical scale changes across the scene: nearby regions use smaller chunks to preserve detail, while farther or taller regions use larger chunks to extend coverage, so one generator trained on a canonical volume can cover scenes of varying extent.
-
Explicit 2D–3D conditioning. A scene mesh generation model that explicitly distinguishes 3D locations supported by the observation from unobserved regions, so reconstruction and generative completion are handled within a unified model — image features are lifted onto the observed surface and each token is told whether it lies in free space in front of the surface, on it, or in the unknown region behind it.
-
Outdoor scene supervision. Roughly 4,000 diverse outdoor scenes are constructed with a synthetic agentic pipeline to create additional training supervision; the model trained on them produces better reconstructions at inference than the scene-generation framework used to create the dataset.
-
Autoregressive scene assembly. Neighboring chunks are generated sequentially while latents in overlapping regions are copied and re-imposed at every denoising step, so overlapping chunks agree by construction; across depth regions with different latent cell sizes, the previous region's latents are trilinearly resampled within the overlap.
Main Findings
-
Best results across every metric and dataset. On Tanks and Temples, ScanNet++ and 121 in-the-wild images, the method outperforms all baselines on every metric and in the user study. On Tanks and Temples it achieves CD 1.99 and F1 0.506, versus the strongest baseline on each metric (VolFill at CD 2.63; Lyra 2.0 at F1 0.388) — a 24% reduction in Chamfer distance and a 30% improvement in F1.
-
ScanNet++ and in-the-wild numbers. ScanNet++: CD 5.01, F1 0.702 (best baselines: CD 5.21, F1 0.690). In-the-wild: DreamSim 0.221, CLIP-N 0.870 (best baselines: DreamSim 0.237, CLIP-N 0.859).
-
User study preference. On in-the-wild images, the method is preferred over every baseline in at least 73% of pairwise blind comparisons (baseline win rates listed range from 73.0% to 94.4%).
-
Adaptive chunking beats fixed-size chunking and runs faster. In the chunking ablation, adaptive chunking gives indoor CD 2.86 / F1 0.792 and outdoor CD 37.4 / F1 0.240, versus fixed 3 m chunks at indoor 3.13 / 0.782 and outdoor 38.5 / 0.100 — and adaptive chunking runs three times faster (5 minutes versus 15 minutes). A single chunk is competitive indoors (2.87 / 0.759) but fails outdoors (CD 49.9, F1 0.138).
-
Explicit conditioning beats implicit alternatives. The full conditioning gives indoor CD 3.54 / F1 0.793 and outdoor CD 6.90 / F1 0.501, compared with SAM 3D-style conditioning (4.38 / 0.707 indoor; 8.30 / 0.257 outdoor), projection-only conditioning (4.74 / 0.739; 8.26 / 0.330), and the variant without visibility (4.24 / 0.757; 6.60 / 0.464).
-
Outdoor data helps without hurting indoor quality. Training on existing data alone gives indoor CD 3.99 / F1 0.784 and outdoor CD 10.75 / F1 0.317; adding the synthesized outdoor data improves both to 3.54 / 0.793 indoor and 6.90 / 0.501 outdoor, with the larger gain outdoors.
-
Baseline failure modes. GenRecon often imposes a room-like prior on outdoor scenes; World Tracing leaves holes under heavy occlusion; Lyra 2.0 can produce visually plausible renders whose underlying geometry is inaccurate, leading to floating geometry after reconstruction; VolFill shows line-like surface artifacts and often fails outdoors.
-
Large-scene efficiency. For a scene extending 280 m in depth and 10 m in height, fixed-size chunks at uniform scale would require roughly 200 chunks and exceed an 80 GB GPU's memory, whereas the adaptive strategy uses four depth regions and 15 chunks in about 5 minutes, with peak GPU memory of 26 GB (a single chunk needs roughly 8 GB).
Methodology in Plain English
The team started from Trellis 2, an image-conditioned 3D asset generator that represents geometry with O-Voxels and generates through two flow-matching stages: a sparse-structure stage that predicts active voxel locations, then a structured-latent stage that predicts geometry latents decoded into a mesh. Both stages operate inside a normalized canonical volume, and the model was trained to place centered objects there — so used directly on a scene, it would collapse everything to the origin with the wrong layout.
To fix the scale problem, the scene is split into adaptive chunks. Depth regions are defined along the camera-forward axis, and every chunk inside region i shares a scale factor a_i; the model always sees a canonical chunk of side length L = 3 m, while the physical extent is a_iL. Geometry, depth values and camera translation are divided by a_i while intrinsics stay unchanged, so projections are preserved and one model handles many physical resolutions. Chunk size starts at the smallest value wherever the observed height permits, doubles with each successive depth row (6, 12, 24 m, and so on), and is increased further if a region's 99th-percentile height exceeds 2.8 m. Adjacent chunks overlap by 0.5 m in canonical space, giving a physical overlap of 0.5·a_i m.
To keep generated geometry faithful to the image, the authors use a monocular point map estimated from the input (MoGe-3 at inference) and condition each 3D token through 2D–3D projection. Image features come from DINOv3 and are "lifted" onto a voxel only when the voxel center is close to the observed surface along its viewing ray, using a depth residual tolerance τ set to 1.5 voxel widths — 0.28 m for the sparse-structure stage and 0.07 m for the structured-latent stage. A clipped signed depth residual (clamped to ±1 m), Fourier-encoded with 64 fixed frequencies into a 128-dimensional embedding and passed through an MLP, tells the sparse-structure model whether a location is in free space in front of the surface, on the surface, or behind it. These conditioning signals are added to the transformer hidden states before each block via learned linear projections; the structured-latent stage uses only the lifted-image term.
For training data, the authors use SAGE-10k (10,000 indoor scenes generated with each of Infinigen 1.0 and 2.0), rendering 16 views at 1024×1024 with Blender and discarding objects occupying fewer than 80 pixels. To cover outdoors, they build an agentic pipeline: GPT-5.6 writes scene prompts, Ideogram 4 renders reference images, a VLM identifies object types, dimensions and spatial relations, objects are cropped, completed with Nano Banana and converted to meshes with Trellis 2, a layout solver converts relations into poses while rejecting collisions, and ground geometry combines monocular guidance with procedural height fields. This yields roughly 4,000 outdoor scenes; even though the assembled scenes are imperfect, training on them improves the model.
Training is done on individual canonical chunks to save memory: rank-32 LoRA adapters plus the new conditioning modules are optimized for 100K steps with AdamW on 16 NVIDIA A100 GPUs at batch size 64, using learning rates of 1×10⁻⁴ for the conditioning modules and 3×10⁻⁵ for LoRA. Ground-truth depth and camera parameters are used during training; monocular estimates replace them at inference. At generation time, chunks are produced sequentially from near to far, latents in already-covered regions are copied into new chunks and re-imposed at every denoising step, and the assembled latents are decoded into the full scene mesh.
Evaluation uses 7 scenes from Tanks and Temples, 32 randomly selected ScanNet++ scenes, and 121 in-the-wild images (53 indoor, 68 outdoor). Geometry is scored with Chamfer distance normalized by median ground-truth depth and F1 at a 10 cm threshold after ICP alignment; image consistency is scored with DreamSim and CLIP-N, the latter comparing rendered normal maps from four viewpoints against normals estimated with Lotus2. Seven baselines are compared across four categories: EvoScene and Extend3D (iterative 3D completion), 3D-RE-GEN (object composition), Lyra 2.0 (generated video then reconstruction), and VolFill, GenRecon and World Tracing (direct scene reconstruction).
Why This Matters
The work shows that a generative prior learned on isolated objects can be repurposed for whole scenes of indoor and outdoor scale without retraining a scene prior from scratch — a route to scene generation that sidesteps the scarcity of diverse 3D scene data. It also demonstrates that imperfect synthetic supervision can still improve a model, which is relevant to any domain where clean ground truth is expensive.
Real-world applications (from the paper):
- Content creation
- Virtual reality
- Robotics, including use in physics simulators for robot navigation and interaction
- World models that turn a single image into an explorable 3D world
Industry relevance: The pipeline's cost profile matters for deployment — adaptive chunking cuts inference on a large scene to about 5 minutes with 26 GB peak GPU memory, versus roughly 200 chunks and out-of-memory on an 80 GB A100 for fixed-size chunking. The paper also notes this generation could scale up robot learning by reducing the need for extensive real-world capture.
Future Directions
- Producing textured outputs, for example through 3D Gaussian splatting, since the current method generates geometry without textures.
- Recovering finer geometric detail.
- Supporting more than one input image rather than a single conditioning image.
- Addressing the stated limitations: Trellis 2 does not guarantee watertight meshes and the model inherits this, occasionally producing holes that need extra mesh processing; the method depends on estimated depth and camera intrinsics whose errors affect chunk placement, scene scale and feature alignment; and autoregressive generation can propagate errors from earlier chunks to later ones through the reused overlap latents.
Target Audience
Researchers and practitioners in 3D computer vision, generative modeling and graphics who work on single-image reconstruction, scene completion, or feedforward 3D asset generation; engineers building content-creation, VR, robotics-simulation or world-model pipelines that need scene meshes from photographs; and readers already comfortable with latent 3D representations, flow-matching models and transformer conditioning, since the technical detail (O-Voxels, LoRA adaptation, Fourier-encoded depth residuals) assumes that background.
Authors’ abstract
Single-image scene generation aims to produce a complete 3D scene mesh from a single image, including surfaces the camera did not observe. While pretrained 3D object generators encode a strong shape prior, they are mainly designed for isolated objects in a fixed canonical volume and focus mostly on indoor scenes, since diverse 3D data for outdoor scenes are quite limited. In this work, we present a method that redesigns such an object-centric generator, e.g., Trellis 2, to work on both indoor and outdoor scenes while retaining its prior. We accomplish this by (a) partitioning the scene into adaptive chunks that scale relative to the distance to the camera; nearby chunks have a smaller size to keep the finer detail, while distant structures, e.g., buildings, are covered by large chunks; (b) making the generator capture explicit 2D-3D correspondence by lifting image features and making the model aware of the free space, observed surface, and unobserved region; (c) synthesizing around 4,000 outdoor scenes to broaden the training data, as existing scene datasets are largely indoor. Experiments on Tanks and Temples, ScanNet++, and in-the-wild images show that our method outperforms all baselines in geometric accuracy and perceptual quality across both indoor and outdoor scenes.