tools
Text Generation Inference (TGI) Review 2026 — HuggingFace LLM Server
TGI by HuggingFace is the production LLM serving engine powering the HuggingFace Inference API. Open-source, Docker deployment, OpenAI-compatible, enterprise metrics.
In inglese
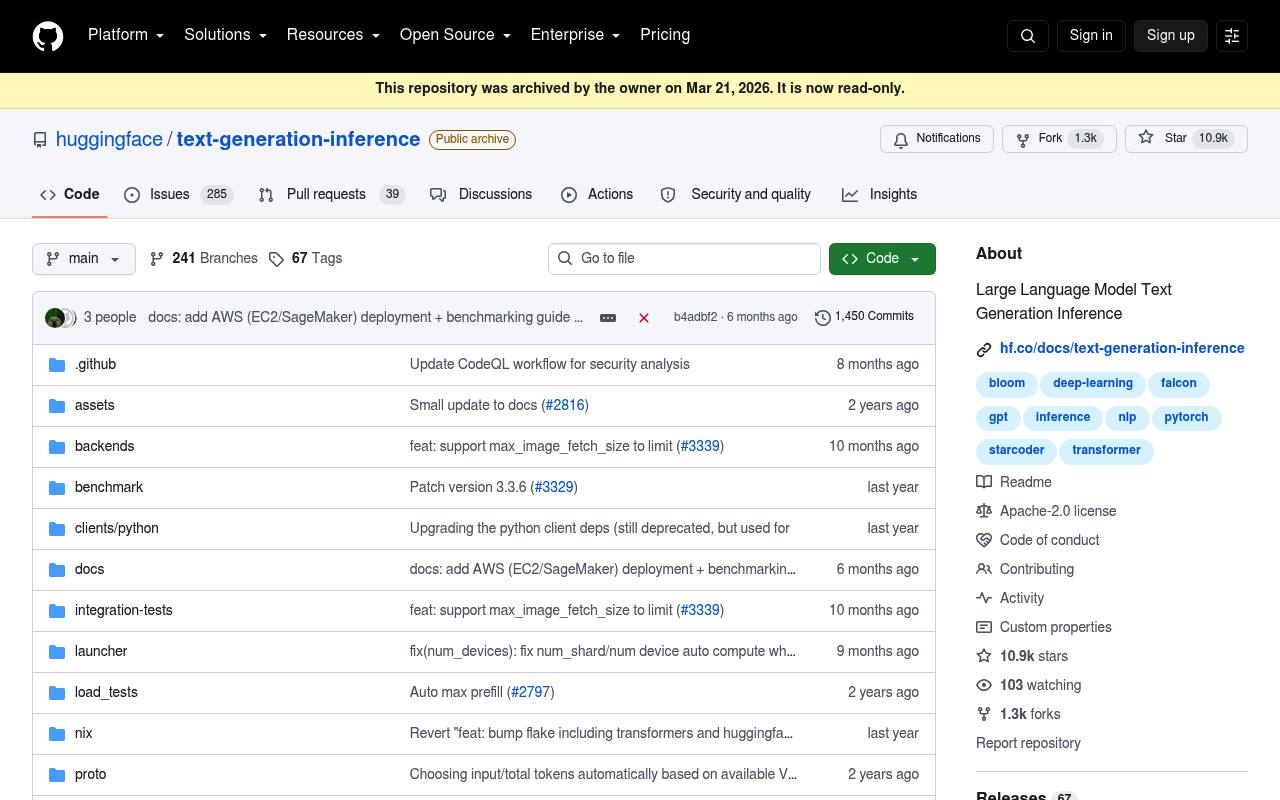
Text Generation Inference (TGI) is a Rust, Python, and gRPC server for deploying and serving large language models. It provides REST and Messages APIs, token streaming, continuous batching, tensor parallelism, tracing, metrics, and quantization support.
It is used by developers and infrastructure teams running models on local or cloud GPU systems. The repository is archived and in maintenance mode; Hugging Face recommends newer inference engines such as vLLM and SGLang. Hosting costs, including compute and GPUs, are separate.
Features
- Serves popular open-source language models through a simple launcher
- Streams generated tokens using Server-Sent Events
- Batches incoming requests continuously to improve throughput
- Runs tensor-parallel inference across multiple GPUs
- Provides Messages API compatibility with OpenAI Chat Completions
- Supports distributed tracing with OpenTelemetry and Prometheus metrics
- Supports quantization with bitsandbytes, GPTQ, AWQ, Marlin, EETQ, and FP8
- Licensed under Apache-2.0
Use cases
- Deploy language models behind a production HTTP API
- Serve gated Hugging Face models with an access token
- Run batched text generation on multi-GPU infrastructure
- Stream model responses to chat or completion applications
- Reduce GPU memory use with quantized model weights
- Trace and monitor inference workloads in distributed systems
Pros
Cons
Latest updates
- v3.3.7 (v3.3.7)
Added support for max_image_fetch_size and announced maintenance mode.
- v3.3.5 (v3.3.5)
Added Gemma 3 sliding-window support and XPU LoRA support.
- v3.3.4 (v3.3.4)
Added initial Gaudi support for Gemma 3 text and VLM models.
- v3.3.3 (v3.3.3)
Enabled the Qwen3 MoE model on Gaudi.
- v3.3.2 (v3.3.2)
Added Qwen3 and FP8 compressed-tensors W8A8 support.
Capabilities
- Command line — “To see all options to serve your models (in the code or in the cli): text-generation-launcher --help” source
- Choice of models — “text-generation-launcher --model-id mistralai/Mistral-7B-Instruct-v0.2” source
- Self-hosted — “You can also opt to install text-generation-inference locally.” source
- API — “You can consult the OpenAPI documentation of the text-generation-inference REST API using the /docs route.” source
- Runs models for you — “Text Generation Inference (TGI) is a toolkit for deploying and serving Large Language Models (LLMs).” source
- Traces and evaluates — “Production ready (distributed tracing with Open Telemetry, Prometheus metrics)” source
Get it
Pricing
- Starting price
- $4/user/mo
- Prices checked
- 2026-09-25
Free
Free
- Unlimited public/private repositories
- Dependabot security and version updates
- 2,000 CI/CD minutes/month
- 500MB of Packages storage
- Issues & Projects
- Community support
Team
- $4 USD per user/month
- Access to GitHub Codespaces
- Repository rules
- Multiple reviewers in pull requests
- Draft pull requests
- Code owners
- 3,000 CI/CD minutes/month
Enterprise
- Starting at $21 USD per user/month
- Data residency
- Enterprise Managed Users
- User provisioning through SCIM
- Enterprise account to centrally manage multiple organizations
- Environment protection rules
- Audit Log API