tools
Lambda 1-Click Clusters
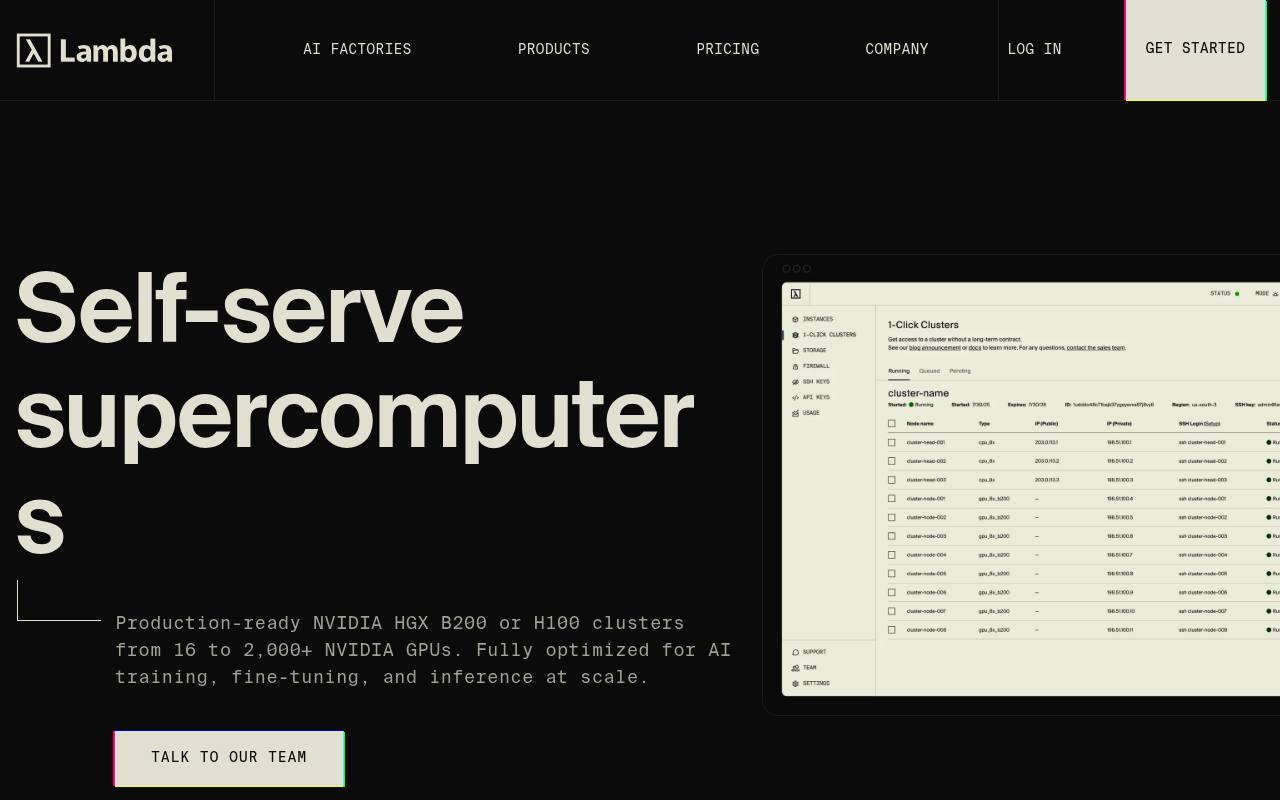
Lambda 1-Click Clusters provides dedicated, InfiniBand-connected GPU clusters for distributed AI training, fine-tuning, and inference.
In inglese
Lambda 1-Click Clusters are managed multi-node GPU clusters built with NVIDIA HGX B200 or H100 systems. They include InfiniBand networking, CPU management nodes, local NVMe storage, Lambda Stack software, and access through the Lambda Cloud dashboard, SSH, or JupyterLab.
AI researchers, engineers, and enterprise teams use them for large-scale training, fine-tuning, inference, and proof-of-concept workloads. GPU time is billed per GPU per hour; filesystem storage is billed separately, and applicable sales taxes may apply.
Features
- NVIDIA HGX B200 and H100 GPU clusters
- 16 to 2,000+ NVIDIA GPUs
- NVIDIA Quantum-2 InfiniBand networking
- Managed Kubernetes or Slurm orchestration
- S3-compatible storage
- Preinstalled Lambda Stack with PyTorch, TensorFlow, NCCL, and Open MPI
- SSH and JupyterLab access
- ISO 27001, 27017, 27701, 22301, and SOC 2 Type II compliance
Use cases
- Train large language and multimodal models across multiple GPU nodes
- Fine-tune models with distributed PyTorch or TensorFlow workloads
- Run large-scale inference deployments
- Benchmark new GPU architectures and distributed training systems
- Prototype production AI workloads with short-term reservations
Pros
Cons
Get it
Security
Pricing
- Prices checked
- 2026-09-24
NVIDIA HGX B200 — 16 GPUs
- $9.86 per GPU/hr
- 2 weeks – 1 year
- 16 GPUs
NVIDIA HGX B200 — 64 GPUs
- $9.36 per GPU/hr
- 2 weeks – 1 year
- 64 GPUs
NVIDIA HGX B200 — 256+ GPUs
- $8.87 per GPU/hr
- 2 weeks – 1 year
- 256+ GPUs
NVIDIA H100 — 16 GPUs
- $6.16 per GPU/hr
- 2 weeks – 1 year
- 16 GPUs
NVIDIA H100 — 64 GPUs
- $5.85 per GPU/hr
- 2 weeks – 1 year
- 64 GPUs
NVIDIA H100 — 256 GPUs
- $5.54 per GPU/hr
- 2 weeks – 1 year
- 256 GPUs