events
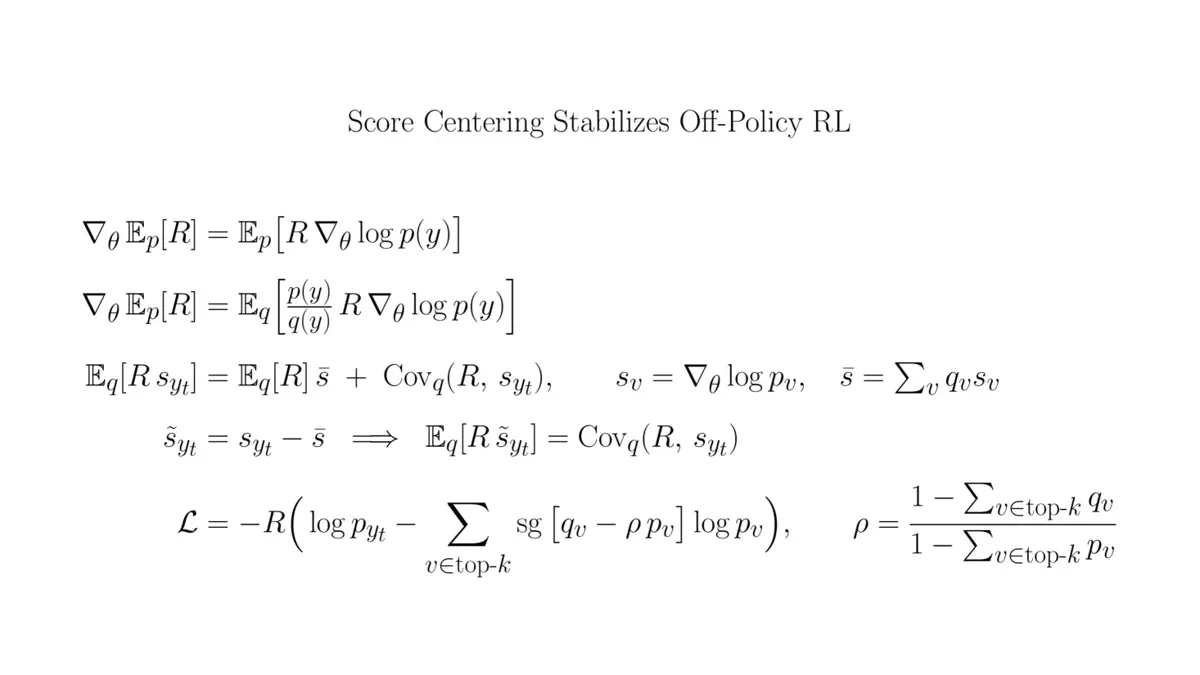
Cosmin goes over Score Centering Stabilizes Off-policy Reinforcement Learning
The Deep Learning Study Group in San Francisco holds an online session in which Cosmin walks through the paper "Score Centering Stabilizes Off-policy Reinforcement Learning," a method used in a…
Auf Englisch
- Starts
- 2026-10-28 01:30 UTC
- Organizer
- Deep Learning Study Group (San Francisco)
- Location
- Online event
The Deep Learning Study Group in San Francisco holds an online session in which Cosmin walks through the paper "Score Centering Stabilizes Off-policy Reinforcement Learning," a method used in a recent update to the Thinking Machines RL platform. The session connects the paper to the Thinker StableReinforce objective and points to further reading on KL approximation and related work. It is a paper-reading discussion for people who follow reinforcement learning research and how it is implemented in training platforms.
Event website